
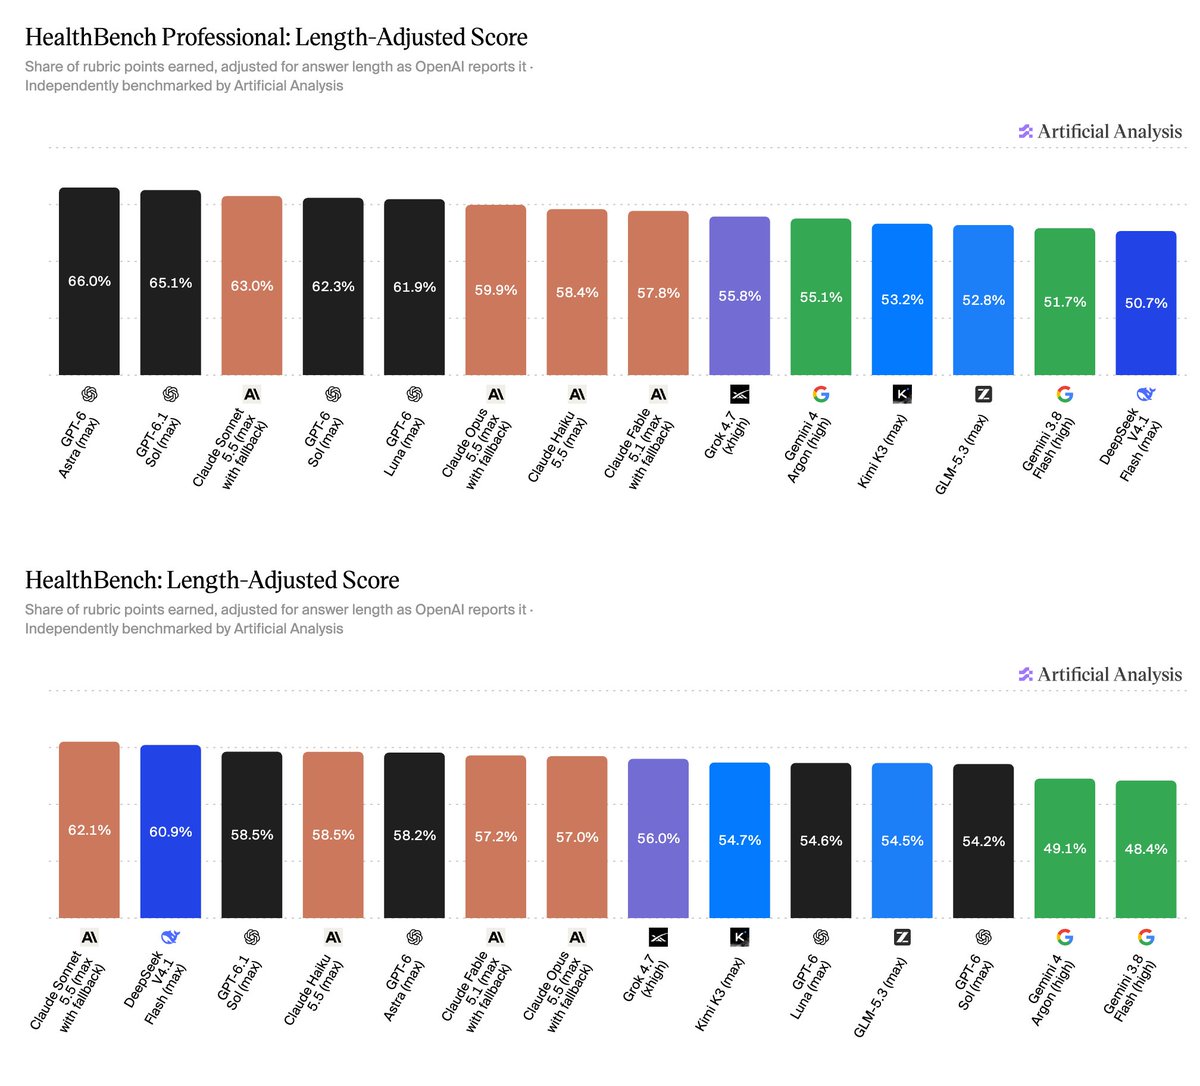
Independent AI evaluation authority Artificial Analysis launched the HealthBench and HealthBench Professional clinical reasoning and medical conversation leaderboards. Addressing the critical flaw where models artificially inflate medical scores through exhaustive, padded responses, the Professional benchmark implements rigorous length penalties. GPT-6 Astra (max effort) leads the world at 66.0%, with GPT-6.1 Sol at 65.1% and Claude Sonnet 5.5 at 63.0%. Claude Opus 5.5, despite holding a 71.4% raw score, collapses to 59.9% (#6) due to averaging ~5,900 characters per reply.
Key Takeaways
- ✓Artificial Analysis launched HealthBench, introducing strict length penalties on the Professional leaderboard to penalize verbose medical answers
- ✓GPT-6 Astra took #1 with 66.0%, followed by GPT-6.1 Sol at 65.1% and Claude Sonnet 5.5 at 63.0%
- ✓Claude Opus 5.5 scored 71.4% raw, but dropped to 59.9% (#6) under length penalties due to averaging ~5,900 characters per reply
- ✓On standard HealthBench, DeepSeek V4.1 Flash took #2 with 60.9%, outperforming multiple frontier commercial models
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background and the Problem
Clinical consultation and medical decision support represent high-stakes domains demanding absolute factual integrity, rigorous diagnostic reasoning, and concise communication. Existing benchmarks (such as MedQA) rely primarily on multiple-choice questions, failing to reflect multi-turn clinical dialogue. Crucially, open-ended medical evaluations have suffered from models "gaming" evaluation metrics by outputting thousands of characters of generic disclaimers and encyclopedic fluff to obscure ambiguous diagnostic claims. In real-world emergency care, verbose outputs cost critical clinical time. Artificial Analysis introduced HealthBench and HealthBench Professional to measure medical conversational intelligence under strict verbosity constraints.
Architecture and How It Works
- Multi-Turn Clinical Scenario Simulation:
- Spans hundreds of medical dialogues encompassing emergency differential diagnosis, chronic medication conflict analysis, and rare disease reasoning;
- Strict Length Penalty for Redundant Verbosity:
- HealthBench Professional enforces an information-density length penalty. Models must present evidence-based clinical reasoning succinctly; padding answers with boilerplate disclaimers incurs steep penalties;
- Independent Third-Party Verification:
- Evaluated independently via standardized API calls, verified against physician gold standards.
Benchmarks and Measured Results
According to official Artificial Analysis leaderboard telemetry (Figure 1, HealthBench Disclosures):
- HealthBench Professional (Length-Penalized):
- GPT-6 Astra (Max Effort) secures #1 globally with 66.0%;
- GPT-6.1 Sol (Max Effort) claims #2 at 65.1%;
- Claude Sonnet 5.5 demonstrates remarkable conciseness and diagnostic accuracy, placing #3 at 63.0%;
- The Opus Verbosity Penalty: Claude Opus 5.5 logged the highest raw unpenalized score at 71.4%, but because its answers averaged ~5,900 characters, the length penalty dropped it to 59.9% (#6 overall);
- HealthBench Standard:
- Claude Sonnet 5.5 leads at 62.1%;
- DeepSeek V4.1 Flash takes #2 at 60.9%, outperforming larger proprietary models;
- GPT-6.1 Sol secures #3 at 58.5%.
Getting Started for Developers
- Leaderboard Access: Accessible at
artificialanalysis.ai; - Engineering Recommendation for Healthcare AI: This benchmark proves that in clinical AI systems, information density trumps verbose disclaimers. Engineers building hospital triage systems or physician assistants should enforce strict character limits and structured output schemas in system prompts, prioritizing immediate differential diagnoses over filler prose.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.