

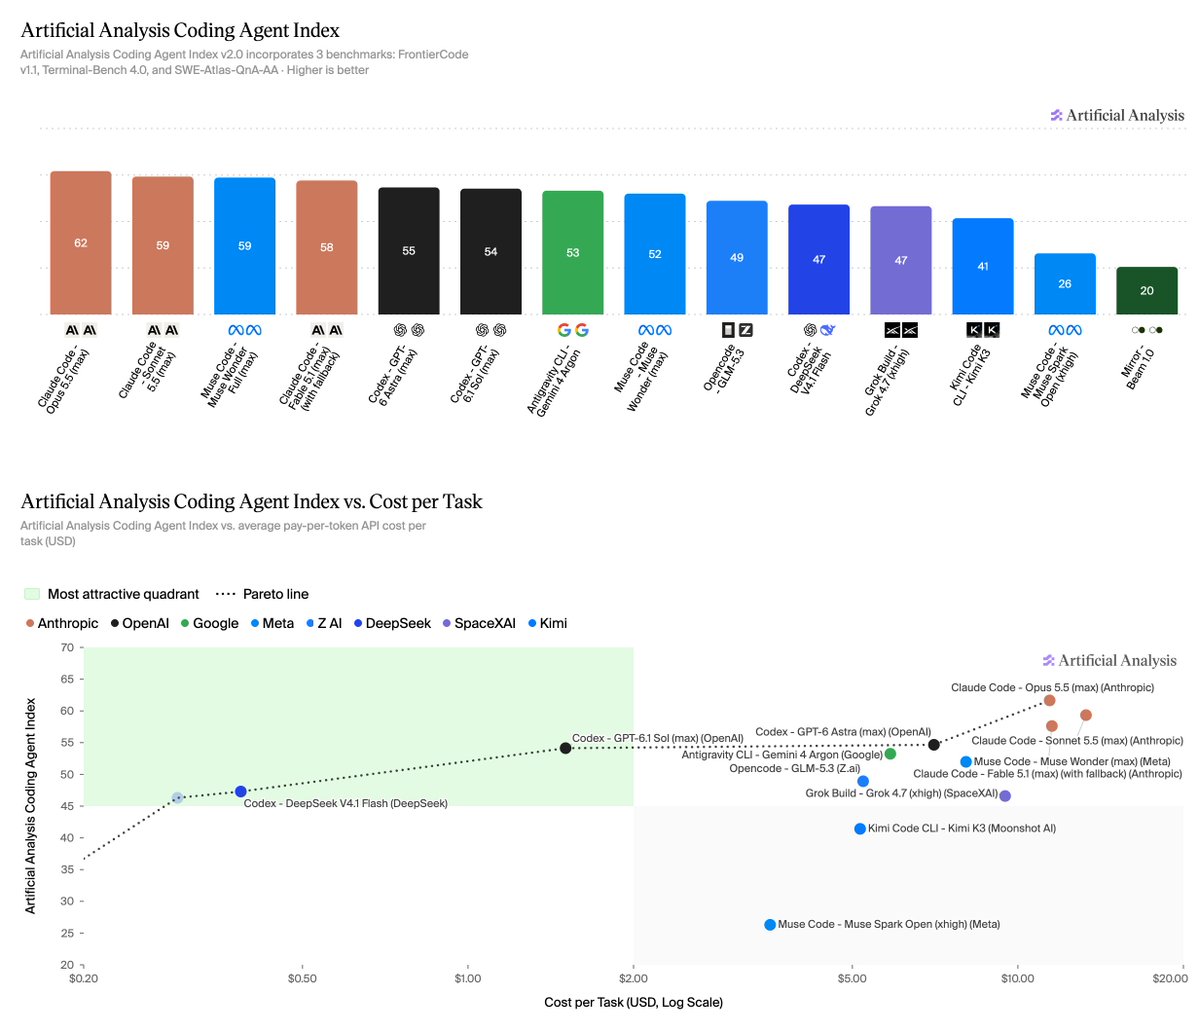
On 2026-10-23 Artificial Analysis launched Coding Agent Index v2.0, which scores model-plus-harness combinations across 290 tasks with three equally weighted benchmarks: FrontierCode v1.1 from Cognition (100 tasks on real open-source repos, graded on whether a maintainer would merge the change) replaces DeepSWE v1.1, SWE-Atlas-QnA becomes the stricter SWE-Atlas-QnA-AA, and Terminal-Bench 4.0 is unchanged. Claude Code with Claude Opus 5.5 (max) leads at 61.7, ahead of Sonnet 5.5 at 59.3 and Muse Wonder Full at 58.9. Scores fall across the board: the 21 configurations measured on both versions drop from a mean of 54.8 to 47.4.
Key Takeaways
- ✓Top of the index: Claude Code with Claude Opus 5.5 (max) 61.7, Claude Sonnet 5.5 (max) 59.3, Muse Code with Muse Wonder Full (max) 58.9, Claude Fable 5.1 (max with fallback) 57.6 (Artificial Analysis figures)
- ✓On FrontierCode v1.1, Opus 5.5 scores 56.0%, ahead of Codex with DeepSeek V4.1 Flash at 52.6%; 15 of 24 configurations sit between 43% and 49%
- ✓Version shift: 21 configurations average 54.8 on v1.5 and 47.4 on v2.0, with 20 of 21 moving down; the same set averages 45.1% on FrontierCode versus 65.6% on DeepSWE
- ✓Four points on the cost frontier: DeepSeek V4.1 Flash 47.3 at $0.39 per task, GPT-6.1 Sol 54.1 at $1.50, GPT-6 Astra 54.7 at $7.04, Opus 5.5 61.7 at $11.42 (pay-per-token API costs, not subscriptions)
- ✓SWE-Atlas-QnA-AA rewords 127 of 1,306 rubric criteria and uses GPT-6 Luna (xhigh) as judge with five votes per criterion; dataset and judge config are on Hugging Face
Key Decision Metrics at a Glance
Heavy Claude Code use: compare subscription limits and API bills
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background and the problem
A coding agent's results depend on the harness (Claude Code, Codex, Muse Code and others) as well as the model, so Artificial Analysis scores each model-plus-harness pair as its own row. In v1.5, top configurations were already above 65% on DeepSWE v1.1, which made it less useful for telling them apart. Version 2.0 swaps in a harder software engineering benchmark that is closer to real merge standards.
How the index works
Version 2.0 averages three equally weighted benchmarks over 290 tasks: FrontierCode v1.1 from Cognition (100 tasks, private test set), Terminal-Bench 4.0 (66 terminal tasks, unchanged) and SWE-Atlas-QnA-AA (Scale AI's 124 repository Q&A tasks). FrontierCode grades whether a maintainer would merge the change: any failed blocking check scores zero, and passing all of them earns 70% to 100% depending on non-blocking checks. Agents have internet access, but a trajectory scan zeroes any attempt that fetched the upstream pull request, merge commit or a mirror. SWE-Atlas-QnA-AA rewords 127 rubric criteria and uses GPT-6 Luna (xhigh) as judge with five votes per criterion. Each task is run three times and averaged.
Benchmark results
All figures are from Artificial Analysis. Overall: Claude Code with Opus 5.5 (max) 61.7, Sonnet 5.5 (max) 59.3, Muse Wonder Full (max) 58.9, Fable 5.1 57.6. FrontierCode alone: Opus 5.5 56.0%, Codex with DeepSeek V4.1 Flash 52.6%, GPT-6.1 Sol 49.4%, GPT-6 Astra 49.3%. The index got harder: 21 configurations fell from a mean of 54.8 to 47.4, and 20 of them moved down. On the cost frontier, DeepSeek V4.1 Flash scores 47.3 at $0.39 per task, while Opus 5.5 scores 61.7 at $11.42.
What developers can do
Don't pick on the headline score alone. For high-volume or budget work, try Codex with DeepSeek V4.1 Flash or GPT-6.1 Sol first, and move to Opus 5.5 when merge quality matters most. Scores on v2.0 are not comparable with v1.5, so check the version before comparing older articles. Per-benchmark scores, cost per task and token usage are on the Artificial Analysis coding agents page, and the SWE-Atlas-QnA-AA dataset can be downloaded from Hugging Face for your own runs.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.