AI Coding Live News

Cartesia launches Managed Agents voice agent platform: #1 of 30 on Speech Agent Arena, $0.03 per minute at launch

Voice model company Cartesia launched Managed Agents on Oct 29, an end-to-end voice agent platform for enterprise phone calls that tunes its own speech-to-text and text-to-speech models together with the agent harness, and bundles telephony, knowledge bases, tool calls and outbound batches. Cartesia says it ranks #1 on Artificial Analysis's Speech Agent Arena with a 1115 Elo and scores 87.4% accuracy and 90.7% experience on ServiceNow's EVA-Bench (vendor-reported, with GPT-5.5 as the reasoning model). Launch pricing is 50% off at $0.03 per minute.

Cartesia launches Managed Agents voice agent platform: #1 of 30 on Speech Agent Arena, $0.03 per minute at launch

Key Takeaways

  • On Artificial Analysis's Speech Agent Arena blind preference test, Managed Agents ranks #1 of 30 agents with a 1115 Elo, ahead of Gemini 3.1 Flash Live Minimal (1099), Grok Voice 3.0 (1064) and GPT-Live-1 (1041) (Cartesia blog, as cited by the vendor)
  • First-attempt results on ServiceNow EVA-Bench across 200+ customer service, IT service and HR scenarios: 87.4% accuracy and 90.7% experience, versus 73.7%/71.2% for Grok Voice 3.0 and 59.0%/61.6% for GPT Realtime 2.1 (EVA-Bench)
  • All these benchmark runs use GPT-5.5 as the reasoning model; Cartesia's internal evaluation says 85% of calls had no turn-taking issues, versus 67% for other agents
  • Launch pricing is 50% off at $0.03 per minute; Cartesia says the platform has already handled tens of millions of conversations in finance, retail, hospitality and healthcare
  • It supports 44 languages; English, Spanish, Hindi, French and Japanese can switch mid-call today, with the rest coming soon
Read full story

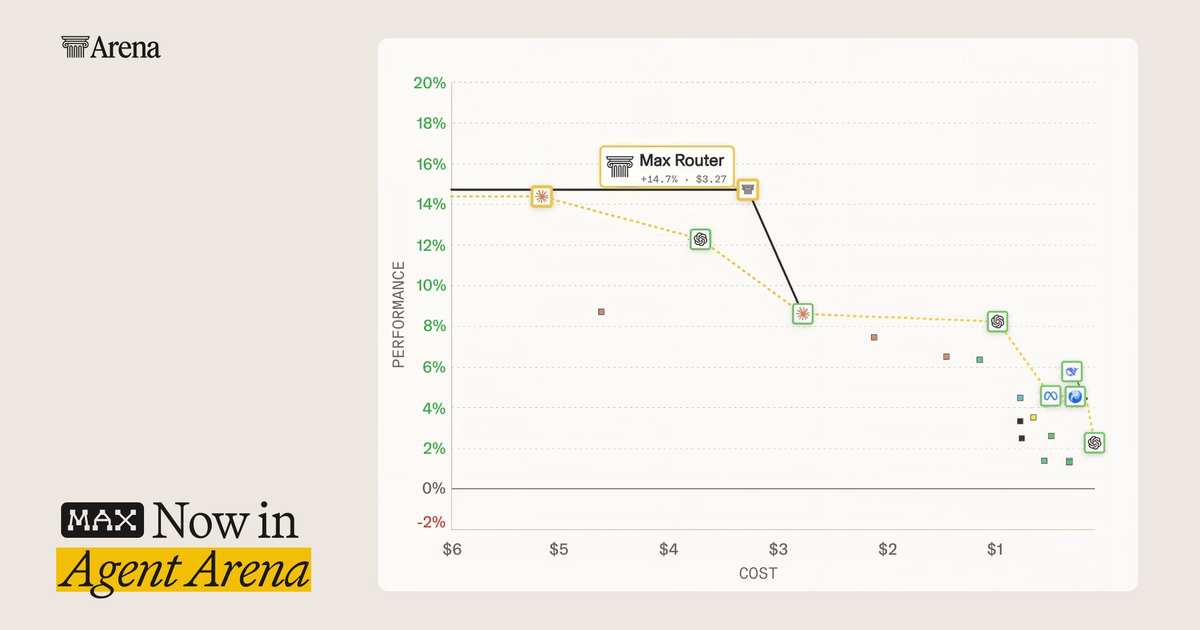
Arena's agentic Max router, trained on 2.5M Agent Arena sessions, tops Agent Arena at a $3.27 median task cost — 37.5% below Fable 5.1 (Max)

Arena released an agentic version of its Max router. Trained on 2.5M+ real Agent Arena sessions, it picks between Fable 5.1 (Max), Astra (Max) and Astra (Medium) per task based on complexity, task type and cost. In a live test it ranked #1 in Agent Arena with a +14.7% score at a $3.27 median cost per task — 0.3% better than the top public model, Fable 5.1 (Max), at 37.5% lower cost — and sent 67% of coding sessions to the cheaper Astra (Medium). It is free to try in Agent Mode for a limited time; API access is via a signup form.

Arena's agentic Max router, trained on 2.5M Agent Arena sessions, tops Agent Arena at a $3.27 median task cost — 37.5% below Fable 5.1 (Max)

Key Takeaways

  • Training data: 2.5M+ real Agent Arena sessions; Arena tested 60+ agentic models over the past 4 months
  • Live test: #1 in Agent Arena with +14.7% score and a $3.27 median cost per task — 0.3% above Fable 5.1 (Max) at 37.5% lower cost
  • Routing mix: code 67% → Astra (Medium); chat Astra (Max) 49% / Fable 5.1 (Max) 42%; work Fable 5.1 (Max) 49% / Astra (Medium) 43%
  • Model-agnostic: an earlier Fable 5 + Kimi K3 router hit +10.7% net at a $1.06 median cost, 0.6 pp above Fable 5 (High) at 54% lower cost
  • Caveats: trained on data collected before Sept 17 (pre-Opus 5.5); Agent Mode only for now, API via signup
Read full story

Artificial Analysis: Gemini 3.8 Live Extended Thinking tops Speech to Speech Index at 82.6

Artificial Analysis (@ArtificialAnlys) updated its Speech to Speech Index: Google Gemini 3.8 Live Extended Thinking (High) debuts at #1 with 82.6, ahead of GPT-Live-1 (Astra medium) at 81.5 and Grok Voice Think Fast 2.0 High at 81.3; standard Gemini 3.8 Live lands #5 at 76.0. The same drop covers Speech Agent Arena, Tau Voice (Extended Thinking leads at 68.6%), Big Bench Audio, time-to-first-audio, and input-audio cost ($0.84/hr standard, $3.50/hr Extended Thinking).

Key Takeaways

  • Gemini 3.8 Live Extended Thinking (High) leads Speech to Speech Index at 82.6, above GPT-Live-1 Astra at 81.5.
  • On Tau Voice, Extended Thinking leads at 68.6%; standard Gemini 3.8 Live scores 30.1%.
  • Standard input audio is about $0.84/hr (cheapest in the Index); Extended Thinking about $3.50/hr, still below Astra at $5.83.
Read full story
Linked Models & Agents:
⚡ Google Gemini 3.8 Live⚡ GPT Live 1⚡ GPT-6 Astra🌐 Google DeepMind

Agent Arena Image-to-WebDev: GPT-6 Astra (Max) leads at 1733; Claude Fable 5.1 second

Arena updated the Image-to-WebDev leaderboard: GPT-6 Astra (Max) leads at 1733 points, 129 above GPT-5.6 Sol (xHigh); Claude Fable 5.1 (Max) is second at 1710. The board compares newly evaluated model releases on image-to-webdev delivery.

Key Takeaways

  • GPT-6 Astra (Max) leads Image-to-WebDev at 1733 points.
  • Claude Fable 5.1 (Max) ranks second at 1710.
  • Four newly evaluated model releases landed on the board.
Read full story
ADSponsored

Artificial Analysis: GPT-Live-1 (Astra) tops Speech to Speech Index at 81.5

Artificial Analysis (@ArtificialAnlys) published its Speech to Speech Index: OpenAI GPT-Live-1 with Astra (medium) as the delegated backend debuts at #1 with 81.5, while Sol (low) scores 80.1 at #3, with Grok Voice Think Fast 2.0 High between them at 81.3. GPT-Live-1 is a full-duplex speech model that can delegate reasoning and tool use to a backend text model mid-conversation. The same drop covers Speech Agent Arena, Tau Voice, Big Bench Audio, plus cost and time-to-first-audio.

Key Takeaways

  • GPT-Live-1 (Astra medium) leads Speech to Speech Index at 81.5; Sol low is #3 at 80.1.
  • On Tau Voice, Astra medium (67.9%) and Sol low (59.3%) take the top two agentic spots.
  • Cost is about $5.83/$4.47 per hour of input audio incl. backend; TTFA about 1.34s/1.24s vs Grok Voice 0.70s.
Read full story
Linked Models & Agents:

Agent Arena: DeepSeek-V4.1-Flash (Max) reshapes open-model Pareto frontier at ~$0.07/task

Arena.ai (@arena) reports Agent Arena results: DeepSeek-V4.1-Flash (Max) posts about +4.87% net improvement at roughly $0.07 median task cost — lowest among the top-3 open models — retaining ~98% of Hy4 preview’s net gain at ~73% lower cost and ~76% of Kimi K3 (Max) performance at ~92% lower cost.

Key Takeaways

  • DeepSeek-V4.1-Flash (Max) enters Agent Arena at about +4.87% net improvement.
  • Median task cost ~$0.07 — cheapest among top-3 open models.
  • Beats Hy4 / Kimi K3 on cost-efficiency and reshapes the Pareto frontier.
Read full story
Linked Models & Agents:

LMArena: Muse Spark 1.3 Max hits #13 on Agent Arena (+4.2%); Code to #15

LMArena reports Muse Spark 1.3 (Max) at #13 on Agent Arena with +4.2% net improvement across 8.7K+ real agentic sessions — a 17-rank climb from Muse Spark 1.2 (xHigh) at #30. Code, Work, and Chat all improved, with Code moving to #15 (+4.3%).

Key Takeaways

  • #13 on Agent Arena with +4.2% net improvement over 8.7K+ sessions.
  • 17-rank climb from Muse Spark 1.2 (xHigh) at #30.
  • Code reaches #15 (+4.3%); Work and Chat also improve.
Read full story

LMArena: Claude Fable 5.1 (Max) #1 on Agent Arena (+15.8% net) at $4.14 median cost/task

Arena.ai says Anthropic Claude Fable 5.1 (Max) is #1 on Agent Arena across 6.7k+ real-world long-horizon agentic sessions with +15.8% net improvement, redrawing the price-performance frontier at a $4.14 median cost/task. Implicit praise-vs-complaint leads by +42.5%, confirmed success +22.4%, bash recovery +13.1%, and no tool hallucinations; GPT-6 Astra traces are still coming in.

Key Takeaways

  • Claude Fable 5.1 (Max) tops Agent Arena with +15.8% net over 6.7k+ real agentic sessions.
  • Median cost $4.14/task — both the strongest and costliest model on the board, reshaping the Pareto frontier.
  • Praise-vs-complaint +42.5%, confirmed success +22.4%, bash recovery +13.1%, no tool hallucinations; Astra traces still arriving.
Read full story

LMArena: Meta Muse Spark 1.3 enters Agent/Code Arena; voting open, scores soon

Arena.ai (@arena) says Meta Muse Spark 1.3 is now in the Arena: Agent Arena measures long-horizon agentic tasks with web search, filesystem, and terminal tools via causal tracing vs the average model; it is also in Code Arena WebDev/Text/Vision/Document. Voting is open and scores are coming soon.

Key Takeaways

  • Muse Spark 1.3 is live in Agent Arena and Code Arena (including WebDev).
  • Agent Arena scores long-horizon tool-using workflows; leaderboard scores coming soon.
  • Voting is open so builders can stress-test prompts against frontier peers.
Read full story

LMArena: Gemini 3.8 Flash hits Agent Arena Pareto first time at $0.22 median/task

Arena.ai (@arena) says Google DeepMind’s Gemini 3.8 Flash (High) put Gemini on the Agent Arena Pareto frontier for the first time: $0.75/$3.75 per MTok, ~$0.22 median cost per Agent Arena task with +5.94% net gain—on par with Grok 4.5 and GLM 5.2 (Max) at roughly 44–50% lower price.

Key Takeaways

  • Gemini 3.8 Flash (High) lands on the Agent Arena Pareto frontier for the first time.
  • Priced $0.75/$3.75 per MTok; ~$0.22 median/task in Agent Arena with +5.94% net.
  • About 44–50% cheaper per task than Grok 4.5 ($0.39) and GLM 5.2 Max ($0.44).
Read full story
ADSponsored

Cursor adds Gemini 3.8 Flash — Google’s new workhorse now in the IDE

Cursor (@cursor_ai) announces Gemini 3.8 Flash is now available in Cursor. Paired with Google DeepMind’s same-day agent/cyber narrative and clear Agent Arena gains, developers can use the faster, stronger Flash-tier model inside their familiar AI coding IDE.

Key Takeaways

  • Official: Gemini 3.8 Flash is live inside Cursor.
  • Brings Google’s newest Flash workhorse into a mainstream AI IDE with low switching cost.
  • Pairs well with Agent Arena gains for everyday coding, tool use, and longer tasks.
Read full story

LMArena: Gemini 3.8 Flash (High) +5.94% net on Agent Arena, ranks #14

LMArena (@arena) breaks down Gemini 3.8 Flash (High) vs 3.7 Flash (High) on Agent Arena: net improvement jumps from +0.84% (#32) to +5.94% (#14). Agent Arena scores relative gains on real long-horizon tasks with web, filesystem, and terminal tools. Among five signals, Praise vs Complaint improves most (+14.78% vs -1.60%); Confirmed Success and Bash Recovery also rise, while Steerability remains a relative weakness but better than 3.7.

Key Takeaways

  • Agent Arena net +5.94% and #14 overall, up from +0.84%/#32 on 3.7 Flash (High).
  • Praise vs Complaint +14.78% vs -1.60%; Confirmed Success and Bash Recovery also improve.
  • Steerability still weak (-1.43%) but better than 3.7; Tool Hallucination remains clean for both.
Read full story

LMArena: Gemini 3.8 Flash debuts in Agent/Text/Code Arena — #14 Agent, #7 Text

LMArena (@arena) says Gemini 3.8 Flash (High) is live across Agent Arena, Text Arena, and Code Arena WebDev. It ranks #14 in Agent Arena (+5.94% net, up from 3.7 Flash at #32), #7 in Text Arena (1494 pts) with Coding category jumping #22→#7, and #18 in Code Arena WebDev (1567 pts).

Key Takeaways

  • Live in Agent, Text, and Code WebDev Arenas for tool-use and coding evals.
  • Agent Arena #14 (+5.94%), a big jump from Gemini 3.7 Flash at #32.
  • Text Arena #7; Coding category #22→#7; WebDev #18 keeps DeepMind near the lab top.
Read full story

LMArena: Claude Fable 5.1 is live in the Arena; Agent Arena scores long-horizon tool-using agents

LMArena (@arena) said Anthropic’s Claude Fable 5.1 is now live for Arena voting, with scores coming soon. Agent Arena measures long-horizon real-world agent tasks where models can use web search, filesystem, and terminal tools; Fable 5.1 is also in Code Arena WebDev, Text, Vision, and Document.

Key Takeaways

  • Fable 5.1 is live for public Arena voting; official scores pending.
  • Agent Arena targets long-horizon workflows with search, filesystem, and terminal tools.
  • Also listed across Code Arena WebDev, Text, Vision, and Document.
Read full story