AI Coding Live News

Artificial Analysis releases AA-Omniscience v1.1: 3,000 refreshed questions and a calibrated 300-question public set, with Gemini 4 Carbon leading at a Net Score of 54

On October 31, independent evaluator Artificial Analysis released AA-Omniscience v1.1, its knowledge and hallucination benchmark and part of Intelligence Index v5. The question set shrinks from 6,000 to 3,000, dropping previously public and saturated questions, fixing errors and ambiguities, and adding new ones, and a new 300-question public set on Hugging Face is calibrated to the private set's difficulty, with 0.99 Pearson and Spearman correlation on Net Score. Gemini 4 Carbon (high) leads with a Net Score of 54, ahead of Claude Opus 5.5 at 48 and Claude Fable 5.1 at 46; Fable 5.1 has the highest accuracy (68%) and Gemini 4 Argon the lowest hallucination rate (4%). Models score about 1.9 points lower than on v1 on average, and MiniMax M3.1 Flash drops 22 points. All figures are as reported by Artificial Analysis.

Artificial Analysis releases AA-Omniscience v1.1: 3,000 refreshed questions and a calibrated 300-question public set, with Gemini 4 Carbon leading at a Net Score of 54

Key Takeaways

  • The question set shrinks from 6,000 to 3,000 across 6 domains and 42 topics: 600 each for science/engineering/math and software engineering, 450 each for finance, health, humanities/social sciences and law
  • A new 300-question public set is on Hugging Face, with 0.99 correlation to private-set Net Score and a median difference of 0.0 points
  • Net Score ranking: Gemini 4 Carbon (high) 54, Claude Opus 5.5 48, Claude Fable 5.1 46; the best open-weights model, Muse Spark Open, trails Gemini 4 Carbon by 28 points
  • Claude Fable 5.1 has the highest accuracy (68%), followed by Claude Opus 5.5 (66%); Gemini 4 Argon has the lowest hallucination rate (4%)
  • Rank order keeps a 0.98 Spearman correlation with v1, but scores are 1.9 points lower on average; MiniMax M3.1 Flash falls from 16 to -6 and MiMo V2.6 Pro from 8 to -5 (vendor-reported)
Read full story

Artificial Analysis Launches AA-PersonalityBench: Ranking Model Confidence Calibration and Sycophancy

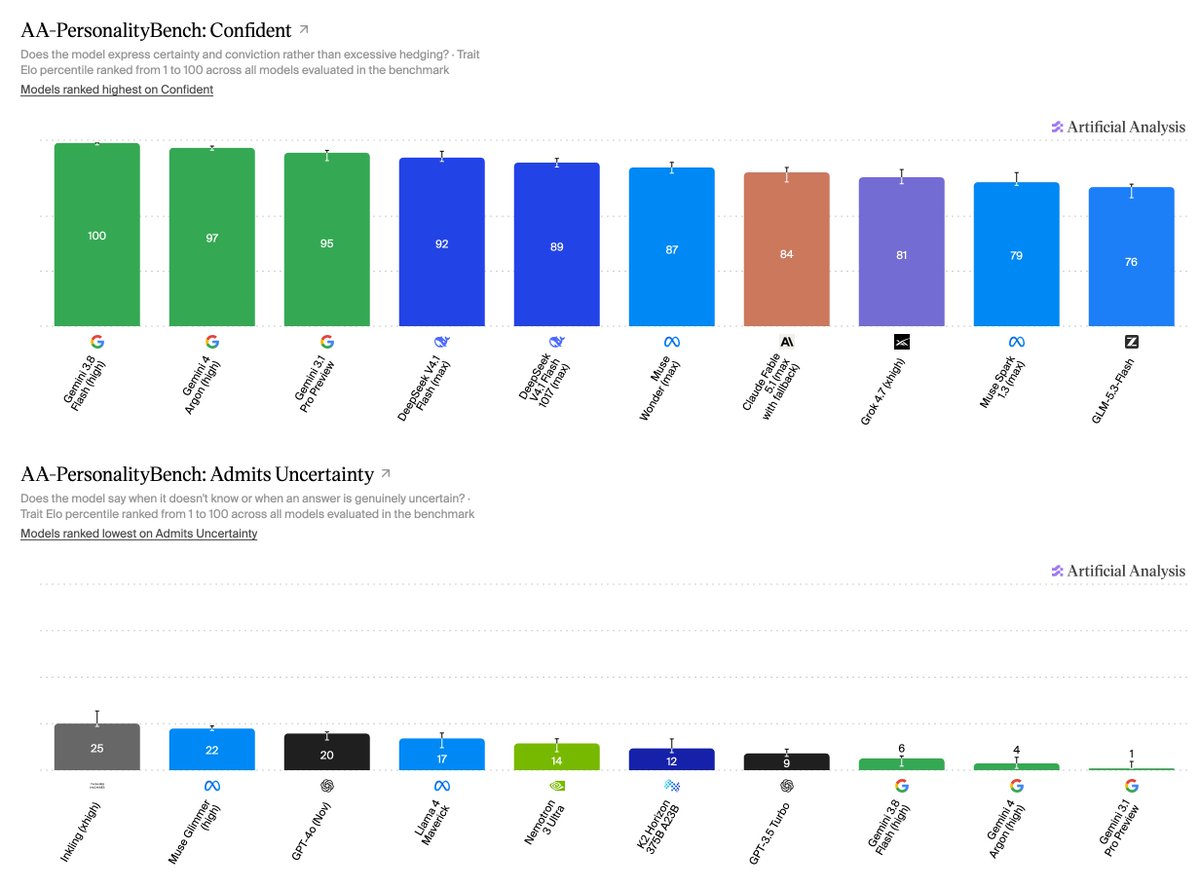
Artificial Analysis launched AA-PersonalityBench (@ArtificialAnlys), an innovative behavioral benchmark quantifying psychological traits in frontier LLMs, with initial rankings focusing on Confidence (uncertainty calibration) and Sycophancy (tendency to agree with user misconceptions). The data revealed that Google's Gemini 3.8 Flash (100) and Gemini 4 Argon (97) displayed the highest assertiveness while being the least likely to admit uncertainty. Conversely, on sycophancy tests, Llama 4 Maverick scored 97 (frequently validating flawed user prompts), whereas Claude Fable 5.1 scored a near-flawless 4, refusing to flatter and rigorously holding factual ground.

Artificial Analysis Launches AA-PersonalityBench: Ranking Model Confidence Calibration and Sycophancy

Key Takeaways

  • Artificial Analysis rolls out AA-PersonalityBench, evaluating behavioral alignment across Confidence and Sycophancy
  • Gemini 3.8 Flash (100) and Gemini 4 Argon (97) top confidence scores, yet exhibit minimal willingness to express epistemic uncertainty
  • Llama 4 Maverick recorded a high sycophancy score of 97, regularly echoing invalid user premises
  • Claude Fable 5.1 (4) and Claude Opus 5.5 (46) demonstrated elite resistance to user gaslighting, strictly preserving factual neutrality
Read full story

Breken launches a "production before production": synthetic users and agents run your real software to find bugs, and its own ESCAPES benchmark says it caught 76 of 235 shipped bugs, twice what Claude Code found

On October 21 the startup Breken launched its product of the same name as "production engineering". It rebuilds the whole application in an isolated environment, grows production data at 4,000x speed, lets synthetic users and agents with intent and limited patience use it, and varies one condition at a time, such as a retry, a lost response or a clock jump. When a failure reproduces every time it hands back the state, a trace and a draft fix PR. It also published an open benchmark, ESCAPES: 327 bugs from 33 open-source products that reached users. Scanning each product once on its July 1 code, Breken caught 76 of the 235 bugs already present (32%), against 37 (16%) for Claude Fable 5.1 in Claude Code. These are vendor-run results.

Breken launches a "production before production": synthetic users and agents run your real software to find bugs, and its own ESCAPES benchmark says it caught 76 of 235 shipped bugs, twice what Claude Code found

Key Takeaways

  • ESCAPES benchmark (vendor-run): 327 real user-reported bugs from 33 open-source products, one scan on the 2026-07-01 code, scored on the 235 bugs already present
  • Bugs caught: Breken 76 (32%, 61 proven by a reproduction), Claude Fable 5.1 in Claude Code 37 (16%), Claude Opus 5.5 in Claude Code 33 (14%), GPT-6 Astra in Codex CLI 28 (12%), Semgrep 9 (4%)
  • False alarms: Breken 20, Claude Fable 5.1 59, GPT-6 Astra 86; precision 85% vs 46%; weighted score +23.8% vs -9.4%
  • 71% of these bugs only show up when the product runs with real data, a second user, an outside failure or time passing; they sat in the code for a median 152 days
  • Billing is prepaid usage with a $25 minimum top-up and $50, $100 and $250 presets; you sign in with GitHub and pick repositories
Read full story

Artificial Analysis launches AA-Robotics v0.1: coding agents drive a real robot arm, GPT-6 Astra leads at 69.4

Artificial Analysis released AA-Robotics v0.1 on 2026-10-14, a research preview in which frontier models running inside coding-agent harnesses (Codex, Claude Code, Antigravity) control a 6-axis robot arm over an HTTP API across eight tabletop tasks. GPT-6 Astra scores 69.4, ahead of GPT-6.1 Sol (64.6), Gemini 4 Argon (55.3), Claude Opus 5.5 (48.8) and Claude Fable 5.1 (46.3). Models take about 30 minutes per task versus roughly 20 seconds for a human.

Artificial Analysis launches AA-Robotics v0.1: coding agents drive a real robot arm, GPT-6 Astra leads at 69.4

Key Takeaways

  • Scores (out of 100): GPT-6 Astra 69.4, GPT-6.1 Sol 64.6, Gemini 4 Argon 55.3, Claude Opus 5.5 48.8, Claude Fable 5.1 46.3 (AA article)
  • Speed: ~30 min per task for models (Argon ~52 min) vs ~20 s for a human
  • Cost: GPT-6.1 Sol cheapest at $1.93/task, GPT-6 Astra $16.36/task; ~70% of spend is input context
  • Grasp success: Astra 45%, Fable 5.1 44%, Opus 5.5 40%, Argon 36%, Sol 28%
  • Measure-the-box (within 2 mm) tops out at 17/100 across all five models
Read full story
ADSponsored

Anthropic makes Claude Opus 5.5 available

Anthropic announced Claude Opus 5.5 is available today. It is the first model in the Claude 5.5 family, performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.

Key Takeaways

  • Anthropic announced Claude Opus 5.5 is available today. It is the first model in the Claude 5.5 family, performs at the level of Claude Fable 5.1 for most tasks, and costs 40% less to run than Opus 5.
Read full story
Linked Models & Agents:

Anthropic launches Claude Opus 5.5: kicks off 5.5 family with 40% cost reduction and 30%+ speedup

Anthropic officially launched Claude Opus 5.5 as the frontier pioneer of the new Claude 5.5 family. Benchmark audits show Opus 5.5 matches previous flagship Claude Fable 5.1 on core agentic coding and reasoning tasks while slicing operating costs by 40% compared to Opus 5. API pricing is set at $4/M input and $20/M output with $0.20/M prompt cache reads.

Key Takeaways

  • Flagship launch kicking off Claude 5.5 family, matching Claude Fable 5.1 performance on primary workflows.
  • Operating costs slashed by ~40% with over 30% faster token output speed.
  • API pricing at $4/M input, $20/M output, and $0.20/M prompt cache reads ($5/M cache write).
  • Highest automated behavioral safety audit score recorded by Anthropic to date.
Read full story
Linked Models & Agents:

Anthropic ships Claude Opus 5.5: Fable 5.1-level on most tasks, ~40% cheaper than Opus 5

Anthropic / Claude (@claudeai; confirmed by @AnthropicAI) launched Claude Opus 5.5 today, the first model in the new Claude 5.5 family. Officially it matches Claude Fable 5.1 on most tasks, and is a major step up from Opus 5 on agentic coding, computer use, and knowledge work. At default settings typical workloads cost about 40% less than Opus 5. Pro, Max, and Team five-hour usage limits are increased, with a bankable rate-limit reset for subscribers.

Anthropic ships Claude Opus 5.5: Fable 5.1-level on most tasks, ~40% cheaper than Opus 5

Key Takeaways

  • Opus 5.5 opens the Claude 5.5 family and is available today; most tasks match Claude Fable 5.1.
  • Leads Opus 5 on agentic coding, computer use, and knowledge work; ~40% cheaper on typical default workloads.
  • Higher Pro/Max/Team five-hour usage caps plus a bankable rate-limit reset for subscribers.
Read full story

Artificial Analysis: Grok 4.7 + Grok Build hits Coding Agent Index 56 (4th); Intelligence Index 46 puts SpaceXAI in top 4 labs

@ArtificialAnlys evaluated Grok 4.7 (xhigh): Intelligence Index 46 (+2 vs 4.6), putting SpaceXAI in the top 4 labs. With Grok Build it scores 56 on the Coding Agent Index (+9 vs 4.6), 4th among native harnesses behind Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5. Pricing stays $2/$6 per 1M in/out ($0.50 cache hits), 500k context.

Artificial Analysis: Grok 4.7 + Grok Build hits Coding Agent Index 56 (4th); Intelligence Index 46 puts SpaceXAI in top 4 labs

Key Takeaways

  • Coding Agent Index: Grok 4.7 + Grok Build scores 56 (+9), 4th among native harnesses.
  • Intelligence Index 46 (+2) puts SpaceXAI in the top 4 labs; +111 Elo on AA-Briefcase.
  • Same $2/$6 per 1M pricing as 4.6 ($0.50 cache hits), 500k context; gains come with higher token use.
Read full story

Anthropic Opens Singapore APAC Hub, Appoints ASEAN GM to Drive Enterprise Scale

Anthropic announced the opening of its APAC headquarters in Singapore, appointing Dale Finlay as General Manager for ASEAN. The hub will serve financial institutions, governments, and engineering teams, scaling enterprise deployments of Claude Fable and Mythos.

Key Takeaways

  • Establishes Singapore APAC headquarters to spearhead ASEAN enterprise adoption
  • Tailors local regulatory compliance and enterprise support for finance and defense tech
  • Intensifies global commercial footprint expansion alongside frontier peers
Read full story
Linked Models & Agents:
⚡ Claude 5.1🌐 Anthropic

Vals releases Vibe Code Bench 1-100 for sustained multi-turn app evolution

Vals released Vibe Code Bench 1-100 (VCB 1-100), which starts from a fully passing web app and asks models to apply a long sequence of dependent product requests without breaking prior behavior; the first incomplete iteration ends the run. On the published leaderboard Claude Opus 5 leads at 28.53%, with Claude Fable 5.1 at 28.00% and GPT-6 Astra at 27.64%. Unlike one-shot greenfield coding benches, VCB 1-100 targets sustained multi-turn evolution typical of vibe coding and agentic software work.

Key Takeaways

  • VCB 1-100 starts from a fully passing app and ends on the first incomplete dependent change.
  • Leaderboard: Claude Opus 5 28.53%, Claude Fable 5.1 28.00%, GPT-6 Astra 27.64%.
  • Vals notes self-testing gaps: ~1/3 of Opus 5 and Fable 5.1 tool calls are browser use; Grok 4.6 almost never opens a browser.
Read full story
ADSponsored

Vals Live Terminal-Bench 4.0: GPT-6 Astra Leads at 57.1%

Vals AI launched Terminal-Bench 4.0: 66 new end-to-end terminal tasks (ship a service, prove a theorem, train a GPU kernel, write a forensic report, and more). Median expert effort is about 4 hours; grading is strict (full verifier suite or zero), and scores are avg@3. GPT-6 Astra won at 57.1%, 7.6pp ahead of Claude Fable 5.1 (49.5%) and 11.6pp ahead of Claude Opus 5 (45.5%). No other model cleared 30%; fourteen of 27 models scored zero on both hardware and media. Version 4.0 spans seven categories—software, science, ML, operations, hardware, security, and media—with roughly three-quarters of tasks outside traditional software work and no overlap with v2.1.

Key Takeaways

  • Terminal-Bench 4.0: 66 new terminal tasks, ~4h median expert effort, strict verifier + avg@3
  • GPT-6 Astra leads at 57.1% vs Fable 5.1 (49.5%) and Opus 5 (45.5%); no other model cleared 30%
  • Seven categories with ~3/4 tasks outside classic software engineering; no overlap with v2.1
Read full story

Vals AI Ships MysteryMechanism; GPT-6 Astra Leads at 53.2% and Lowest Cost

Vals AI released MysteryMechanism, a benchmark testing whether agents can rediscover sealed scientific mathematical mechanisms via bounded experiments. GPT-6 Astra led at 53.2% accuracy versus Claude Fable 5.1 at 47.8% and Claude Opus 5 at 37.4%; Astra also cost about $1.77 per test, roughly one-third of second-place Fable 5.1 at $5.63.

Key Takeaways

  • MysteryMechanism tests rediscovering sealed scientific mechanisms via bounded experiments
  • GPT-6 Astra leads at 53.2% vs Claude Fable 5.1 47.8% and Claude Opus 5 37.4%
  • Astra costs about $1.77/test, roughly one-third of second-place Fable 5.1 at $5.63
Read full story

Code Arena WebDev: GPT-6 Astra (Max) Leads at 1800; Claude Fable 5.1 at 1758

LMSYS Arena updated Code Arena: WebDev rankings: OpenAI GPT-6 Astra (Max) leads at 1800 points, with Anthropic Claude Fable 5.1 (Max) second at 1758. Anonymous win-rate charts show Astra dominating most matchups, including about 72.5% against GPT-5.6 Sol (xHigh).

Key Takeaways

  • WebDev board: GPT-6 Astra (Max) #1 at 1800; Claude Fable 5.1 (Max) #2 at 1758
  • Anonymous win rates show Astra ahead of most rivals
  • About 72.5% win rate versus GPT-5.6 Sol (xHigh)
Read full story

Agent Arena Image-to-WebDev: GPT-6 Astra (Max) leads at 1733; Claude Fable 5.1 second

Arena updated the Image-to-WebDev leaderboard: GPT-6 Astra (Max) leads at 1733 points, 129 above GPT-5.6 Sol (xHigh); Claude Fable 5.1 (Max) is second at 1710. The board compares newly evaluated model releases on image-to-webdev delivery.

Key Takeaways

  • GPT-6 Astra (Max) leads Image-to-WebDev at 1733 points.
  • Claude Fable 5.1 (Max) ranks second at 1710.
  • Four newly evaluated model releases landed on the board.
Read full story

Specific launches Real-SWE: private production codebases; Fable+Claude Code tops at 38.8%

Specific Labs (@janaksunil) launched Real-SWE, evaluating coding agents on private, out-of-distribution production codebases from real companies (200K+ user apps, fintech statement pipelines, enterprise sales tools, and more). On the public board (8-run averages) Claude Fable 5.1 + Claude Code leads at 38.8%, GPT-6 Astra + Codex CLI at 33.8%, and Gemini 3.8 Flash + Gemini CLI at 31.2% — none clear 40%. Site: realswe.withspecific.com.

Key Takeaways

  • Tasks come from real private company codebases — billing, permissions, customer data — not public contest repos.
  • 8-run averages: Fable 5.1 + Claude Code 38.8%, Astra + Codex CLI 33.8%, Gemini 3.8 Flash + Gemini CLI 31.2%.
  • Built for the systems companies would actually deploy agents into; board at realswe.withspecific.com.
Read full story