AI Coding Live News

Omarchy Local Model Engine omarchy-local-ai 0.5.0 Ships: Nemotron 3.5 Bolt Becomes the 64 GB Default, and DHH Says Omarchy 4.6 Will Recommend the Best Local Model for Each Machine

At 08:30 UTC on November 9, Omarchy creator DHH released v0.5.0 of omarchy-local-ai, the local model engine behind Omarchy. It extends local model support to 64 GB NVIDIA GB10 / N1x-class machines and makes Nemotron 3.5 Bolt the default for that tier (project measurements: full 262K context, 91 tok/s on short prompts and 82 tok/s at 32K, peaking under 40 GiB). About 20 minutes later he posted on X that Omarchy 4.6 will recommend the best model each machine can run, showing the agents panel on the Ryzen AI Max+ 495 machine AMD gave him, with a Claude Code subscription next to a local Qwen3.8 Flash Next using 94 GiB. The feature comes from PR #17267, merged November 1: one omarchy agent local use best command picks a model by GPU family and RAM class and runs it in a rootless Podman container with no network access, for coding agents such as OpenCode and pi. No release date for 4.6 has been announced.

Omarchy Local Model Engine omarchy-local-ai 0.5.0 Ships: Nemotron 3.5 Bolt Becomes the 64 GB Default, and DHH Says Omarchy 4.6 Will Recommend the Best Local Model for Each Machine

Key Takeaways

  • Release: DHH published omarchy-local-ai v0.5.0 at 08:30 UTC on November 9; the 64 GB GB10 / N1x default is Nemotron 3.5 Bolt, with Qwen3.8 27B (131K window) as fallback
  • Measured (project figures): on 64 GB, Bolt runs the full 262K context at 91 tok/s on short prompts and 82 tok/s at 32K, peaking under 40 GiB
  • The best.toml recommendation table covers 3 classes today: Strix Halo 128 GB (Flash Next, then 27B), GB10/N1x 128 GB (Flash Next, Bolt, 27B) and GB10/N1x 64 GB (Bolt, 27B)
  • On a Ryzen AI Max+ 395 / 128 GB, Flash Next reached 47.5 tok/s at 32K and 105 tok/s on code edits in v0.3.0; the 27B moved to 4-bit at 20.7 tok/s and 40 GiB
  • Security boundary: models run in rootless Podman containers with no network egress, a read-only root and all capabilities dropped, with the API key as a Podman secret; DHH's post had 163 likes and 21 replies after about 20 minutes
Read full story

PFN Open-Sources PLaMo 3.0 Fin: an 8B Japanese Finance Model with Japanese Reasoning and Tool Calling, Scoring 55.8 on a Japanese Finance Benchmark Ahead of Gemma 4 E4B and gpt-oss-20b, Fine-Tuned on In-House MN-Core 2 Chips

Japan's Preferred Networks (PFN) released PLaMo 3.0 Fin (plamo-3-8b-fin-instruct) on Hugging Face on November 9 under the PLaMo Community License. Built on PLaMo 3 NICT 8B Base, co-developed with NICT, it went through continued pre-training on finance corpora, SFT and DPO. It writes its reasoning in Japanese before answering, supports OpenAI-style function calling and can run on a single GPU in private clouds or on-premises. Per PFN, its average on the Japanese finance benchmark japanese-lm-fin-harness rose from 48.0 to 55.8, ahead of Gemma 4 E4B (45.6) and gpt-oss-20b (43.0) but behind Qwen3.5-9B (60.1) and Ministral 3 14B (62.8). SFT ran on PFN's in-house MN-Core 2 AI chip, and a coding agent helped port the training code in under a week.

PFN Open-Sources PLaMo 3.0 Fin: an 8B Japanese Finance Model with Japanese Reasoning and Tool Calling, Scoring 55.8 on a Japanese Finance Benchmark Ahead of Gemma 4 E4B and gpt-oss-20b, Fine-Tuned on In-House MN-Core 2 Chips

Key Takeaways

  • Specs (per PFN): 8B parameters, base PLaMo 3 NICT 8B Base, 262,144-token context (finance continued pre-training used 32,768-token sequences), BF16, Japanese-focused
  • japanese-lm-fin-harness: 48.0 to 55.8; 64.9 on the securities sales rep exam task, 14 points above Qwen3.5-9B; CPA audit task up from 13.1 to 29.2
  • pfmt-bench-fin-ja multi-turn finance chat: 8.35 (Qwen3.5-9B 8.53, Ministral 3 14B 8.11, gpt-oss-20b 7.83); PFN's own finance tool-use benchmark: 71.3 (Gemma 4 E4B 76.2, Qwen3.5-9B 75.4)
  • Tool use: only 0.9% of samples answered without calling any tool (Gemma 4 E4B 10.7%) and it reached the tool holding the needed data 78.9% of the time; PFN warns that reasoning can run too long when many tools are offered
  • License: PLaMo Community License, free commercial use (with registration) for companies and individuals under JPY 1 billion in annual revenue; vLLM 0.32.0+ ships plamo3 reasoning and tool-call parsers
Read full story
Linked Models & Agents:
⚡ Plamo 3.0 Fin⚡ Plamo 3 Nict 8b Base⚡ Gemma 4 E4b⚡ Qwen3 5 9b⚡ Ministral 3 14b⚡ GPT Oss 20b🌐 preferred-networks🌐 nict

Alibaba-Led Co-Design Bench Tests Coding Agents on 273 Real User App-Edit Tasks: Top Model GPT-6 Astra Meets 69.9% of Criteria but Fully Finishes Only 26.4%

Researchers from Fudan University, Alibaba (Alibaba Token Hub) and other institutions published Co-Design Bench on arXiv (2610.35138, submitted 2026-10-26), and from November 8 it spread widely on X. It takes 273 web-app revision tasks that real users had to request repeatedly, drawn from 26,314 real coding sessions and 37,463 deduplicated queries (100 multimodal editing tasks and 173 repository editing tasks), each paired with hidden expert-written acceptance criteria, 2,331 in total. Ten models were run in the same Claude Code harness. The best, GPT-6 Astra, met 69.9% of criteria per task on average but passed every criterion on only 26.4% of tasks; Claude Opus 5 reached 18.3% and Grok 4.6 just 6.6%. The paper tested September-era models, so newer ones such as Opus 5.5 and GPT-6.1 are not included.

Alibaba-Led Co-Design Bench Tests Coding Agents on 273 Real User App-Edit Tasks: Top Model GPT-6 Astra Meets 69.9% of Criteria but Fully Finishes Only 26.4%

Key Takeaways

  • Scale: 273 tasks (100 multimodal editing plus 173 repository editing) from 26,314 real coding sessions, with 2,331 hidden acceptance criteria
  • Top model GPT-6 Astra: meets 69.9% of criteria on average (Strict 0.699) but fully passes only 26.4% of tasks
  • Other full-pass rates (paper figures): Opus 5 18.3%, Qwen3.8-Max 16.5%, Kimi K3 15.8%, Qwen3.8-27B 15.0%, GPT-5.6 Sol 14.3%, Grok 4.6 6.6%
  • For contrast, the authors measured Opus 4.8 at 99.4% graded completion in agentic mode on the older WebCompass-edit benchmark, a sign that older tests are near saturation
  • All ten models score lower on repository edits that span three or four change types than on edits spanning one or two
Read full story

Open WebUI 0.13.1 Puts Coding Agents Such as Claude Code, Codex and Pi in the Model Picker and Introduces the Tether Desktop Companion

Open WebUI, the self-hosted AI chat platform with about 158K GitHub stars, published v0.13.1 on GitHub at 11:07 UTC on 2026-11-08. The headline change: on an Open Terminal that offers agents, coding agents such as Claude Code, Codex and Pi now appear in the model picker, where you can chat with them, call them by voice, pick reasoning effort and service tier, and approve their tool requests in the chat. It also introduces Tether, a desktop companion app for macOS, Windows and Linux that ties your own computer to Open WebUI so models and agents can work in your real files and repositories, reachable from any browser including a phone. Tool chats no longer rewrite the system prompt each round, so provider prompt caches can hit; the project says they now cost much less. About 45 minutes later v0.13.2 fixed a UUID error when serving over plain HTTP.

Open WebUI 0.13.1 Puts Coding Agents Such as Claude Code, Codex and Pi in the Model Picker and Introduces the Tether Desktop Companion

Key Takeaways

  • Release: GitHub v0.13.1 shipped at 11:07 UTC on 2026-11-08 and v0.13.2 followed at 11:53 UTC with fixes; the repo has about 158K stars
  • Coding agents as models: Claude Code, Codex and Pi appear in the model picker; each conversation uses 1 agent, and agent chats cannot be regenerated, continued or edited and resent
  • Tether: a new desktop companion app for 3 platforms (macOS, Windows, Linux); it connects outward so no ports need opening, and sessions expire after 90 days without use by default (SESSION_EXPIRES_IN)
  • Cost and speed: tool chats keep a stable prompt prefix so provider caches can hit; large chats open about 2x faster; typing after pasting 16,000 lines drops from 8.6 s to 74 ms per keystroke (about 117x)
  • New Auto tool permission (off by default) lets a review model decide whether a tool call needs confirmation; files under 50,000 characters are included in full instead of through retrieval
Read full story
ADSponsored

X Discussion: Claude Code's Addy Osmani Says "Your Coding Agents Made You a Manager" and Maps Team Management Habits to Agent Work

Addy Osmani (@addyosmani), who works on Claude Code at Anthropic, posted a long X article titled "Your coding agents made you a manager" at 07:32 UTC on 2026-11-08. His argument is that engineers who spend all day with a coding agent are already managing, and that the highest-leverage habits are, in order: give the agent a runnable way to check its work, state the context it cannot read from the repo, turn repeated corrections into CLAUDE.md entries, enforce only hard rules with hooks, agree a plan before coding, and delegate the task but never the judgment. At capture it had about 964 likes, 1,528 bookmarks, 101 reposts, 39 quotes and about 53,700 impressions. This is a discussion started by an employee's personal article, not an Anthropic announcement or a new feature.

Key Takeaways

  • Original post: Addy Osmani (bio "Claude Code @anthropicai") published an X article at 07:32 UTC on 2026-11-08; about 964 likes, 1,528 bookmarks, 101 reposts, 39 quotes, 94 replies and 53,672 impressions at capture, with more bookmarks than likes
  • The article lists 10 habits ordered by impact; the first is giving the agent a check with a clear pass or fail result (tests, build exit codes, linters, screenshots) and asking it to show the result as proof
  • Layered rules: prompts, CLAUDE.md and skills are requests the agent may weigh, while hooks, deny rules and managed settings are requirements that are always enforced; old habits like ALL CAPS and "think harder" should be dropped
  • Reset after two failed corrections: clear the session and rewrite the prompt; he says he usually runs 4 to 5 background agents plus a few local sessions, and that some days that is too many (author's own account)
  • Framing: a discussion started by an employee's personal article with no new official data or product launch; quote-post claims such as "Claude writes about 90% of Claude Code" are not in the article
Read full story

Google ReproBridge: Packaging One Successful Reproduction for the Next Coding Agent Lifts ML Experiment Reproduction from 76.4% to 92.6%

Google and the University of Waterloo posted ReproBridge on arXiv (2611.08452, 2026-11-05). It turns the code fixes, environment setup, launchers and guide an agent discovers while reproducing a paper into a standardized artifact. ReproBridge-Bench covers 36 papers, 387 experiments and 1,029 tasks. Author-reported: across Sonnet 4.6, Sonnet 5, Opus 5 and Gemini 3.8 Flash, mean success rises from 76.4% to 92.6% and API spend drops 19.7% on average.

Google ReproBridge: Packaging One Successful Reproduction for the Next Coding Agent Lifts ML Experiment Reproduction from 76.4% to 92.6%

Key Takeaways

  • Benchmark: 36 papers, 387 experiments, 1,029 tasks, each anchored by 5 human-verified reference scores
  • Author-reported: mean reproduction success 76.4% → 92.6% across 4 models; API spend down 19.7% on average
  • Cross-model spread narrows from 21.6 to 3.9 points; all four models exceed 90%
  • Gains range from 5.5pp (Opus 5) to 23.2pp (Gemini 3.8 Flash); removing code or environment hurts most in ablations
  • 24-hour wall-clock limit per paper on 8×H100; Codex serves as the primary Auditor
Read full story

Microsoft Foundry Local Wires Qwen3.8-27B into GitHub Copilot: Local Coding Agent on ~24 GB VRAM; Vendor Terminal-Bench 2.1 ~73.0

On 2026-11-05 Microsoft Foundry blogged that Foundry Local CLI 0.13.0+ can run 4-bit Qwen3.8-27B (~18 GB weights) on-device via ONNX Runtime and connect it to GitHub Copilot through Bring Your Own Key. Needs an NVIDIA GPU with at least 24 GB VRAM (about 64K context on 24 GB; up to the model's 262K max on 32 GB+). Vendor-cited model-card scores include Terminal-Bench 2.1 73.0 and SWE-bench Pro 61.7; Microsoft also reports higher generation speed than same-quant llama.cpp on RTX 5090 and DGX Spark. Mac and AMD support are still on the roadmap.

Microsoft Foundry Local Wires Qwen3.8-27B into GitHub Copilot: Local Coding Agent on ~24 GB VRAM; Vendor Terminal-Bench 2.1 ~73.0

Key Takeaways

  • Shape: Foundry Local 0.13.0+ runs 4-bit Qwen3.8-27B (~18 GB weights) and connects to the GitHub Copilot app via BYOK
  • Hardware: NVIDIA GPU with >=24 GB VRAM; ~64K context on 24 GB, up to 262K on 32 GB+; install CUDA/cuDNN yourself
  • Vendor-cited model-card scores (not a 4-bit re-run): Terminal-Bench 2.1 73.0, SWE-bench Pro 61.7, NL2Repo-Bench 42.3, DeepSWE 1.1 42.2
  • Stack: ONNX Runtime + DFlash2 speculative decoding + INT4/KV quant + prefix caching; Microsoft says the gap vs llama.cpp widens past 131K tokens
  • Limits: Microsoft says cloud models still win on hard reasoning; Mac/AMD not shipped; Copilot CLI local model does not imply offline—set COPILOT_OFFLINE separately
Read full story

OpenCode Ships Browse: MCP Server + Chromium Extension Lets Coding Agents Drive Your Signed-In Real Browser

On 2026-11-07 the official OpenCode account announced Browse: an MCP server plus Chromium extension that lets agents drive your local real browser with existing tabs, logins, and extensions. Sensitive steps such as login, 2FA, or payment hand the tab back until you click Continue. It works with Chrome, Edge, Brave, Arc and other Chromium browsers, and with MCP clients including OpenCode, Claude Code, Cursor, Codex, and Zed. Source is MIT at anomalyco/browse; the npm package is @opencode/browse.

OpenCode Ships Browse: MCP Server + Chromium Extension Lets Coding Agents Drive Your Signed-In Real Browser

Key Takeaways

  • Shape: MCP server + Chromium extension; agents drive Playwright tabs in collapsed background groups, with screenshots, recordings, and HAR capture
  • Compatibility: browsers include Chrome, Edge, Brave, Arc, Helium, Vivaldi, Opera, Chromium; MCP clients include OpenCode, Claude Code, Cursor, Codex, Zed, and more
  • Safety UX: login, 2FA, and payment steps can hand off to the user; sessions support site allowlists; OpenCode published no standalone benchmark
  • Install: prefer the Chrome Web Store extension, or npx @opencode/browse install / curl -fsSL https://opencode.ai/browse/install | bash (Node.js 22.19+)
  • Source: as of write time the official post had about 3,305 likes, 190 reposts, and ~135K impressions; GitHub anomalyco/browse had about 108 stars (MIT)
Read full story

Cursor Ships Voice Chat: Realtime Two-Way Calls with Agents on Agents Window, IDE, Web, and iOS via Grok Voice

On 2026-11-06, Cursor's changelog shipped Voice Chat with Agents: realtime two-way voice calls with coding agents in the Agents Window, IDE, web, and iOS. Dictation remains a separate feature. Grok Voice handles listening and speaking (voices include Ara, Eve, Leo, Rex, Sal); the coding agent still uses the model you picked. With Privacy Mode on, voice chat runs with zero data retention. A signed-in Cursor account is required (API-key-only sessions cannot start a call).

Cursor Ships Voice Chat: Realtime Two-Way Calls with Agents on Agents Window, IDE, Web, and iOS via Grok Voice

Key Takeaways

  • Source: Cursor changelog Voice Chat with Agents (2026-11-06) + docs at cursor.com/docs/agent/voice-chat
  • UX: start when the agent is idle and the chat input is empty via the waveform button; during a call hand off coding, read-only check diffs/runs/history, switch Project workers
  • Split: Grok Voice listens and speaks; the coding agent keeps your chosen model and speaks short progress/done notes
  • Privacy/limits: Privacy Mode = zero data retention for voice; signed-in account required; API-key-only sessions cannot call; ~10 min silence hangup by default plus a daily call limit
  • Not dictation: Cmd+Shift+Space still toggles dictation (formerly Voice Mode); Voice Chat is two-way speech with no dedicated shortcut
Read full story
Linked Models & Agents:

HF's Joël Niklaus Ships Harness Leaderboard: 28,849 Trials Across 9 Coding Agent Harnesses; Author Reports mini-swe-agent ~51.4% Average

On 2026-11-05, Hugging Face Harness Optimization researcher Joël Niklaus (@joelniklaus) released the Harness Leaderboard: same model, provider, and reasoning effort with only the harness swapped, covering GLM-5.3-Flash, DeepSeek-V4.1-Flash, and Flint on Terminal-Bench 2.1 and DeepSWE—28,849 trials and about $4,746 of inference. Author-reported averages: mini-swe-agent ~51.4% resolve rate; Pi ~49.4% at about $0.29 per solved task. This is an individual research leaderboard, not a Hugging Face company product announcement.

HF's Joël Niklaus Ships Harness Leaderboard: 28,849 Trials Across 9 Coding Agent Harnesses; Author Reports mini-swe-agent ~51.4% Average

Key Takeaways

  • Source: personal post by HF Harness Optimization researcher Joël Niklaus on 2026-11-05T16:04:08Z—not a company announcement
  • Scale (author): 9 harnesses on open models, 28,849 trials, ~$4,746 inference spend
  • Method: pin model/provider/reasoning effort; 3 attempts per task; Terminal-Bench 2.1 and DeepSWE
  • Results (author): averaged mini-swe-agent ~51.4%, openclaw ~27.3%; Pi ~49.4% at ~$0.29 per solved task
  • Use: public HF Space leaderboard + trajectories; Harness Lens documents prompts/tools for each harness
Read full story
ADSponsored
C
CMU Infini-AI LabInfini-AI-Lab·
👀28
🔥87

CMU Infini-AI Lab Drops CompressionBench and ServerBench: Coding Agents Compress LLMs and Design Serving Stacks; Sonnet 5.5 Hits ~4.87× vLLM Dollars-per-Dollar

Carnegie Mellon’s Infini-AI Lab posted twin arXiv benchmarks on 2026-11-04. CompressionBench asks coding agents to deliver verified compressed weights plus inference code under a storage cap (29/36 submissions pass; best-per-task designs average ~3.4% PPL above BF16). ServerBench scores complete LLM serving design by latency-qualified token value per GPU dollar; across 11 models × 3 deployments Claude Sonnet 5.5 reaches 2.97 dollars-per-dollar on Gemma E4B (~4.87× the vLLM reference) and 22/33 runs verify.

Key Takeaways

  • Official: arXiv:2611.06858 CompressionBench + arXiv:2611.06841 ServerBench (CMU Infini-AI Lab)
  • CompressionBench: 6 agents × 6 settings; 29/36 submissions pass independent verification; best designs ~3.4% PPL above BF16
  • ServerBench: objective dollars-per-dollar = latency-qualified token value / GPU cost; stateful coding-session replay
  • Paper table: Claude Sonnet 5.5 hits 2.97 on Gemma E4B (~4.87× vLLM reference); 22/33 runs verify
  • Code: github.com/Infini-AI-Lab/Compression-Bench and Server-Bench
Read full story

Vercel Security Review Enters Public Beta: Vulnerability Review on Every GitHub Push, One-Click Fixes with Vercel Agent

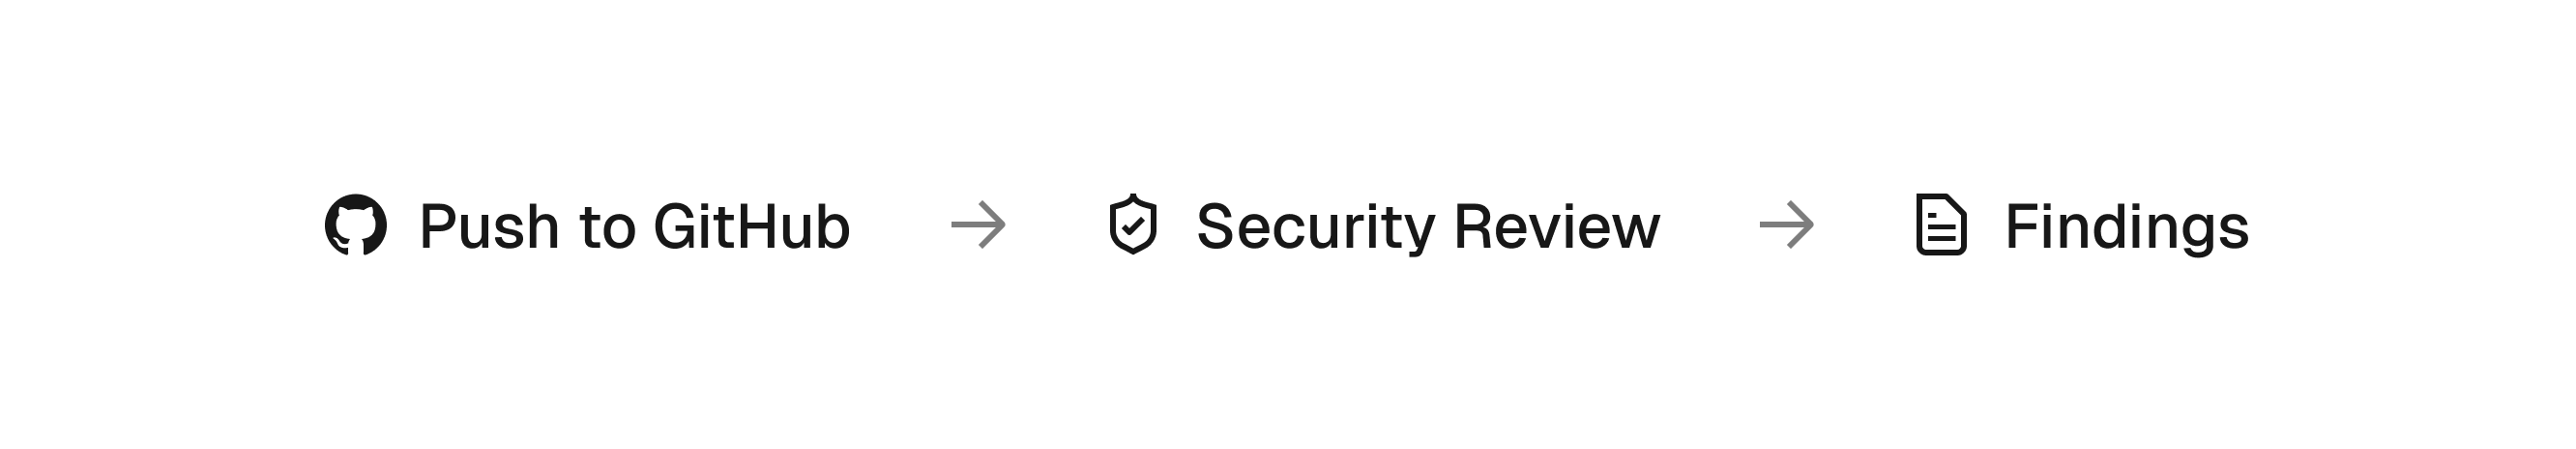
On November 3 (US Pacific time), Vercel launched Security Review in public beta. It is a new Vercel Agent capability alongside Code Review and Investigation: once enabled, every push to connected GitHub repositories triggers a diff-only vulnerability review that finishes in seconds. Findings land in the Security dashboard, PR comments and the CLI, and can be fixed with one click by Vercel Agent or pulled into your own coding agent via vercel security vulnerabilities. It is available to Pro and Enterprise teams, and reviews are free until November 10.

Vercel Security Review Enters Public Beta: Vulnerability Review on Every GitHub Push, One-Click Fixes with Vercel Agent

Key Takeaways

  • Trigger: every GitHub push (including direct pushes to production) is reviewed automatically; only the diff is scanned, which Vercel says finishes in seconds, so it can run on every preview and production deployment
  • Beyond pattern matching: the agent traces how changed code is reached, checks existing protections and rechecks each finding, which Vercel says catches logic flaws such as missing authorization checks
  • Teams can write security policies in plain language, scoped to projects or the whole team, and manage them with vercel security policy
  • Pricing: Vercel Agent rate, model tokens at provider cost with no markup, plus $0.25 per million tokens; reviews are free until November 10, 2026, while Agent fixes are billed
  • Availability: public beta for Pro and Enterprise teams; Vercel has not published detection-rate or false-positive benchmarks
Read full story

X discussion: Shopify CEO Tobi Lütke backs the monorepo as a Shopify engineer calls it a boon for coding agents, while critics still prefer split repos

Shopify distinguished engineer Burke Libbey posted on November 1 that moving to a monorepo has been a boon for agents at Shopify; it needs thoughtful tooling and has downsides that take effort to mitigate, but he would not go back. He was replying to Darren Shepherd, who said a day earlier that he hates the idea that monorepos are great for agents. Shopify CEO Tobi Lütke then quoted Burke and recalled Mikhail Parakhin telling him that every engineer hates the idea of moving to a monorepo, yet once it is there no engineer would want to work somewhere without one. Tobi's post drew about 1,115 likes, 454 bookmarks and 89K views and set off a wide debate. These are practitioner opinions, not an official technical announcement.

Key Takeaways

  • Original post: @tobi, Nov 1, 15:39 UTC, about 1,115 likes, 454 bookmarks, 95 replies and 89K views at fetch time
  • Shopify distinguished engineer Burke Libbey wrote that moving to a monorepo has been a boon for agents at Shopify; it needs thoughtful tooling and its downsides take effort to mitigate, but he would not go back
  • On the other side, Darren Shepherd (Rancher and k3s background) posted on Oct 31 that he hates the idea that monorepos are great for agents and that the best way to scale is to avoid scaling
  • Mikhail Parakhin replied to Tobi's retelling: "True story! And now, with agents, it more true than ever."
  • Supporters in the quote posts say agents can see every caller at once and get cross-stack type checking and atomic changes; skeptics ask whether agents make independent, separately evolving repos more attractive
Read full story
Linked Models & Agents:
g
guregodevo (Memdoor author)github.com·
👀43
🔥81

Memdoor reproduces GVS5H: a team of five Qwen3.8-27B agents averages 9.8/10 on the first 10 LiveCodeBench Hard problems, against 8.0 for a single Fable 5 call

On Oct 31 the open-source coding agent Memdoor (GitHub guregodevo/memdoor, Apache 2.0) published its team-solve workflow: using the GVS5H paper authors' exact prompts and loop, five Qwen3.8-27B instances act as planner, two ideators, solver and manager, talk only through files on disk, and a script that runs the tests decides success. Over five passes on the first 10 LiveCodeBench Hard problems from the GVS5H list it averaged 9.8/10, against 9.6 for the authors' own harness and 8.0 for a single Fable 5 call; 49 of 50 runs solved the problem for $35.79 in total, and every request and reply is public. The Hacker News post has about 200 points. This is a community reproduction on only 10 problems, and the author notes that training-data contamination cannot be ruled out.

Key Takeaways

  • Score: a mean of 9.8/10 over five passes (10, 10, 10, 10, 9), against 9.6 for the GVS5H authors' own harness and 8.0 for a single Fable 5 call (team-solve README, project-reported)
  • Cost: 49 of 50 runs solved, $35.79 and 15.3M output tokens in total; a median run took about 40 minutes of model time and $0.39, the longest 4 hours
  • Method: five roles (planner, two ideators, solver, manager) plus a repair worker each start from a fresh context, talk only through files on disk, and a shell script that runs the tests decides success instead of a model
  • Limits: only 10 problems rather than the paper's 100; the contests date from March and April 2025 and may be in training data; Fable 5's column comes from the GVS5H authors' result files and was not rerun in this harness
  • Reach: the HN post has about 200 points as of Nov 1, 16:10 SGT; the original GVS5H paper is arXiv 2608.26480, which reached #1 on HN on Oct 25
Read full story

Benji Taylor, head of design at X and SpaceXSI, open-sources Stageshow, an agent skill for realistic faux product UI and animated demos

On Oct 31, Benji Taylor, head of design at X and SpaceXSI, released Stageshow on X: an open-source skill (MIT license) for coding agents that helps them produce faux product UI that looks real, including stills, cursor demo animations, and bento grids, delivered as ordinary React components. It installs with one command, and he says it works with Grok Build, Claude Code, Codex, Gemini, and others. The launch post drew about 4,500 likes and 6,500 bookmarks. He notes it rarely nails a demo in one shot and most still take a few rounds of feedback.

Benji Taylor, head of design at X and SpaceXSI, open-sources Stageshow, an agent skill for realistic faux product UI and animated demos

Key Takeaways

  • Install: npx skills add benjitaylor/skills --skill stageshow; the author says it works with Grok Build, Claude Code, Codex, Gemini, and other agents (author's post)
  • Contents: a seven-step workflow in SKILL.md, reference rule docs, dozens of gold examples, a React kit, and self-check scripts such as film.mjs (GitHub)
  • License: the stageshow folder is MIT licensed; the repo was created Oct 26 and had about 61 stars at writing time
  • Reach: the launch post had about 4,521 likes, 6,561 bookmarks, and 213k views as of Nov 1, 08:00 SGT
  • Quality claims are the author's own: the same prompts did better with the skill, but no quantitative evaluation was published
Read full story