
vLLM and OpenRouter Launch Day-0 Serving for DeepSeek-V4.1-Flash-1017: 830K tok/s per GPU and 1.3B Tokens/$ TCO on SemiAnalysis AgentX
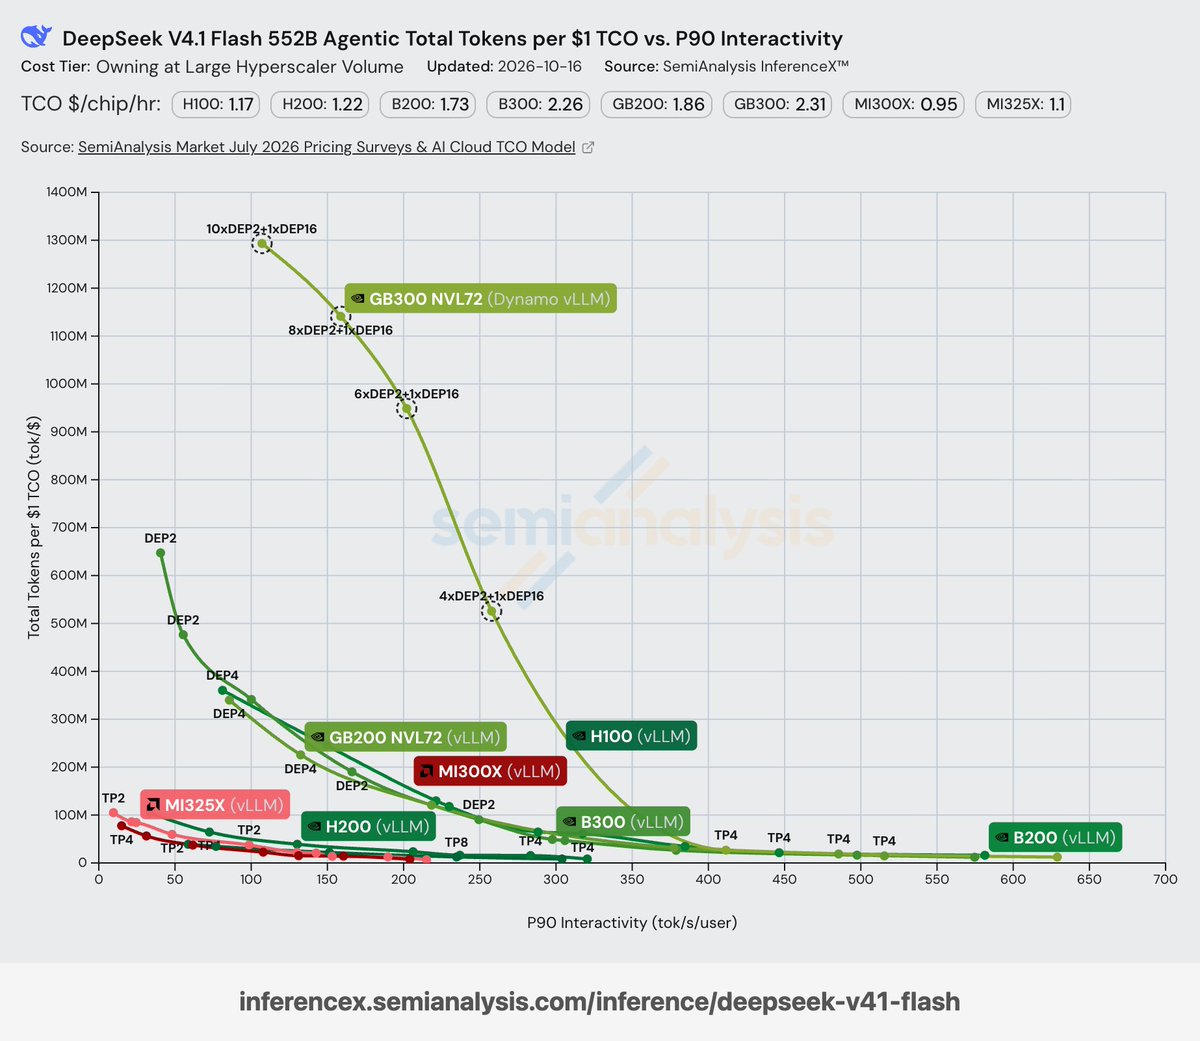
Following the release of DeepSeek-V4.1-Flash-1017, vLLM announced Day-0 serving optimization delivering 1.3B tokens per dollar TCO and 830K tok/s per GPU at 100 tok/s/user on SemiAnalysis AgentX (5x agentic throughput gain since Day 0), while OpenRouter launched live multi-provider routing starting at $0.10/M input and $0.50/M output tokens.
Key Takeaways
- vLLM delivers 830K tok/s per GPU (cached + input + output) at 100 tok/s per user and 1.3B tokens/$ TCO on SemiAnalysis AgentX for DeepSeek-V4.1-Flash-1017 (5x faster since Day 0)
- DeepSeek-V4.1-Flash-1017 reaches 77.0% on DeepSWE v1.1 (beating Claude Opus 5 at 74.0%), 68.2% on NL2Repo-Bench, and 72.1% on Apex Bench with shorter agentic outputs
- Live on OpenRouter from $0.10/M input and $0.50/M output tokens, while DeepSeek's official API alias deepseek-flash remains at $0.15/M input and $0.60/M output
Linked Models & Agents: