AI Coding Live News

Anthropic expands GSA partnership: new OneGov deal gives all levels of US government 40% off Claude Enterprise, Claude for Government and the API

On Oct 27 Anthropic announced a new OneGov agreement with the US General Services Administration (GSA): government customers get 40% off Claude Enterprise, Claude for Government and the Claude API. For the first time the discount covers every product surface (direct purchases today, cloud-provider channels in the coming months) and extends to state, local, tribal and territorial governments. Anthropic estimates about $1 billion in savings, with no minimum spend and pay-as-you-go usage.
Anthropic expands GSA partnership: new OneGov deal gives all levels of US government 40% off Claude Enterprise, Claude for Government and the API

Key Takeaways

  • 40% off Claude Enterprise, Claude for Government and the Claude API; direct purchases today, cloud-provider channels in the coming months (vendor-stated)
  • Anthropic estimates about $1 billion in government savings, with no minimum spend commitment and pay-for-what-you-use billing
  • About 500 US federal, state and local organizations use Claude; weekly Claude for Government active users are up about 8x since February and federal civilian usage is up about 20x in a year (vendor-stated)
  • Utah gave Claude Code to 34 developers across 10 agencies: 80% had a working environment within 30 minutes and 71% reported saving 20+ hours over a four-week pilot (vendor-stated)
  • Claude for Government went GA on Sep 30 at FedRAMP High; select Bedrock models hold DoD IL4/IL5, and Claude Enterprise is pursuing FedRAMP Moderate via FedRAMP 20x
Read full story

fal and Black Forest Labs launch FLUX 3 Max video model: tied #1 in image-to-video quality, a 10-second clip in about 12 seconds, roughly 22x faster than Seedance 2.5

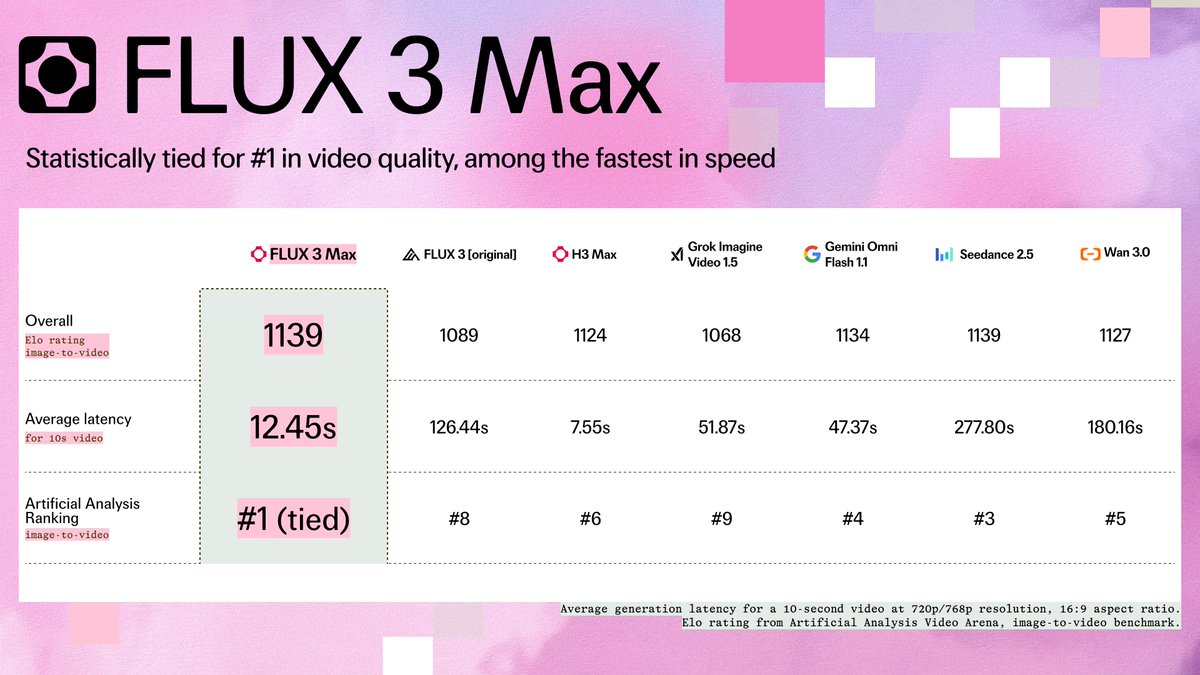
On Oct 19 (UTC) fal released FLUX 3 Max, a video model built by fal Research with Black Forest Labs through post-training, reinforcement learning and inference optimization on top of the FLUX 3 foundation model. It handles text-to-video, image-to-video and keyframes, up to 20 seconds, at 720p or 1080p, with audio on by default. On Artificial Analysis's preliminary image-to-video arena it scores 1,139 Elo, level with Seedance 2.5 and within the confidence interval of leader MiniMax H3 (1,141), and fal says a 10-second clip takes about 12.45 seconds. A 75% launch discount runs until Nov 7, putting 720p at $0.0425 per second.

fal and Black Forest Labs launch FLUX 3 Max video model: tied #1 in image-to-video quality, a 10-second clip in about 12 seconds, roughly 22x faster than Seedance 2.5

Key Takeaways

  • Artificial Analysis AA-Video-I2V v1.1 (preliminary): FLUX 3 Max at 1,139 Elo, level with Seedance 2.5 and just under MiniMax H3 at 1,141; "tied #1" rests on overlapping confidence intervals
  • Speed (fal-reported, 10-second 16:9 at 720p): FLUX 3 Max 12.45s, Gemini Omni Flash 1.1 47.37s, Seedance 2.5 277.80s; the press release quotes 10.95s instead
  • Versus the original FLUX 3: Elo up from 1,089 to 1,139 (+50) and a 10-second clip down from 126.44s to about 12s (11.5x per the press release, about 10x per the product page)
  • Pricing: promotional $0.0425/s at 720p and $0.0725/s at 1080p until Nov 7, then $0.17/s and $0.29/s, billed per output second
  • API options: 5-20 second duration, multiple aspect ratios, reasoning_level (low/high), generate_audio on by default; model IDs blackforestlabs/flux-3-max/*
Read full story
Linked Models & Agents:
⚡ FLUX 3 Max⚡ FLUX 3⚡ Seedance 2.5⚡ MiniMax H3🌐 fal🌐 Black Forest Labs🌐 Artificial Analysis

SpaceXAI: Grok 4.7 is 50% off on Ramp Router through Oct 6; public catalog still $2/$6

On 2026-10-02 SpaceXAI said Grok 4.7 is 50% off on Ramp Router through October 6. xAI list price remains $2/$6 ($4/$12 for the whole request at ≥200k prompt tokens), and the Router catalog still shows $2.00/$6.00. Routing is free through 2026 with $26 in new-user credits. The discount is not in the docs; check request cost logs before treating $1/$3 as real.

SpaceXAI: Grok 4.7 is 50% off on Ramp Router through Oct 6; public catalog still $2/$6

Key Takeaways

  • Promo: SpaceXAI says Grok 4.7 is 50% off on Ramp Router through 2026-10-06; not restated in the docs
  • List: xAI Grok 4.7 is $2 / $6 per million tokens; ≥200k prompt tokens bill the whole request at $4 / $12
  • Catalog: docs.router.com still lists grok-4.7 at $2.00 / $6.00, 500k context, reasoning low–xhigh, no Fast tier
  • Launch scores (not a re-test): CursorBench 4.0 46.3%, Terminal-Bench 4.0 37.6%, DeepSWE v1.1 high-effort 71.0%
  • Gateway: routing free through 2026, $26 new-user credits, endpoint https://api.router.com/v1
Read full story
Linked Models & Agents:

OpenAI improves GPT-6 prompt caching: higher default hit rates, up to 90% off cached input

OpenAI Developers (@OpenAIDevs) announced prompt-caching improvements for the GPT-6 API: higher default cache-hit rates so more input tokens get cached-input discounts of up to 90%, helping agents run faster and cheaper. OpenAI docs also point developers to the Prompt Caching Dashboard and miss Diagnostics.

OpenAI improves GPT-6 prompt caching: higher default hit rates, up to 90% off cached input

Key Takeaways

  • GPT-6 API prompt caching now hits more often by default for agent workloads.
  • Cached input tokens discounted up to about 90%.
  • Dashboard monitors hit rates; Diagnostics help fix cache misses.
Read full story
ADSponsored

OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

OpenAI introduced GPT-6 Sol and GPT-6 Luna, faster and more affordable models that carry forward much of GPT-6 Astra’s strength for work at scale. Caching and inference efficiency cuts yield 50% lower API prices versus GPT-5.6 promotional pricing: Sol is priced at $2/$10 per million tokens for deep reasoning, while high-volume Luna costs just $0.10/$0.50 per million tokens with a 90% prompt caching discount.

OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

Key Takeaways

  • Tiered dual-model architecture: Sol for deep reasoning and complex coding agents, Luna for ultra-high-throughput workflows.
  • 50% price slash: Sol at $2/$10 per million tokens; Luna down to $0.10/$0.50 with 90% prompt caching discount.
  • Available immediately in OpenAI API (gpt-6-sol, gpt-6-luna), ChatGPT Work, and Codex.
Read full story
Linked Models & Agents:

Xiaomi open-weights MiMo-V2.6-Pro: AA Intelligence Index 46, tops open weights on cost frontier

@ArtificialAnlys reports Xiaomi released open-weights MiMo-V2.6-Pro: Artificial Analysis Intelligence Index 46 (up from 26 on V2.5-Pro), now the top open-weights model, landing on the intelligence-vs-cost Pareto frontier at about $0.13 per Index task with unchanged token prices ($0.435/M input with 99% cache-hit discount, $0.87/M output). It is a 1.02T-total / 42B-active MoE.

Xiaomi open-weights MiMo-V2.6-Pro: AA Intelligence Index 46, tops open weights on cost frontier

Key Takeaways

  • Open weights: AA Intelligence Index 46, big jump from V2.5-Pro (26) and tops open-weights.
  • Cost: ~$0.13/task; $0.435/M input (99% cache-hit discount) and $0.87/M output unchanged.
  • Architecture: 1.02T-total / 42B-active MoE; more AA analysis forthcoming.
Read full story
Linked Models & Agents:
⚡ Xiaomi Mimo V2 6 Pro

GitHub Copilot Auto adds efficiency, balance, and intelligence cost/quality tiers

GitHub staffer Pierce Boggan (@pierceboggan) announced Copilot Auto model selection now offers three tiers—efficiency (cost-first), balance (cost/quality/latency), and intelligence (quality-first). Auto still picks a model per prompt; usage is billed on the selected model, and paid subscribers keep a 10% Auto usage discount. Rolling out in VS Code, Copilot CLI, and the GitHub Copilot app (changelog 2026-09-14).

Key Takeaways

  • Copilot Auto adds efficiency, balance, and intelligence cost/quality tiers.
  • Still selects per prompt; billed on the chosen model with a 10% Auto discount for paid plans.
  • Rolling out in VS Code, Copilot CLI, and the GitHub Copilot app.
Read full story

Artificial Analysis: Gemini 3.8 Flash hits Intelligence Index 59 on the cost Pareto frontier

Artificial Analysis (@ArtificialAnlys) reports Google DeepMind’s Gemini 3.8 Flash (high reasoning) scores 59 on the Intelligence Index, +3 vs Gemini 3.7 Flash and on par with GPT-5.6 Sol (xhigh) and Grok 4.6 (medium). Gains are driven by agentic evals (τ³-Banking, Terminal-Bench, GDPval). Discount pricing $0.75/$3.75 per 1M tokens through year-end puts it at ~$0.58/task on the intelligence–cost Pareto frontier.

Key Takeaways

  • Intelligence Index 59 at high reasoning (+3 vs 3.7 Flash), matching GPT-5.6 Sol xhigh / Grok 4.6 medium.
  • Agentic gains lead: τ³-Banking tool use, Terminal-Bench coding, and GDPval real-world tasks.
  • Year-end discount $0.75/$3.75 keeps ~$0.58/task on the intelligence–cost Pareto frontier.
Read full story

Anthropic opens a Claude Team plan for 10,000 scientists: free standard seats, $15 premium

Anthropic opened a Claude Team plan for scientists, starting with 10,000 seats across math, chemistry, physics, and other fields. Standard seats are free; premium seats with 5x usage limits cost $15 per month for one year, an 80% discount. Principal investigators at academic and nonprofit labs can enroll and add their groups. The expansion builds on Claude Science and the AI for Science credit program, with Anthropic saying it will grow well beyond the initial 10,000 seats.

Key Takeaways

  • 10,000 scientific seats launch with free standard access and $15/month premium seats at 5x usage for one year.
  • PIs at academic and nonprofit labs can enroll their groups.
  • The plan extends Claude Science and AI for Science credits, with more seats promised later.
Read full story

Cline: GLM-5.3 max outperforms GPT-5.6 Sol max on Terminal-Bench 4.0

Cline reported that Zhipu GLM-5.3 at max effort outperforms OpenAI GPT-5.6 Sol at max effort on the newly released Terminal-Bench 4.0. The post quotes Zhipu lead Zixuan Li's announcement that the benchmark itself is iterating fast enough to keep up with model releases. Cline already hosts glm-5.3 in-product: install with npm i -g cline, run /model, and select glm-5.3. ClinePass is offered as roughly 5x discounted access versus calling the direct API, continuing Cline's push to make open-weight agent models the default path rather than a hobby sidecar. For teams running terminal-native coding agents, the result matters because Terminal-Bench measures long-horizon shell work rather than single-file completion. An open-weight win against Sol on that surface changes both model routing and budget planning, especially if ClinePass pricing holds under production traffic.

Key Takeaways

  • GLM-5.3 max beats GPT-5.6 Sol max on Terminal-Bench 4.0, an open-weight challenge to a closed flagship.
  • Cline already serves glm-5.3 in-product via npm i -g cline and /model.
  • ClinePass offers about 5x discounted access versus the direct API for this class of open weights.
Read full story
ADSponsored

OpenAI slashes GPT-4o Batch API rates by 50% for high-throughput offline test generation and auditing

OpenAI announced a 50% price reduction across its asynchronous Batch API for GPT-4o and GPT-4o-mini. The discount enables developers and enterprise engineering teams to run large-scale automated security scanning, unit test synthesis, and codebase documentation over 24-hour non-peak windows at half the standard cost.

Key Takeaways

  • GPT-4o Batch input rates drop to $1.25/1M tokens, doubling cost-effectiveness for offline jobs.
  • Handles up to 50,000 asynchronous code review requests per batch within a 24-hour turnaround.
  • Ideal for repo-wide security audits, dead-code cleanup, and synthetic test generation.
Read full story
Linked Models & Agents:

Devin Desktop Stacks OpenAI Price Cut with Promo for 76% Total Discount on GPT-5.6 Sol

Cognition announced stacked pricing for GPT-5.6 Sol on Devin Desktop and CLI, combining OpenAI's rate reductions with promotional discounts for an effective 76% savings through October 3.

Key Takeaways

  • Promotional window runs through October 3, 2026, across both Devin Desktop and CLI interfaces;
  • Combines OpenAI's 20% price drop with 70% platform subsidy for an effective 76% off standard rates;
  • SWE-1.7 and GLM-5.2 models offered completely free for one month to expand developer adoption.
Read full story
Linked Models & Agents:

Cloudflare AI Gateway Unified Billing Offers 50% Off GPT-5.6 Sol Inference for One Month

Cloudflare introduced a 50% promotional discount for OpenAI's GPT-5.6 Sol via AI Gateway unified billing, combining edge caching, observability, and cost-effective multi-model routing.

Key Takeaways

  • Gateway competition expands from observability and retries into direct API rate subsidies on flagship models;
  • Unified billing invoice streamlines multi-vendor LLM management across hosted and proxied endpoints;
  • Edge caching and smart routing reduce time-to-first-token and operational costs for production apps.
Read full story
Linked Models & Agents:

Vercel v0 cuts GPT-5.6 Sol and Fast mode pricing by 50% through September 18

Vercel's vibe-coding platform v0 announced a 50% discount on GPT-5.6 Sol and Fast generation modes through September 18, 2026. Developers can build full-stack React and Next.js applications and iterate on interactive UI prototypes at half the standard credit cost.

Key Takeaways

  • 50% discount applied to GPT-5.6 Sol and Fast mode usage across v0.
  • Promotion runs through September 18, 2026, for all full-stack app prototyping.
  • Optimized for Next.js components with instant 1-click Vercel production deployment.
Read full story

Cline reports GLM-5.3 surpasses Claude Fable and DeepSeek V4-Pro on Terminal-Bench

Cline reported that Zhipu AI's newly released GLM-5.3 surpassed Claude Fable and DeepSeek V4-Pro on Terminal-Bench benchmarks. Built on enhanced long-horizon agentic post-training, GLM-5.3 is accessible via ClinePass at a 5x discount ($4.99 first month), with Cline noting that open-weight agent models have reached escape velocity.

Key Takeaways

  • GLM-5.3 overtakes Claude Fable and DeepSeek V4-Pro on CLI Terminal-Bench evaluations.
  • Heavy post-training on long-horizon engineering tasks drives self-correction accuracy.
  • ClinePass launches $4.99 introductory tier for high-speed open-weights agent execution.
Read full story