AI Coding Live News

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Arena announced a major update to Code Arena: WebDev: DeepSeek-V4.1-Flash-20261017 (Max) clinched the #1 position among open models with 1670 points, surpassing Kimi K3 (Max) at a 10x lower cost. Ranking #12 overall, it outperforms Claude Opus 5 (High) and narrows the gap with closed-source frontier GPT-6 Sol (Max) to roughly 10 points, resetting the Pareto efficiency curve at $0.30 input / $1.20 output per million tokens.

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Key Takeaways

  • DeepSeek-V4.1-Flash-20261017 (Max) captured the #1 open model position in Arena Code Arena: WebDev with 1670 points, surpassing Kimi K3 (Max)
  • Ranks #12 overall on the leaderboard, defeating Claude Opus 5 (High) and trailing closed-source champion GPT-6 Sol (Max) by only ~10 points
  • Resets the Pareto efficiency frontier at $0.30 input / $1.20 output per million tokens, cutting operational costs by ~10x against rival models
  • Gains +52 points over its previous 20260910 checkpoint in just over a month
Read full story
Linked Models & Agents:

Microsoft launches Microsoft-Decision-1: a Qwen3.5-9B-based decision-scoring model at $0.042/M input tokens, free output, on Foundry and OpenRouter

On Oct 9 Microsoft released Microsoft-Decision-1, a decision-scoring model that returns calibrated probabilities over fixed options instead of generating text, aimed at routing, classification, verification, agent guardrails and AI judging. Microsoft reports top accuracy across 36 blind benchmarks, ~35x lower P50 latency than GPT-6 Sol and a 1.3% decision-flip rate under perturbation. Available on Microsoft Foundry and OpenRouter, 32K context, $0.042/M input, free output.

Microsoft launches Microsoft-Decision-1: a Qwen3.5-9B-based decision-scoring model at $0.042/M input tokens, free output, on Foundry and OpenRouter

Key Takeaways

  • Pricing: $0.042/M input tokens, $0 output, 32,768-token context (OpenRouter)
  • Vendor-reported: highest accuracy across 36 blind benchmarks (~150K questions); 2.5x faster than runner-up H2O-Lightning-4B v1.1 and 35x faster than GPT-6 Sol
  • Robustness: 1.3% average decision flips across 8 perturbation types; zero flips when options are paraphrased, reversed or shuffled
  • Base: post-trained from Qwen3.5-9B for single-pass scoring; Microsoft plans to rebase on MAI and OpenAI models
  • Internal use: Xbox Research labeled 10K+ feedback items at near GPT-6 Sol quality, 14x+ faster and ~200x cheaper (vendor-reported)
Read full story
Linked Models & Agents:
⚡ Microsoft-Decision-1⚡ Qwen3.5-9B⚡ GPT-6 Sol🌐 Microsoft🌐 OpenRouter

GPT-6 rolls out to all of ChatGPT with Intelligent UI: interactive charts and in-chat tools, Sol for paid tiers and Luna for free

On Oct 7 OpenAI began rolling GPT-6 out globally in ChatGPT together with Intelligent UI: the model decides when to answer with diagrams, interactive charts, forms, tappable buttons or small in-chat tools (calculators, games, bill splitters) instead of plain text. Plus, Pro, Business and Enterprise get it first on GPT-6 Sol; Go and free users follow on Oct 8 on GPT-6 Luna. OpenAI says GPT-6 can stream partial answers while still thinking, cutting wait times by 44%.

Key Takeaways

  • Tiers: Plus / Pro / Business / Enterprise get GPT-6 Sol from Oct 7; Go and free get the more efficient GPT-6 Luna from Oct 8 (OpenAI announcement)
  • Answers while thinking: partial answers stream before reasoning finishes; OpenAI says wait times drop 44% and GPT-6 beat GPT-5.6 on hard web searches in internal tests (The Decoder)
  • Intelligent UI renders diagrams, interactive and editable charts, forms, tappable buttons and on-demand in-chat tools (savings calculator, retro game, bill splitter); users can dial visuals down (TechCrunch)
  • Safety: OpenAI says GPT-6 resists attempts to bypass its safety training better (The Verge)
  • Context: Google shipped a similar generative-interface feature for Gemini in May; ChatGPT now makes it a default for every user
Read full story

Vercel AI SDK @ai-sdk/openai 4.0.78: GPT-6 Sol/Luna allow reasoningEffortUpdate 'none'

Vercel AI SDK shipped @ai-sdk/[email protected] on 2026-09-26: request-level and positioned system-message reasoningEffortUpdate now accept 'none' so GPT-6 Sol/Luna conversations can turn reasoning off mid-thread. Updates are validated against each model’s supported efforts—unsupported request-level updates warn and omit; unsupported historical/message-level updates reject. Companion @ai-sdk/[email protected] and @ai-sdk/[email protected] pick up the dependency.

Vercel AI SDK @ai-sdk/openai 4.0.78: GPT-6 Sol/Luna allow reasoningEffortUpdate 'none'

Key Takeaways

  • Shipped: @ai-sdk/[email protected] / npm 4.0.78
  • Feature: reasoningEffortUpdate 'none' for GPT-6 Sol/Luna (#21518)
  • Validation: warn+omit unsupported request-level; reject unsupported historical updates
  • Companions: Azure 4.0.82, Bedrock 5.0.97; see OpenAI provider docs
  • Install: npm i @ai-sdk/[email protected]
Read full story
ADSponsored

simonw/llm 0.36: GPT-6 Sol/Luna catalog + supports_conversation=False for plugins

llm 0.36 (2026-09-22) adds gpt-6-sol/gpt-6-luna, lets plugins set supports_conversation=False (raises ConversationNotSupported; first used by llm-typesafe), and wraps reasoning traces in <details> in llm logs Markdown.

simonw/llm 0.36: GPT-6 Sol/Luna catalog + supports_conversation=False for plugins

Key Takeaways

  • Built-in gpt-6-sol and gpt-6-luna (#1702)
  • Plugins may set supports_conversation=False → ConversationNotSupported (#1692)
  • First consumer: llm-typesafe for Jev/TypeSafe models
  • llm logs wraps reasoning in HTML details (#1701)
  • Upgrade: pip install -U llm==0.36
Read full story

Codex CLI 0.157.0: GPT-6 Sol/Luna (incl. Bedrock), fullscreen transcript + background daemon by default

OpenAI Codex CLI rust-v0.157.0 (2026-09-25) adds GPT-6 Sol/Luna (incl. Amazon Bedrock), enables fullscreen transcripts and auto background-server startup by default, adds an f shortcut to fork locked conversations, and enables /import in remote and local daemon sessions.

Codex CLI 0.157.0: GPT-6 Sol/Luna (incl. Bedrock), fullscreen transcript + background daemon by default

Key Takeaways

  • GPT-6 Sol/Luna in catalog + Amazon Bedrock (#47332/#47347)
  • Fullscreen transcript + auto background-server default (#47178/#47179/#47318)
  • f forks locked conversations; /import in remote/daemon sessions (#47185/#47317)
  • Proxy + network policy hardening for realtime/search (#47101/#47389)
  • Upgrade: npm i -g @openai/[email protected]
Read full story

OpenClaw 2026.9.6: managed updates, restart recovery, 30-day Usage, plus Opus 5.5 / GPT-6 Sol·Luna / Grok 4.7

OpenClaw shipped v2026.9.6 on 2026-09-23 (macOS DMG rebuilt 2026-09-24 after launch crash #156861): clearer managed-update outcomes, restart recovery for unfinished work, complete 30-day Usage reporting, a GitHub reader, remote workspace Files/Memory/Skills, live meeting notes, optional TypeSafe Jev Decision Models, and chat models Claude Opus 5.5, GPT-6 Sol/Luna, and Grok 4.7. Scale: 2,614 PRs, 178 direct commits, ~350 contributors.

OpenClaw 2026.9.6: managed updates, restart recovery, 30-day Usage, plus Opus 5.5 / GPT-6 Sol·Luna / Grok 4.7

Key Takeaways

  • Verified scale on docs: 2,614 PRs / 178 commits / ~350 contributors
  • Managed updates + restart recovery; Usage covers a full 30-day window
  • GitHub reader; remote workspaces gain Files/Memory/Skills; live meeting notes
  • Decision Models (TypeSafe Jev/local) + Opus 5.5, GPT-6 Sol/Luna, Grok 4.7
  • Install [email protected]; macOS users hit by #156861 should reinstall the rebuilt DMG (#156881)
Read full story

Codex CLI 0.156: optional /tui fullscreen, voice on by default, /usage dashboard; 0.156.1 adds GPT-6 Sol/Luna

OpenAI shipped Codex CLI rust-v0.156.0 and hotfix 0.156.1 on 2026-09-22/23 (@openai/codex). 0.156.0 adds optional /tui fullscreen, voice default-on, /usage, worktrees on by default, themes/Mermaid, plus sandbox fixes. 0.156.1 adds GPT-6 Sol/Luna to the picker and recommends Luna on rate-limit switches.

Key Takeaways

  • Install @openai/[email protected] (0.156.0, 0.156.1)
  • /tui fullscreen; voice default-on (F8); /usage dashboard
  • Worktrees enabled by default from the agent command center
  • Sandbox isolation fixes for Windows inbound, privileged sockets, macOS handles
  • 0.156.1 adds GPT-6 Sol/Luna; rate-limit prompt recommends Luna
Read full story

OpenAI introduces GPT-6 Sol and GPT-6 Luna

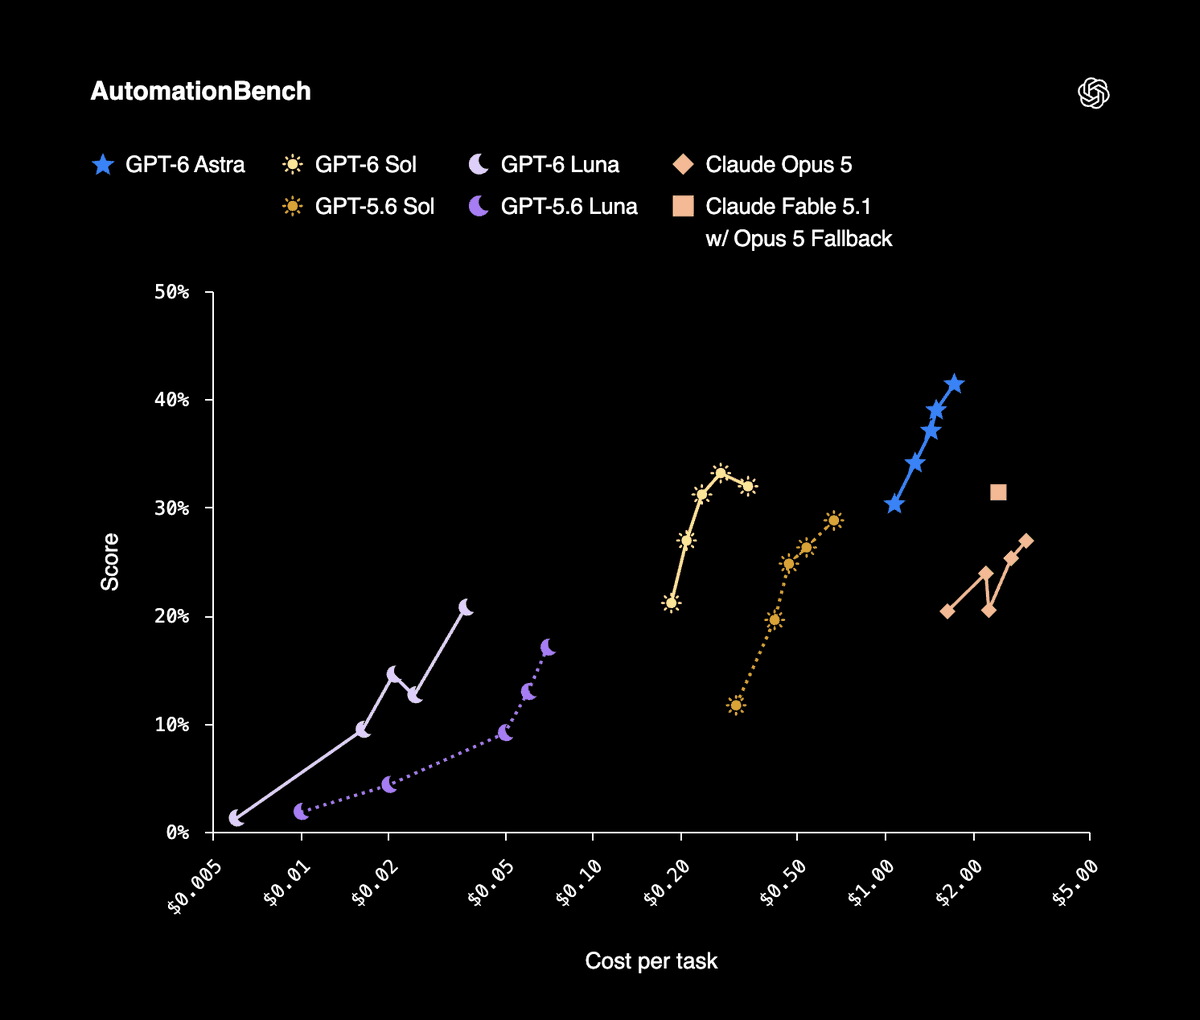
OpenAI announced GPT-6 Sol and Luna. They bring much of GPT-6 Astra’s strengths into faster, more affordable models, with API prices 50% lower than GPT-5.6 promotional pricing, and are rolling out in ChatGPT Work, Codex, and the API.

Key Takeaways

  • OpenAI announced GPT-6 Sol and Luna. They bring much of GPT-6 Astra’s strengths into faster, more affordable models, with API prices 50% lower than GPT-5.6 promotional pricing, and are rolling out in ChatGPT Work, Codex, and the API.
Read full story
Linked Models & Agents:

OpenCode adds GPT-6 Sol, GPT-6 Luna, and Claude Opus 5.5 the same day

Open-source coding agent OpenCode (@opencode) said GPT-6 Sol, GPT-6 Luna, and Claude Opus 5.5 are now available in OpenCode, wiring the same-day OpenAI and Anthropic launches into an open coding-agent workflow.

Key Takeaways

  • GPT-6 Sol, GPT-6 Luna, and Claude Opus 5.5 are live in OpenCode.
  • Covers the same-day OpenAI and Anthropic model launches.
  • Same-day access for open-source coding-agent users.
Read full story
ADSponsored

OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

OpenAI introduced GPT-6 Sol and GPT-6 Luna, faster and more affordable models that carry forward much of GPT-6 Astra’s strength for work at scale. Caching and inference efficiency cuts yield 50% lower API prices versus GPT-5.6 promotional pricing: Sol is priced at $2/$10 per million tokens for deep reasoning, while high-volume Luna costs just $0.10/$0.50 per million tokens with a 90% prompt caching discount.

OpenAI launches GPT-6 Sol & Luna: dual enterprise workhorses cut API pricing by 50% down to $0.10/M

Key Takeaways

  • Tiered dual-model architecture: Sol for deep reasoning and complex coding agents, Luna for ultra-high-throughput workflows.
  • 50% price slash: Sol at $2/$10 per million tokens; Luna down to $0.10/$0.50 with 90% prompt caching discount.
  • Available immediately in OpenAI API (gpt-6-sol, gpt-6-luna), ChatGPT Work, and Codex.
Read full story
Linked Models & Agents: