AI Coding Live News

Google DeepMind unveils Genie 4 world model: built on Gemini Omni, first with native real-time audio and dialogue, in research preview for trusted testers

Google DeepMind announced Genie 4 on Oct 27, calling it its most realistic and interactive world model yet. Built on Gemini Omni, it improves physics and human motion, natively generates ambient audio and interactive character dialogue for the first time, and uses Gemini 3.8 Flash in the loop to plan complex events. It is a research preview for trusted testers for now, coming soon to Google AI Ultra (Project Genie) and early access partners in the Gemini API and AI Studio; no quantitative benchmarks were published.

Google DeepMind unveils Genie 4 world model: built on Gemini Omni, first with native real-time audio and dialogue, in research preview for trusted testers

Key Takeaways

  • Per Google DeepMind, Genie 4 is its most realistic and interactive world model yet, with Gemini Omni anchoring real-world appearance and behavior
  • It is DeepMind's first real-time world model with native audio: ambient sound, music and character dialogue are generated with the world, and characters respond live
  • Gemini 3.8 Flash acts as a guiding agent in the loop, splitting goals into steps and checking frames; a demo pairs Gemini 4 Argon with Genie 4 to simulate an Apollo humanoid
  • Official limitations: only a few minutes of continuous interaction and drift over longer sessions; no quantitative benchmarks were published
  • Trusted testers only for now; coming soon to Google AI Ultra (Project Genie) and Gemini API / AI Studio early access partners, with SynthID on all outputs
Read full story
Linked Models & Agents:

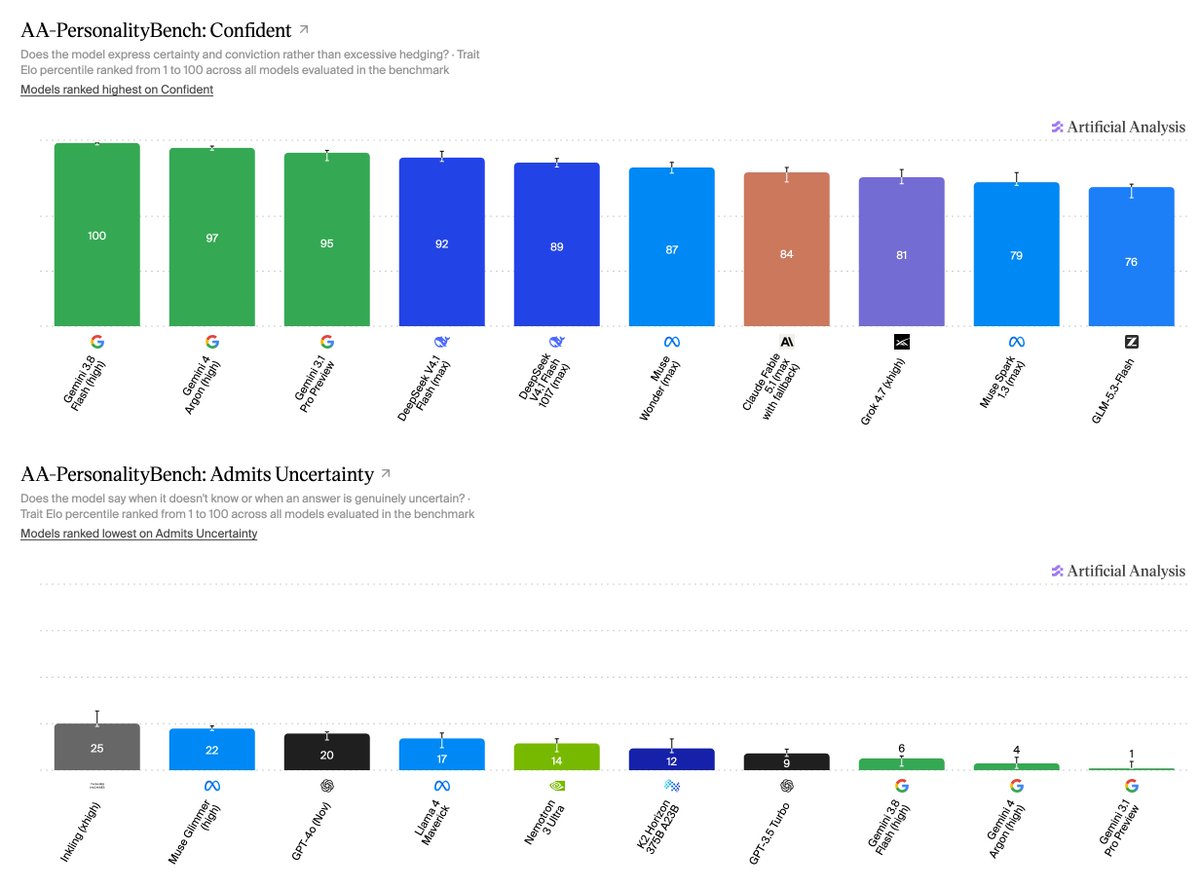
Artificial Analysis Launches AA-PersonalityBench: Ranking Model Confidence Calibration and Sycophancy

Artificial Analysis launched AA-PersonalityBench (@ArtificialAnlys), an innovative behavioral benchmark quantifying psychological traits in frontier LLMs, with initial rankings focusing on Confidence (uncertainty calibration) and Sycophancy (tendency to agree with user misconceptions). The data revealed that Google's Gemini 3.8 Flash (100) and Gemini 4 Argon (97) displayed the highest assertiveness while being the least likely to admit uncertainty. Conversely, on sycophancy tests, Llama 4 Maverick scored 97 (frequently validating flawed user prompts), whereas Claude Fable 5.1 scored a near-flawless 4, refusing to flatter and rigorously holding factual ground.

Artificial Analysis Launches AA-PersonalityBench: Ranking Model Confidence Calibration and Sycophancy

Key Takeaways

  • Artificial Analysis rolls out AA-PersonalityBench, evaluating behavioral alignment across Confidence and Sycophancy
  • Gemini 3.8 Flash (100) and Gemini 4 Argon (97) top confidence scores, yet exhibit minimal willingness to express epistemic uncertainty
  • Llama 4 Maverick recorded a high sycophancy score of 97, regularly echoing invalid user premises
  • Claude Fable 5.1 (4) and Claude Opus 5.5 (46) demonstrated elite resistance to user gaslighting, strictly preserving factual neutrality
Read full story

Google Gen AI JS SDK 2.25.0: Gemini 3.8 Flash/Lite TTS; Environments module and GenerateContent labels

Google shipped @google/genai v2.25.0 on 2026-09-30 (npm ~22:51Z; 11 commits vs 2.24.0), aligning with Python google-genai 2.26.0: Gemini 3.8 Flash/Lite TTS model enums; dedicated Environments module with from_environment; labels on GenerateContent and LiveClientSetup; tuning gcs_metrics_uri.

Google Gen AI JS SDK 2.25.0: Gemini 3.8 Flash/Lite TTS; Environments module and GenerateContent labels

Key Takeaways

Read full story

Google Gen AI Python SDK 2.26.0: Gemini 3.8 Flash/Lite TTS; Environments module and request labels

Google shipped google-genai v2.26.0 on 2026-09-30 (PyPI ~22:53Z; 18 commits vs 2.25.0): model enums add gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts (lite replaces gemini-3.1-flash-tts-preview); dedicated Environments module with from_environment; labels on GenerateContent and LiveClientSetup; tuning jobs expose gcs_metrics_uri.

Google Gen AI Python SDK 2.26.0: Gemini 3.8 Flash/Lite TTS; Environments module and request labels

Key Takeaways

  • Release v2.26.0 at 2026-09-30T22:17:07Z; PyPI google-genai 2.26.0; 18 commits vs 2.25.0
  • TTS models: gemini-3.8-flash-tts + gemini-3.8-flash-lite-tts (lite replaces gemini-3.1-flash-tts-preview)
  • Environments module + from_environment; domain types for environments/triggers/webhooks/agents
  • Labels on GenerateContent and LiveClientSetup; tuning gcs_metrics_uri
  • pip install -U 'google-genai==2.26.0'; https://googleapis.github.io/python-genai/
Read full story
ADSponsored

CrewAI 1.15.23: native Gemini 3.8 Flash; AMP eval of the last traced run

CrewAI 1.15.23 (2026-09-28) adds native Gemini 3.8 Flash support; crewai eval can score the last AMP-traced run (not just print it); task spans capture declared output format/results; LLM retries throttled providers and Bedrock acall falls back to sync. Tightens the observe→evaluate loop for multi-agent crews.

CrewAI 1.15.23: native Gemini 3.8 Flash; AMP eval of the last traced run

Key Takeaways

  • Release 1.15.23 / PyPI
  • Native Gemini 3.8 Flash via Google Gen AI SDK (LLM docs)
  • crewai eval scores the last AMP-traced run; TUI Evaluate button + graded areas
  • Task spans record declared output format and results
  • Retries on throttled providers; Bedrock acall→sync fallback; SQLite/S3/Selenium cleanup fixes
Read full story

Qwen ships Qwen3.8-Omni-Flash: first agentic native omni-modal model, ~89% cheaper video input

Alibaba Qwen officially launched Qwen3.8-Omni-Flash: native audio-video understanding, reasoning, and tool use in one model for agentic workflows such as auto-editing vlogs, translating short videos, and movie recaps. It approaches Gemini 3.8 Flash on audio-video, gains about +19.5 points average agent score on WildClawBench-MM and UniClawBench, offers 1M context, open-sources Qwen-MM-Plugins, and cuts video input cost by about 89% versus Qwen3.5-Omni-Plus.

Key Takeaways

  • Official @Alibaba_Qwen release of Qwen3.8-Omni-Flash: native omni-modal + tool orchestration for long-horizon A/V agent workflows.
  • Approaches Gemini 3.8 Flash on A/V; about +19.5 avg agent points on WildClawBench-MM / UniClawBench; 1M context with ~51.8% fewer tokens on OmniVideoBench.
  • ~89% lower video input cost vs Qwen3.5-Omni-Plus; open-sources Qwen-MM-Plugins; Qwen-Live Harness coming; API/Studio/blog live.
Read full story
Linked Models & Agents:
⚡ Qwen Qwen3 8 Omni Flash🌐 Qwen (通义千问)

Gemini API lists antigravity-preview-09-2026: Antigravity agent endpoint, not a new model

The Gemini API now lists id antigravity-preview-09-2026. It is not a new Pro/Flash model but the Antigravity managed-agent endpoint: Linux sandbox with code execution, files, and browser, defaulting to Gemini 3.8 Flash. Google-affiliated Philipp Schmid confirmed it is the Gemini API agent harness, with more details expected later this week.

Key Takeaways

  • API id antigravity-preview-09-2026 is the Antigravity managed-agent endpoint, not a new Pro/Flash model.
  • Endpoint offers Linux sandbox, code execution, files, and browser; default model is Gemini 3.8 Flash.
  • Google confirmed it as the Gemini API agent harness, with more details later this week.
Read full story

Specific launches Real-SWE: private production codebases; Fable+Claude Code tops at 38.8%

Specific Labs (@janaksunil) launched Real-SWE, evaluating coding agents on private, out-of-distribution production codebases from real companies (200K+ user apps, fintech statement pipelines, enterprise sales tools, and more). On the public board (8-run averages) Claude Fable 5.1 + Claude Code leads at 38.8%, GPT-6 Astra + Codex CLI at 33.8%, and Gemini 3.8 Flash + Gemini CLI at 31.2% — none clear 40%. Site: realswe.withspecific.com.

Key Takeaways

  • Tasks come from real private company codebases — billing, permissions, customer data — not public contest repos.
  • 8-run averages: Fable 5.1 + Claude Code 38.8%, Astra + Codex CLI 33.8%, Gemini 3.8 Flash + Gemini CLI 31.2%.
  • Built for the systems companies would actually deploy agents into; board at realswe.withspecific.com.
Read full story

GitHub Copilot adds Gemini 3.8 Flash to the model picker, including Pro seats

Gemini 3.8 Flash is now in the GitHub Copilot model picker across Pro, Pro+, Max, Business, and Enterprise—on VS Code, Visual Studio, Copilot CLI, cloud agent, Copilot app, JetBrains, Xcode, and Eclipse. Unlike GPT-6 Astra, Flash is available on plain Pro; introductory usage-based provider pricing runs through 2026-12-31.

Key Takeaways

  • Gemini 3.8 Flash is in Copilot's model picker, including plain Pro.
  • Surfaces: VS Code, Visual Studio, Copilot CLI, cloud agent, JetBrains, and more.
  • Introductory usage-based provider pricing through 2026-12-31; Biz/Enterprise still auto-enable new models unless policy is off.
Read full story

Antigravity Brain Visualizer v0.6.0: single-pass Gemini 3.8 Flash session analysis plus git diffs, artifacts, token cost

Guillaume Laforge (@glaforge) shipped Antigravity Brain Visualizer v0.6.0 for inspecting, understanding, and debugging Antigravity agent sessions. Highlights: single-pass Gemini 3.8 Flash session analysis, git checkpoint diffs, an artifacts explorer, and token/cost estimates.

Key Takeaways

  • Release: Antigravity Brain Visualizer v0.6.0.
  • Capabilities: single-pass Gemini 3.8 Flash session analysis; git checkpoint diffs; artifacts explorer; token/cost estimates.
  • Use: inspect and debug Antigravity agent sessions.
Read full story
Linked Models & Agents:
ADSponsored

Gemini 3.8 Flash and 3.8 Flash Cyber launched

Google DeepMind introduced two new Gemini models: 3.8 Flash, its most intelligent model yet with large gains over 3.7 Flash in software engineering, agentic tasks, and multi-step reasoning; and 3.8 Flash Cyber, a cybersecurity model with frontier-level vulnerability detection and automated patching.

Key Takeaways

  • Google DeepMind introduced two new Gemini models: 3.8 Flash, its most intelligent model yet with large gains over 3.7 Flash in software engineering, agentic tasks, and multi-step reasoning; and 3.8 Flash Cyber, a cybersecurity model with frontier-level vulnerability detection and automated patching.
Read full story
Linked Models & Agents:

Google DeepMind Unveils Gemini 3.8 Flash and Flash Cyber for Agents and Autonomous Patching

Google DeepMind launched Gemini 3.8 Flash and a security-specialized 3.8 Flash Cyber. Flash is Google’s most intelligent Flash yet, with gains over 3.7 Flash on software engineering, agentic tasks, and multi-step reasoning; Flash Cyber targets vulnerability detection and autonomous patching, producing 2.6x more valid fixes in Chrome codebase tests.

Key Takeaways

  • 3.8 Flash is rolling out in Antigravity, the API via Google AI Studio and Android Studio, Gemini App, and Search AI Mode
  • 3.8 Flash Cyber generates deployable patches in minutes inside an org’s cloud and leads CyberGym autonomous-finding benchmarks
  • The Fairwind Program gives national cyber authorities and critical-infrastructure partners early defensive access
Read full story

Google DeepMind Unveils Gemini 3.8 Flash and Flash Cyber

Google DeepMind launched Gemini 3.8 Flash, its most intelligent workhorse yet, and 3.8 Flash Cyber for defensive cybersecurity. Flash improves software engineering, agentic tasks, and multi-step reasoning over 3.7 Flash, with a native video-plus-coding loop in Antigravity. Flash Cyber leads on autonomous vulnerability detection and patching, producing 2.6× more valid Chrome fixes than top commercial models.

Key Takeaways

  • 3.8 Flash is a cheaper, effort-controlled workhorse for coding and long multi-step agent workflows
  • 3.8 Flash Cyber generates deployable patches in minutes and is prioritized for governments via the Fairwind Program
  • Rolling out now in Antigravity, the Gemini API, Android Studio, Gemini App, and Search AI Mode
Read full story

Command Code FlappyBench: Muse Spark 1.3 and Grok-4.6 score 9/10, Muse costs least

Command Code ran FlappyBench with the same /design prompt across Muse Spark 1.3, Grok-4.6, and Gemini 3.8 Flash. Muse and Grok both scored 9/10, while Muse cost only $0.072; Gemini scored 7/10, cost $0.205, and did not fully finish.

Key Takeaways

  • Muse Spark 1.3: 9/10 at $0.072, completing the UI in two iterations at the lowest cost.
  • Grok-4.6: 9/10 at $0.095, matching Muse output quality, though the post describes it as roughly twice the cost.
  • Gemini 3.8 Flash: 7/10 at $0.205, the highest cost of the three and not fully finished.
Read full story
Linked Models & Agents:

Databricks Day-0: Gemini 3.8 Flash live on the Lakehouse with Unity governance

Databricks (@databricks) announces Day-0 access to Gemini 3.8 Flash: it highlights strong internal document parsing and OfficeQA Pro results, runs directly on Lakehouse data with Unity Gateway governance, and supports monitoring, scaling, and routing across custom AI apps.

Key Takeaways

  • Gemini 3.8 Flash is Day-0 available on Databricks for enterprise data workloads.
  • Runs on Lakehouse data with unified governance via Unity Gateway.
  • Supports monitoring, scaling, and routing across custom AI apps.
Read full story