AI Coding Live News

DeepSeek Open-Sources DeepInfer Inference Engine: Powering V4.1-Flash at Scale Across NVIDIA SM100 and Huawei Ascend 950

DeepSeek officially open-sourced DeepInfer under Apache 2.0, its production-grade inference engine serving DeepSeek-V4.1-Flash at scale. Originating from vLLM with architectural refinements from SGLang and TensorRT-LLM, DeepInfer natively targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. It integrates specialized kernels including FlashMLA, DeepGEMM, DeepEP, and TileKernels. The engine features DSpark confidence-scheduled speculative decoding with 5-token drafts, SWA bounded replay over a 140-token sliding window, and balanced MoE expert parallelism. DeepSeek simultaneously open-sourced deepseek-recipe, delivering an end-to-end open ecosystem across models, kernels, and inference runtimes.
DeepSeek Open-Sources DeepInfer Inference Engine: Powering V4.1-Flash at Scale Across NVIDIA SM100 and Huawei Ascend 950

Key Takeaways

  • DeepSeek officially open-sourced DeepInfer under Apache 2.0, releasing the production codebase powering DeepSeek-V4.1-Flash at massive scale
  • Natively optimized for both NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs with deterministic, batch-independent output guarantees
  • Integrates custom FlashMLA, DeepGEMM, DeepEP, and TileKernels, alongside DSpark 5-token speculative decoding and 140-token SWA replay
  • Simultaneously released deepseek-recipe, aligning open-source local deployments perfectly with DeepSeek's official production API tokenization
Read full story

DeepSeek open-sources DeepInfer, the inference framework behind its V4.1-Flash production service, with speculative decoding, batch-invariant inference and structured outputs, plus the deepseek-recipe API encoding library

On Oct 20 (UTC) DeepSeek open-sourced DeepInfer (Apache 2.0), the in-house inference stack that serves DeepSeek-V4.1-Flash at scale. The release covers offline inference with Attention DP/CP and MoE EP+EPLB parallelism, DSpark speculative decoding, SWA bounded replay, batch-invariant inference, deterministic sampling and structured outputs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. The KV cache system, prefill/decode disaggregation and load balancing are not included. DeepSeek also released deepseek-recipe (MIT), which converts Chat Completions, Messages and Responses requests and encodes them the same way the official API does.

DeepSeek open-sources DeepInfer, the inference framework behind its V4.1-Flash production service, with speculative decoding, batch-invariant inference and structured outputs, plus the deepseek-recipe API encoding library

Key Takeaways

  • DeepInfer is Apache 2.0 and, per DeepSeek, is the framework serving DeepSeek-V4.1-Flash in production; it currently supports only that model
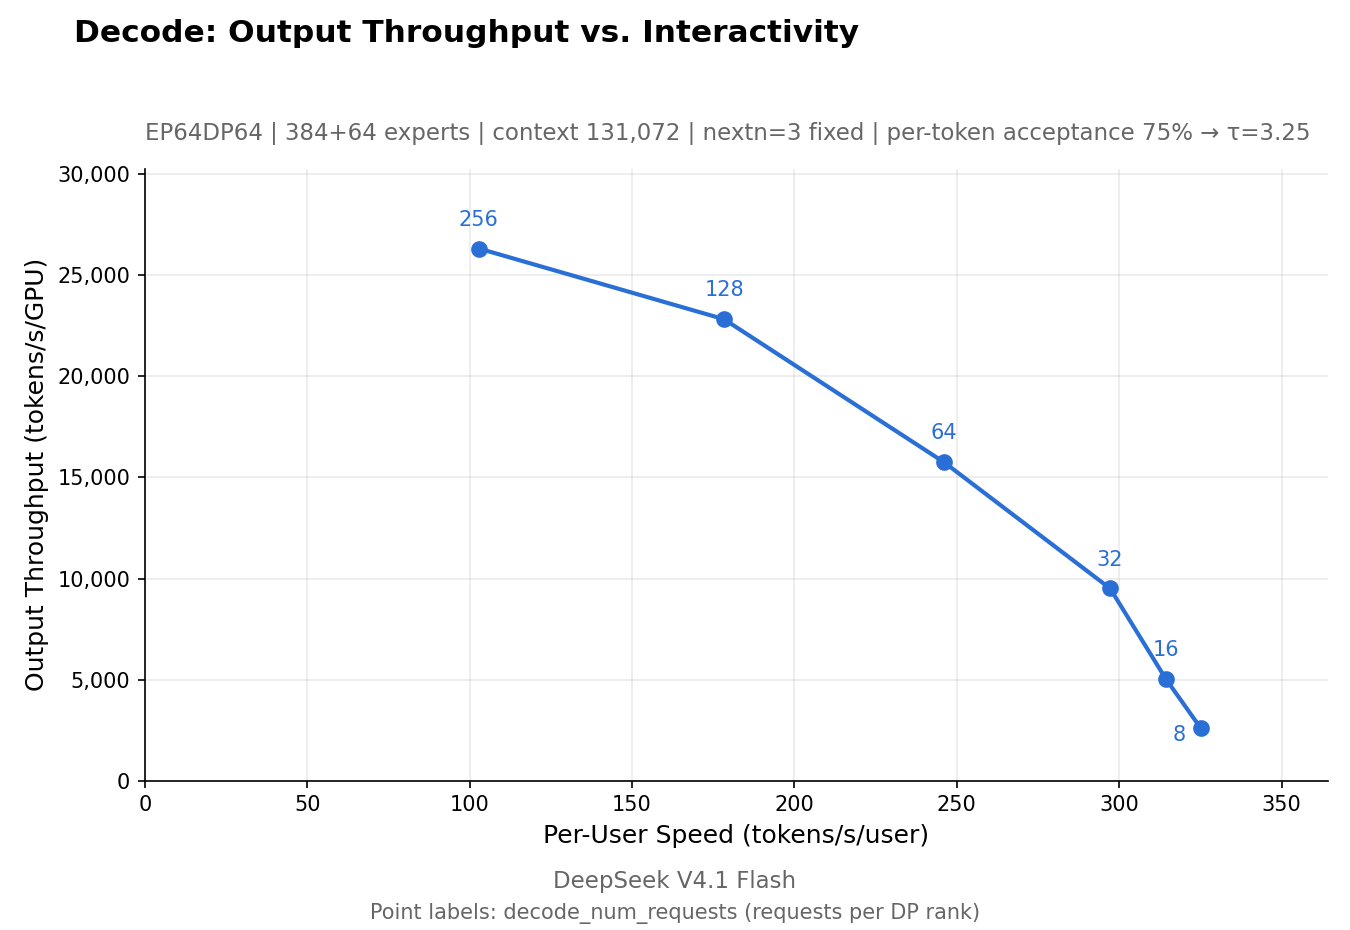
  • Hardware is limited to NVIDIA SM100 (Blackwell) GPUs and Huawei Ascend 950 NPUs; the official Pareto curves were measured on 4 GPUs for prefill and 64 for decode
  • The open release omits the KV cache system, VE/prefill/decode disaggregation and cross-replica load balancing, so it is not a full serving stack yet
  • DeepSeek's reference V4.1 scores (Pass@1, vendor-reported): AIME 2026 99.9%, GPQA Diamond 93.4%, HLE-Full 42.6%, meant as a deployment sanity check
  • deepseek-recipe (MIT, Rust with Python bindings) handles Chat Completions/Messages/Responses conversion and token encoding/decoding
Read full story
Linked Models & Agents:
⚡ DeepSeek-V4.1-Flash-1017🌐 DeepSeek🌐 NVIDIA🌐 Huawei

DeepSeek Scales Ascend Compute Clusters; 552B Asymmetric MoE Model Reaches Record Throughput

DeepSeek disclosed large-scale deployments of Huawei Ascend clusters across its new AI data centers. Paired with its 552B-parameter asymmetric MoE model DeepSeek-V4.1-Flash, the architecture achieved record inference throughput and memory efficiency on domestic silicon.

Key Takeaways

  • Deploys Huawei Ascend AI accelerators at scale to secure hardware sovereignty
  • 552B asymmetric MoE architecture sets new standards for inference speed and vision-code reasoning
  • Reaffirms DeepSeek global leadership in cost-performance and open-weights efficiency
Read full story