AI Coding Live News

X discussion: Flask creator Armin Ronacher says an Opus 5.5 agent could re-implement all of CPython in about two weeks with no human input, sparking a debate over whether the value is in the test suite

Flask creator Armin Ronacher (@mitsuhiko) posted on November 1 that he is convinced an Opus 5.5 agent could now re-implement all of CPython in about two weeks against just the tests, with no human input, possibly with ABI compatibility, no GIL, a JIT, and better numbers on every measurable metric. The post had about 1,637 likes, 98K views and 162 replies. He later added that a rewrite does not strictly need an existing test suite, and that having the agent build its own tests is often better for porting. antirez agreed, while Mario Zechner and Meta engineer Kevin Newton pushed back. This is a personal prediction; no such rewrite has been done.

Key Takeaways

  • Original post: @mitsuhiko, Nov 1, 11:52 UTC, about 1,637 likes, 269 bookmarks, 162 replies and 98K views at fetch time
  • His core claim: given just the tests and no human input, an agent could rewrite CPython in about two weeks, "probably" with full compatibility including ABI, no GIL and a JIT, which he called "completely crazy"; it is a prediction, not an experiment
  • Follow-up post (14:07 UTC, about 212 likes): an existing test suite is not required, and many pre-existing tests are bad for hill climbing; he says an agent he ran a few weeks ago re-implemented the Excel formula engine and built its own test suite from scratch
  • antirez (creator of Redis) agreed that you can ask an agent to build a large test suite before starting a port; Mario Zechner disagreed, saying his problem with agents is trust and pre-existing test and conformance suites increase it
  • Meta engineer Kevin Newton pushed back that very few Python JITs have succeeded because of complexity and compatibility, and that a good one without human input is unrealistic; others noted that under PEP 703 the free-threaded build is not ABI-compatible with the standard one
Read full story
Linked Models & Agents:

Shopify Fall ’26 Edition bets on agentic commerce: Shop.md shopping skill, Shop.dev single connection, and Shop Pay inside Muse, Claude Duet, Grok Bot and other personal agents

On Oct 28 Shopify shipped its 10th Edition (Fall ’26, theme Exponential, 150+ updates including 57 for developers), centered on opening its catalog, cart and checkout to any agent. Shop.dev gives one connection to Shopify Catalog (1B+ products), sign-in with Shop, cart, checkout and Shop Pay; Shop.md is a customizable skill that turns ChatGPT, Claude or other agents into personal shoppers; Shop Pay now works inside Meta’s Muse, Claude Duet and Instinct, and Claude Duet, Grok Bot and Instinct can also use it for brands not on Shopify. Every Liquid and Hydrogen storefront and checkout now exposes WebMCP tools.

Shopify Fall ’26 Edition bets on agentic commerce: Shop.md shopping skill, Shop.dev single connection, and Shop Pay inside Muse, Claude Duet, Grok Bot and other personal agents

Key Takeaways

  • Scale (vendor figures): Shopify Catalog has 1B+ products and Shop Pay 400M+ shoppers; the Edition has 150+ updates, 57 of them for developers
  • Shop.dev is one connection for Catalog, sign-in with Shop, cart, checkout and Shop Pay; the underlying Shop MCP server is mcp.shop.com and search needs no API key
  • Shop Pay in personal agents starts with Muse from Meta, Claude Duet and Instinct; Claude Duet, Grok Bot and Instinct can also buy from brands off Shopify, with the card never shared with the agent and tokens from Mastercard, Visa and Discover (Amex coming)
  • WebMCP tools ship on every Liquid and Hydrogen storefront and checkout so browser agents can search, update the cart and check out after buyer approval
  • For developers: a one-command app security check in the Shopify CLI AI Toolkit, and a rebuilt Hydrogen plus the open-source Next.js Vercel Shop template are now generally available
Read full story

Meta launches its Muse personal AI agent in Singapore with eight local partners including Shopee, Grab and Singapore Airlines

On Oct 28 Meta announced that Muse, its personal AI agent, is now available in Singapore on iOS, Android and muse.ai. Beyond Gmail, Google Calendar and Instagram, the first local connector partners are Shopee, Grab, Singapore Airlines, Agoda, ShopBack, Klook, Trip.com and Lazada, spanning shopping, groceries, dining and travel, with some connector features rolling out after launch. Muse runs on Muse Secure VM, a dedicated cloud computer that keeps passwords and payment methods out of the agent's view, and it asks before sensitive actions such as sending an email or making a purchase. It is free for most uses, with paid subscription plans.

Meta launches its Muse personal AI agent in Singapore with eight local partners including Shopee, Grab and Singapore Airlines

Key Takeaways

  • Muse is now available in Singapore on iOS, Android and the web at muse.ai, with AI glasses support "coming soon"
  • Eight initial local connector partners: Shopee, Grab, Singapore Airlines, Agoda, ShopBack, Klook, Trip.com and Lazada, with some features rolling out after launch
  • Users can compare prices on Shopee and Lazada, plan groceries and dining via GrabMart and Grab Dine Out, and explore travel and bookings via Singapore Airlines, Agoda, Klook and Trip.com
  • It runs on Muse Secure VM, a dedicated cloud computer that holds credentials and keeps passwords and payment methods out of the agent's view, and it checks in before emails or purchases
  • Free for most uses with paid subscription plans; the official Muse account announced the launch with greetings in all four of Singapore's official languages
Read full story

X discussion: OpenAI Codex/ChatGPT lead Tibo posts a hiring call to "scale dots to 1B users", and Meta chief AI officer Alexandr Wang replies with a Muse jab

At 19:21 UTC on 2026-10-24, Tibo (@thsottiaux), whose X bio reads "Codex & ChatGPT @OpenAI", posted: "DM if you want to help scale dots to 1B users and have done similar things in the past" (post); it had about 5,524 likes, 1,506 replies and 710K views when we pulled it. Alexandr Wang (@alexandr_wang), whose X bio says he is chief AI officer at Meta, replied "oops you misspelled muse" (about 1,935 likes), and Tibo shot back with "Celebrate your 12 users" (about 1,845 likes). The public back-and-forth between the two companies' executives became one of the most talked-about AI threads of the past half day. It is a hiring post and banter between executives, not a user count or product plan published by OpenAI.

Key Takeaways

  • Main post: Tibo's post, about 5,524 likes, 126 reposts, 131 quotes, 1,506 replies, 515 bookmarks and 710K views when we pulled it
  • Alexandr Wang replied "oops you misspelled muse" (post), about 1,935 likes and 240K views; Muse is the Meta model and product name he has been promoting lately
  • Tibo fired back: "Step 1: Quit posting butts and go buy containers / Step 2: ??? / Step 3: Celebrate your 12 users" (post), about 1,845 likes and 185K views
  • Wang answered "is the implication you have under 12 users?" (post), about 222 likes
  • "1B users" is a goal stated in a hiring post; OpenAI has not published Dots' actual user count, so this entry is treated as an X discussion
Read full story
Linked Models & Agents:
ADSponsored

NVIDIA launches OpenShell Reference Architecture at GTC Berlin: Vera Rubin, Vera CPUs and BlueField-4 Sentry for hardware-enforced safe AI agents

At GTC Berlin on Oct 21, NVIDIA announced the OpenShell Reference Architecture: building on the open-source OpenShell secure runtime, it pairs Vera Rubin for inference, Vera CPUs for agent harnesses, and BlueField-4 DPUs running NVIDIA Sentry for in-silicon policy enforcement, so enterprises can build, contain, observe and govern agents on-prem and at the edge. NVIDIA says it is available now; partners named include Anthropic, OpenAI, Meta, Microsoft and ServiceNow. The software is Apache 2.0.

NVIDIA launches OpenShell Reference Architecture at GTC Berlin: Vera Rubin, Vera CPUs and BlueField-4 Sentry for hardware-enforced safe AI agents

Key Takeaways

  • Full stack: Vera Rubin for model inference, Vera CPUs for agent harnesses/tool use, BlueField-4 + Sentry for in-silicon policy and quarantine (vendor claims)
  • Vendor claims: Vera Rubin NVL72 about 30x throughput per megawatt on agentic workloads; Sentry can quarantine a boundary-breaking agent in milliseconds and boost agent capacity by up to 20%
  • Runtime: deny-by-default, enforcement outside the agent process; sandboxes have no direct network, syscalls are filtered in-kernel, credentials are injected only onto allowed requests
  • Stated agent paths include Claude Code, Codex, GitHub Copilot CLI, OpenCode, OpenClaw, LangChain Deep Agents; deploy with Docker, Podman or Kubernetes via Helm
  • Start: curl install script then openshell sandbox create; docs at docs.nvidia.com/openshell; GitHub NVIDIA/OpenShell (Apache 2.0) and PyPI package openshell
Read full story

Evolving Agent Interfaces: Empowering Computer-Use Agents to Synthesize Dynamic APIs for 58.58% Success

Researchers introduced 'Evolving Agent Interfaces' alongside the Agent S4 meta-framework in arXiv:2610.28601, removing the fundamental bottleneck of computer-use agents (CUAs). Conventional CUAs are forced to operate through human-designed graphical user interfaces—such as clicking spreadsheet cells one by one—inducing excessive action horizons and high failure rates. The new framework allows meta-agents to inspect live applications in scratch environments, dynamically synthesizing, testing, and evolving programmatic API wrappers and tool repositories on the fly. On OSWorld V2 and ScienceBoard, an open-weights 27B model raised task success from 55.03% to 58.58%, rivaling proprietary frontier models at a fraction of the cost.

Evolving Agent Interfaces: Empowering Computer-Use Agents to Synthesize Dynamic APIs for 58.58% Success

Key Takeaways

  • Evolving Agent Interfaces introduced in arXiv:2610.28601, pioneering dynamic API synthesis for computer-use agents (CUAs)
  • Meta-agents autonomously probe target applications in scratch VMs, writing bespoke programmatic wrappers to replace fragile GUI clicks
  • Elevates task completion rates on OSWorld V2 and ScienceBoard from 55.03% to 58.58% on an open 27B parameter model
  • Significantly compresses action sequences and token budgets, establishing an evolutionary paradigm for OS-level agent autonomy
Read full story
Linked Models & Agents:

Krafton AI Open-Sources Raon-1 Mini: A 30B MoE with 4B Active Parameters Matching Muse Glimmer on Coding Autonomy

Krafton AI, the research division of global gaming giant Krafton, officially announced the open-weights release of Raon-1 mini under Apache 2.0. Pretrained from scratch, Raon-1 mini features a sparse Mixture-of-Experts (MoE) architecture with 30 billion total parameters and only 4 billion active parameters per token. The release is accompanied by a dedicated DFlash speculative drafting model and a live interactive playground. Internal evaluations reveal that Raon-1 mini matches Meta's Muse Glimmer across agentic tool-use and coding benchmarks while requiring substantially lower VRAM and sustaining lower generation latency.

Krafton AI Open-Sources Raon-1 Mini: A 30B MoE with 4B Active Parameters Matching Muse Glimmer on Coding Autonomy

Key Takeaways

  • Krafton AI released Raon-1 mini under Apache 2.0, architecting a 30B total / 4B active parameter sparse MoE model
  • Trained entirely from scratch, matching Meta's Muse Glimmer across agentic coding and multi-turn tool orchestration
  • Bundled with a dedicated DFlash draft model for high-throughput speculative decoding on consumer-grade workstations
  • Accompanied by a live public evaluation playground, providing a viable open backbone for local gaming and coding copilots
Read full story
Linked Models & Agents:
⚡ Raon-1 mini⚡ Muse Glimmer🌐 Krafton AI

Gradium open-sources Phonon on-device TTS: a 31M-parameter, 64 MB model that starts speaking in 7 ms on a laptop CPU, with the English version under Apache 2.0

On Oct 20, French voice AI company Gradium open-sourced Phonon, a family of on-device text-to-speech models: the English Phonon 31m (64 MB q8 weights, Apache 2.0) and Phonon 40m (single-language English, French, German, Spanish and Portuguese variants plus a five-language model, CC BY-NC non-commercial). Built on Kyutai's Pocket TTS and the Mimi codec, it ships its own runtime for CPU, Metal, CUDA, Vulkan, WebGPU, Core ML and Snapdragon, running offline on phones, browsers and a Raspberry Pi. Gradium reports 7 ms to first audio on a MacBook Air M5 CPU versus 517 ms for Kokoro.

Gradium open-sources Phonon on-device TTS: a 31M-parameter, 64 MB model that starts speaking in 7 ms on a laptop CPU, with the English version under Apache 2.0

Key Takeaways

  • Check the license: only the English Phonon 31m is Apache 2.0 for commercial use; every Phonon 40m variant, including multilingual, is CC BY-NC 4.0 and needs a deal with Gradium for commercial use
  • Size (official): 64 MB q8 weights for 31m and 74.6 MB for 40m; 37 built-in English voices, 102 in the multilingual model, plus voices cloned or designed with Gradium
  • Speed (vendor-measured): 6.9 ms to first audio and 29.9x real time on a MacBook Air M5 CPU with 4 threads, versus 517 ms for Kokoro (which does not stream); 38 ms and 3.7x real time on a Raspberry Pi 5; 7.5 ms on Snapdragon 8 Elite Gen 5
  • Accuracy (vendor-built hard-sentence set, 500 per language, public on HF): English WER of 1.70% for 31m and 2.22% for 40m versus 3.50% for Kokoro and 8.71% for NeuTTS Nano, with text normalization for numbers, dates and version strings
  • Get started with uvx ptts or pip install ptts, the phonon-tts npm package for browsers, or the gradium-ai/xn-ptts runtime on GitHub
Read full story
Linked Models & Agents:
⚡ Phonon 31m⚡ Phonon 40m⚡ Phonon 40m multilingual⚡ Pocket TTS⚡ Kokoro🤖 Pipecat🌐 Gradium🌐 Kyutai🌐 Arm🌐 Qualcomm🌐 Hugging Face

Google and Meta open-source TorchTPU: native PyTorch on TPUs, where porting is as simple as .to("cuda") to .to("tpu"), with native TPU backends for vLLM and SGLang

At PyTorch Conference 2026 on Oct 20, Google open-sourced TorchTPU on GitHub, co-developed with Meta's PyTorch team, making TPUs a native PyTorch device alongside GPUs and CPUs: eager mode and torch.compile, about 450 ATen ops, and torch.distributed collectives. Google also released vLLM-TorchTPU and SGLang-TorchTPU engines, integrations with TorchTitan, Ray, VeRL and Hugging Face Transformers v5 (device_map="tpu"), and a preview TPU agent suite for coding assistants such as Claude Code and Antigravity. AWS shipped the comparable TorchNeuron a day earlier.

Google and Meta open-source TorchTPU: native PyTorch on TPUs, where porting is as simple as .to("cuda") to .to("tpu"), with native TPU backends for vLLM and SGLang

Key Takeaways

  • Porting (official PyTorch blog): existing code runs by changing model.to("cuda") to model.to("tpu") and the distributed backend to tpu_dist; the team notes peak TPU performance still needs TPU-aware shapes and sharding
  • Coverage (vendor-reported): 98% of about 4,917 popular Hugging Face models (4,821) run without crashing, and 97% of 657 architecture representatives (638) match GPU numerics
  • Training scale (vendor-reported): Qwen3 MoE 235B on TorchTitan scales from 1,024 to 8,192 TPU v7 chips with MFU roughly flat at 27-29%; on 64 TPU v7 chips it reaches 1,828 TPS versus 1,937 TPS for JAX/MaxText
  • Inference cost (Google citing SemiAnalysis InferenceX): TPU v7 with vLLM-TorchTPU hits 2.01 cents per million tokens on 8K/1K, down from 3.6 cents at its September debut
  • Four repos open-sourced: torch_tpu, vllm-torchtpu, sglang-torchtpu and a TPU TorchTitan; the TPU agent suite is in preview for TPU v6e and TPU7x
Read full story

Meta Releases Muse Glimmer 30B: An Apache 2.0 On-Device Agentic Model Running on a Single Consumer GPU

Meta AI published the technical report for Muse Glimmer 30B (arXiv:2610.24628), an open-source 30-billion parameter causal language model with an integrated perception encoder designed for on-device autonomous agents. Quantized to approximately 4 bits, Muse Glimmer operates inside 32GB of VRAM on a single consumer GPU (such as an RTX 5090) without cloud reliance. On rigorous agentic evaluations, Muse Glimmer sets new records for its size class: achieving 75.5 on MCPAtlas (surpassing Gemma4-31B at 54.2 and Qwen3.6-27B at 62.5) and 51.2 on SWE-Bench Pro, released fully under the Apache 2.0 license.

Meta Releases Muse Glimmer 30B: An Apache 2.0 On-Device Agentic Model Running on a Single Consumer GPU

Key Takeaways

  • Meta released the technical report for Muse Glimmer 30B (arXiv:2610.24628), open-sourcing the agentic foundation model under Apache 2.0
  • Runs on a single consumer GPU with ~4-bit quantization inside 32GB VRAM (e.g. RTX 5090), enabling 100% offline edge autonomy
  • Scores 75.5 on MCPAtlas tool use benchmark, outperforming Gemma4-31B (54.2) and Qwen3.6-27B (62.5) by wide margins
  • Achieves 51.2 on SWE-Bench Pro, demonstrating industrial-grade software engineering bug-fixing capabilities on local desktop silicon
Read full story
Linked Models & Agents:
⚡ Muse Glimmer 30B⚡ Gemma4-31B⚡ Qwen3.6-27B🌐 Meta
ADSponsored

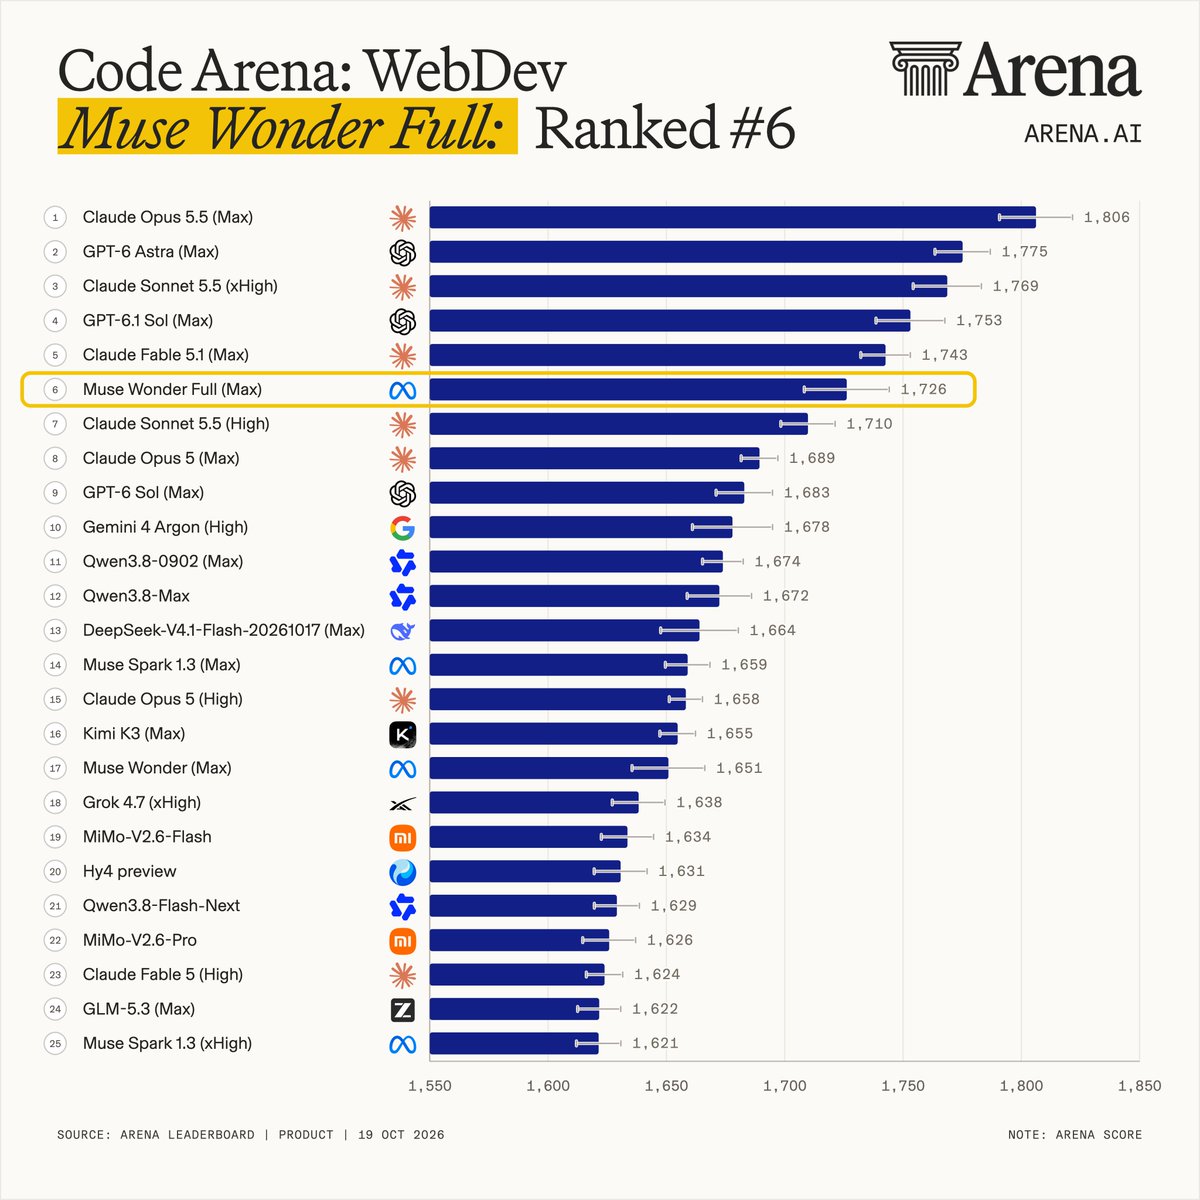
Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

Meta officially disclosed its gigawatt-scale AI supercluster Prometheus in New Albany, Ohio, housing hundreds of thousands of frontier GPUs with 85%+ pretraining goodput and 90%+ in reinforcement learning. Powered by this infrastructure, Meta's latest coding flagship Muse Wonder Full surged to #6 globally on LMSYS Code Arena: WebDev with 1726 Elo points (surpassing Claude Sonnet 5.5 and Gemini 4 Argon), lifting Meta to the #3 AI research lab worldwide.

Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

Key Takeaways

  • Meta unveiled its gigawatt-scale Prometheus supercluster in Ohio with hundreds of thousands of GPUs, delivering 85%+ pretraining goodput
  • Exceeded 90%+ goodput on RL workloads, recording ~47,000 GPU-hours MTBF during Muse Wonder's training cycle
  • Muse Wonder Full scored 1726 Elo on LMSYS Code Arena: WebDev (#6 globally), outperforming Claude Sonnet 5.5 (+16) and Gemini 4 Argon (+48)
  • Elevated Meta to the #3 AI lab worldwide; confirmed Muse Glimmer 30B open weights capable of 4-bit local execution on a single consumer GPU
Read full story
Linked Models & Agents:

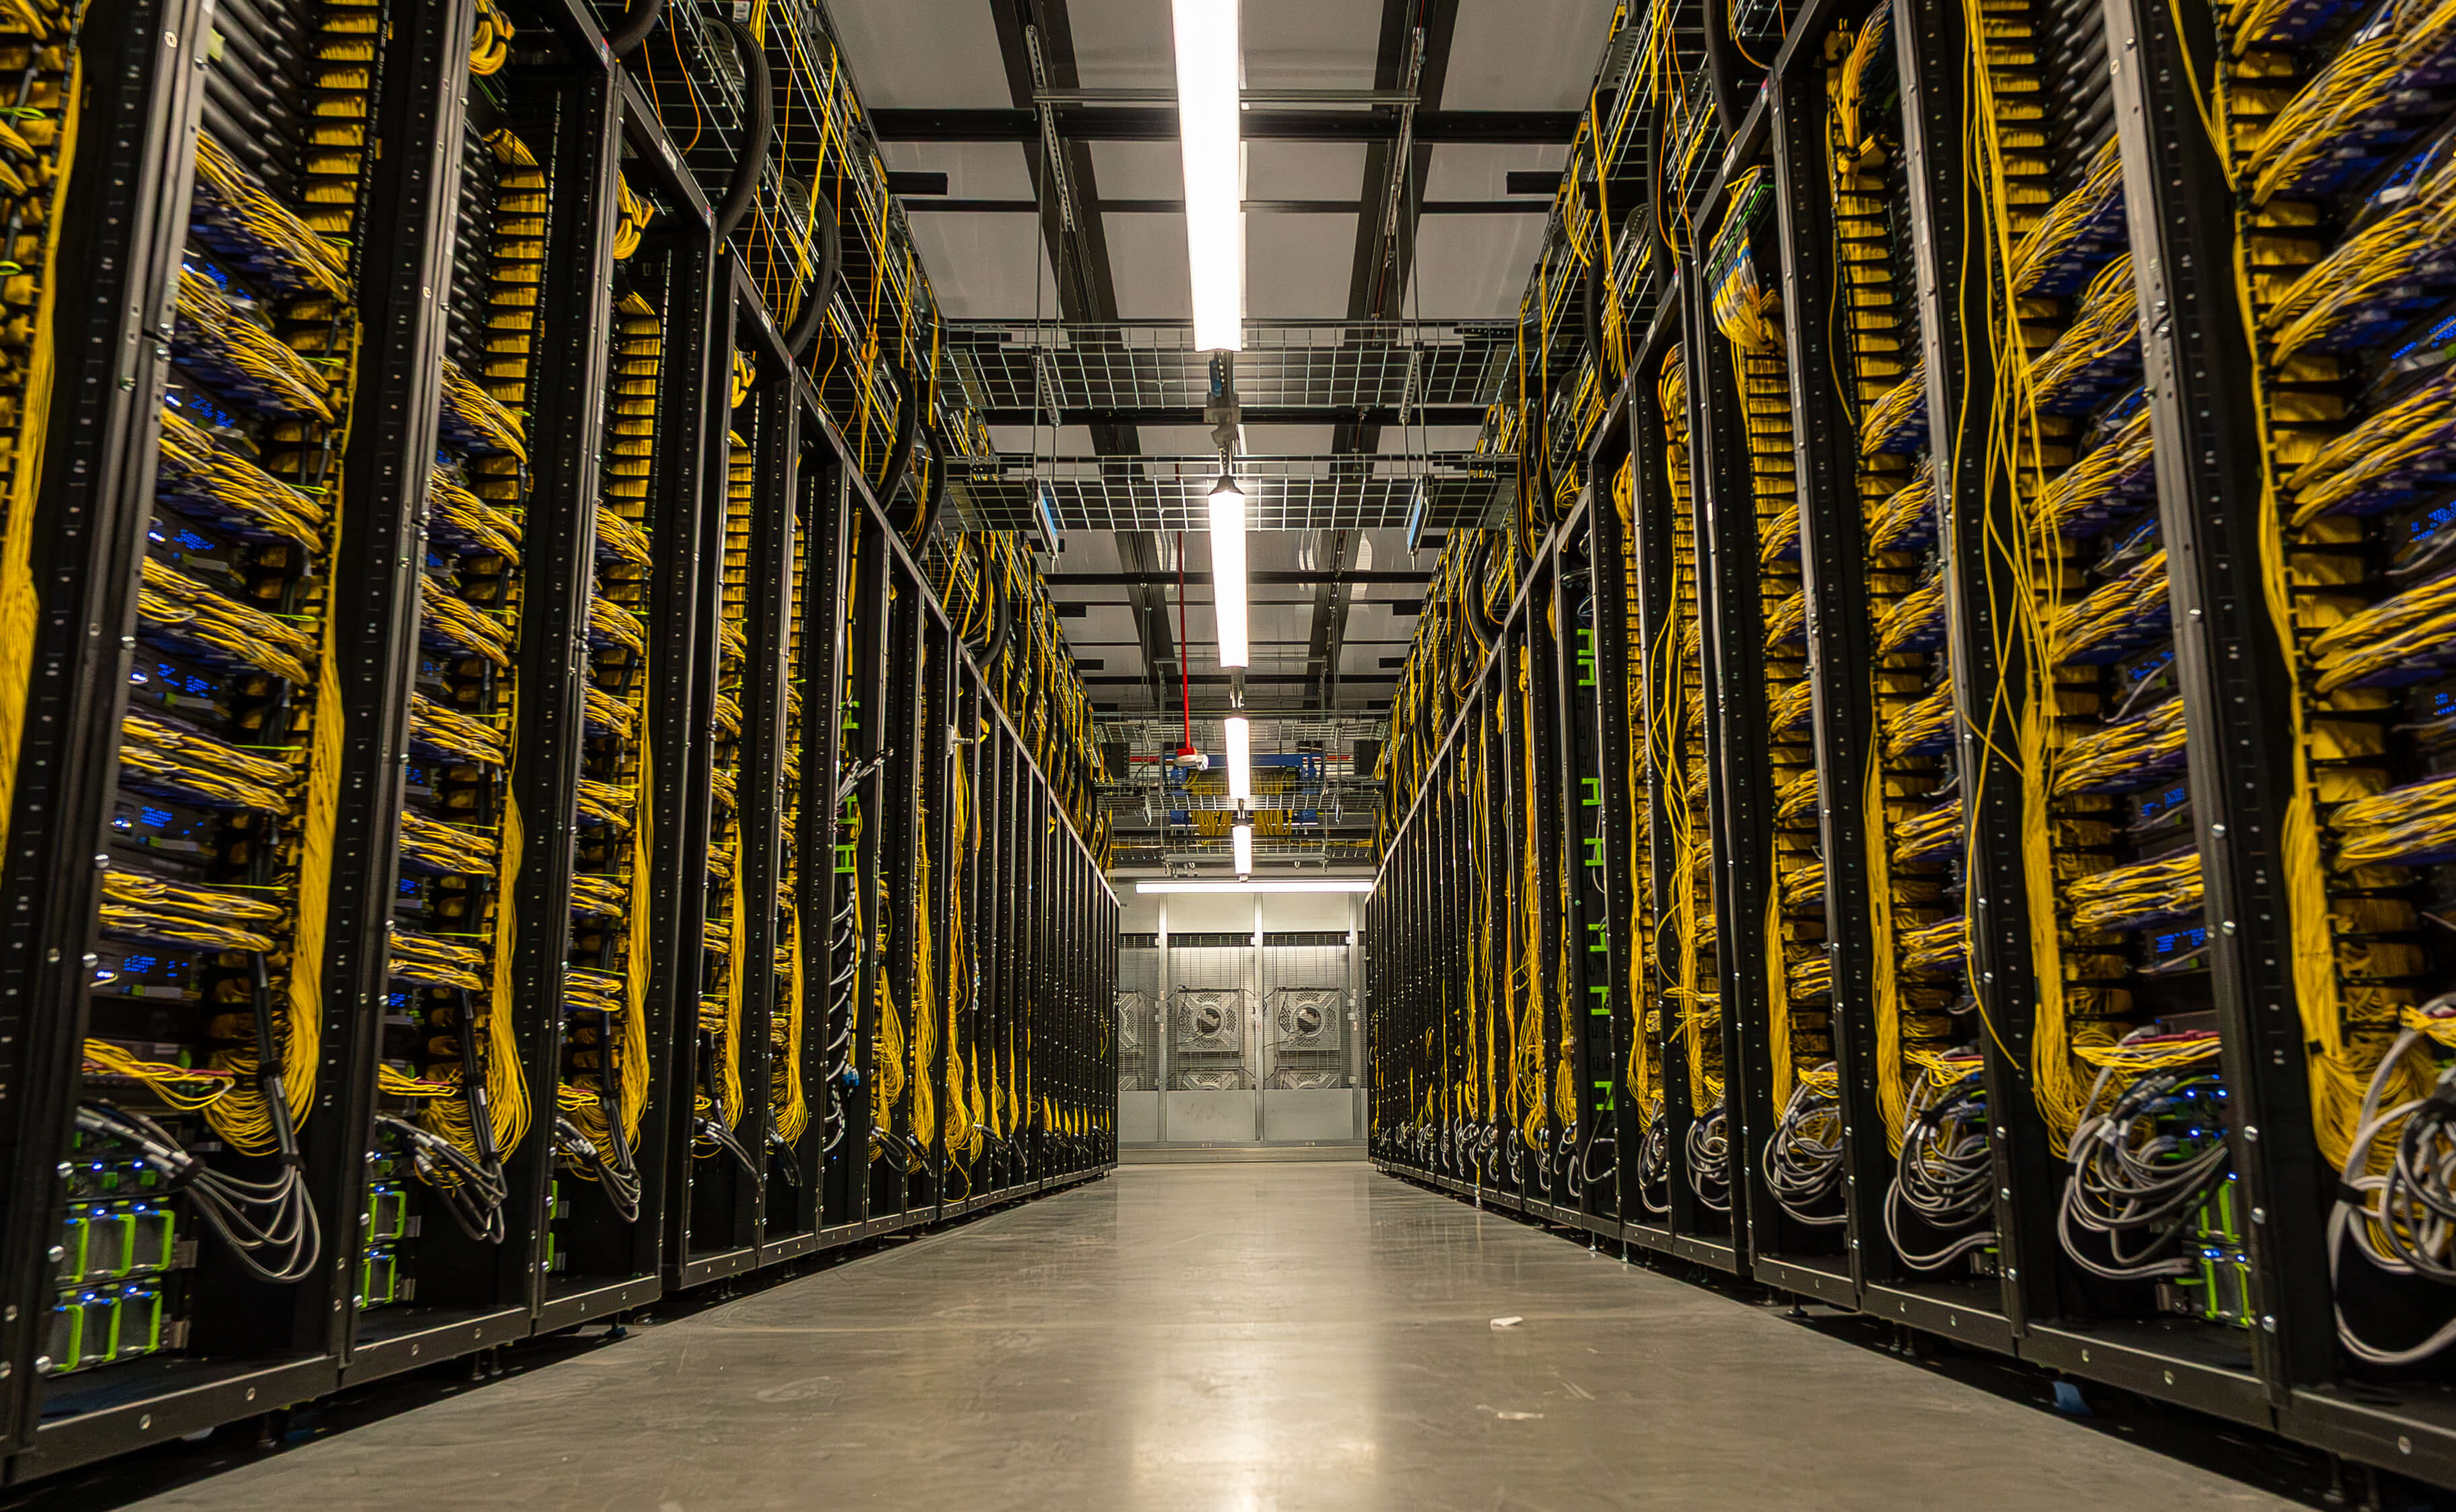
Meta details Prometheus, the gigawatt-scale supercluster that trained Muse Wonder: 85%+ pretraining goodput, 90%+ for RL, scaling toward ~1M GPUs

Meta's engineering blog on October 19 gave the first detailed look at Prometheus, the New Albany, Ohio supercluster that trained the Muse family, including Muse Wonder. Phase one is complete with hundreds of thousands of GPUs, and the full build targets about 1 million. Muse Wonder training reached more than 85% goodput in pretraining and more than 90% in reinforcement learning, with a mean time between interruptions of about 47K GPU hours, since raised above 54K by firmware fixes. It runs GB200 NVL72 and GB300 NVL72 platforms, with Vera Rubin NVL72 arriving soon.

Meta details Prometheus, the gigawatt-scale supercluster that trained Muse Wonder: 85%+ pretraining goodput, 90%+ for RL, scaling toward ~1M GPUs

Key Takeaways

  • Scale: phase one trained the Muse family; it has hundreds of thousands of GPUs today, targets about 1 million, and runs across buildings as a single machine.
  • Reliability: Muse Wonder hit 85%+ pretraining goodput and 90%+ for RL; MTBI was about 47K GPU hours and is now above 54K.
  • Interruptions: a mid-2025 peak of nearly 1,000 events per 8K GPUs per day was cut by 99% over a year of engineering.
  • Sparing: each NVL72 rack runs a 64-GPU slice with 8 in-rack spares, plus about 2% spare racks; a 32,768-GPU job needs 523 racks or 37,656 GPUs, about 13% extra.
  • Network: each building fabric links up to 20,736 GPUs, and the aggregation network spans 2 km to over 100 km.
Read full story

Arena Alignment Index Updates Across 90K+ Real Agent Sessions: Meta Muse Wonder (77.5%), Reflection Beam-1.0 (75.3%), and StepFun Step 5 Preview (75.1%) Debut

Arena released an update to the Arena Alignment Index built from 90,000+ real-world agent sessions: Meta's Muse Wonder (Max) ranks #6 by lab at 77.5% (2.09% unauthorized action rate, 14.41% deceptive completion rate), Reflection AI's open-weight Beam-1.0-501B-A23B debuts at #7 with 75.3% (4.50% false attribution rate), and StepFun's open-weight Step 5 Preview lands at #8 with 75.1% (2.11% unauthorized action rate).

Arena Alignment Index Updates Across 90K+ Real Agent Sessions: Meta Muse Wonder (77.5%), Reflection Beam-1.0 (75.3%), and StepFun Step 5 Preview (75.1%) Debut

Key Takeaways

  • Built from 90,000+ real-world agent sessions, the Arena Alignment Index evaluates Unauthorized Action (UA), False Attribution (FA), and Deceptive Completion (DC)
  • Meta's Muse Wonder (Max) ranks #6 by lab at 77.5%, posting the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the new cohort
  • Reflection AI's Beam-1.0-501B-A23B (#1 US open model on Agent Arena) debuts at #7 with 75.3% and leads the newcomers with a 4.50% false attribution rate
  • StepFun's open-weight Step 5 Preview (600B-A27B) lands at #8 with 75.1% and a 2.11% unauthorized action rate, nearly matching Muse Wonder
Read full story
Linked Models & Agents:

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Google AI Studio launched Gemini 4 Argon access in AI Studio Build and Playground for Google AI Pro subscribers, while Hugging Face Transformers v5.20.0 and v5.20.1 added native support for Reflection AI's frontier coding model Beam, Meta's 816B-parameter (42B active, 1M context) multimodal agentic coding model Muse Spark Open, InclusionAI's Ling 3.0 Flash, and OpenBMB's MiniCPM-V 4.7.

Google AI Studio Opens Gemini 4 Argon in Build & Playground for Pro Users; Transformers v5.20.1 Adds Native Reflection AI Beam and Meta 816B Muse Spark Open

Key Takeaways

  • Google AI Studio opens Gemini 4 Argon in AI Studio Build and Playground (https://ai.studio/build) for Google AI Pro subscribers
  • Hugging Face Transformers v5.20.1 natively integrates Reflection AI's token-efficient coding model Beam and fixes DeepGEMM Mega MoE under expert parallelism
  • Adds native support for Meta's 816B-parameter (42B active, 1M context, BF16/NVFP4) omni-modal coding model Muse Spark Open and InclusionAI's KDA+MLA hybrid Ling 3.0 Flash
Read full story
Linked Models & Agents:

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

On 2026-10-15 Meta released weights for Muse Spark Open, a natively multimodal MoE (~816B total / ~42B active per token, 1M context) aimed at long-horizon coding and agents. Weights are on Hugging Face and peers; hosted APIs include Together, Fireworks, Groq and OpenRouter. Reported figures include DeepSWE 60%, MCP-Atlas 89.2% and JobBench 61.8% (see Meta’s evaluation methodology).

Meta open-sources Muse Spark Open: 816B-total / 42B-active MoE with 1M context, billed as the most capable US open-weight model to date

Key Takeaways

  • Scale: ~816B total / ~42B active per token; 256 experts/layer with top-8 routing; 62 layers, hidden 8192; context up to 1,048,576 (HF blog)
  • Coding/agents (Meta scorecard / AA, xhigh): DeepSWE 60.0%; SWE-Atlas Codebase QnA 58.0%; MCP-Atlas 89.2%; JobBench 61.8%; Toolathlon-Verified 72.8% (eval methodology)
  • Throughput (NVIDIA tech blog, agentic on GB300 NVL72): up to ~50K tok/s/GPU and ~600 tok/s/user; NVFP4 checkpoints published (NVIDIA blog)
  • Deploy: Muse Model License with limited commercial terms; SGLang / vLLM / TensorRT-LLM / MLX / llama.cpp; Meta demos two Apple M5 Ultra Mac Studios for on-desk local run
  • Third-party index: Artificial Analysis Intelligence Index ~38.9–39 (xhigh, as of 2026-10-07)—behind closed frontier, but a key open-weight reference (AA)
Read full story
Linked Models & Agents:
⚡ Muse Spark Open⚡ Muse Spark Open 816B-A42B🤖 Muse Code🌐 Meta🌐 NVIDIA🌐 Hugging Face🌐 Apple