AI Coding Live News

vLLM v0.32.0: 814 commits, built-in /v1/systemone structured-decision endpoint, NVFP4 KV cache on more GPUs, and 43–85% more req/s with multiple API workers

vLLM shipped v0.32.0 on Oct 18 with 814 commits from 363 contributors (121 new). Highlights: a default-served POST /v1/systemone structured-decision endpoint and a generic hf tool/reasoning parser; NVFP4 KV cache on SM8x/SM90/SM12x and FP8 KV by default for GLM-5.x on SM100; Model Runner V2 gains a GPU n-gram speculator and Elastic EP and becomes the ROCm default; three security advisories are fixed, default CORS is restricted, and Python 3.10 is dropped.

vLLM v0.32.0: 814 commits, built-in /v1/systemone structured-decision endpoint, NVFP4 KV cache on more GPUs, and 43–85% more req/s with multiple API workers

Key Takeaways

  • Scale: 814 commits from 363 contributors (121 new); see the release notes.
  • Structured decisions: POST /v1/systemone is new and served by default for choice/score questions, including Cloudflare/clef-omni and LiquidAI/d1-3B; --tool-call-parser hf reads a checkpoint's response_template so no model-specific parser is needed.
  • Low-precision KV: GLM-5.x defaults to FP8 KV on SM100, halving KV memory per rank with 2.3–5.5% more throughput at a 7–11% TTFT cost (PR benchmark, vendor figures); ROCm adds a 4-bit KV cache at about 2x FP8 density.
  • Serving: with --api-server-count above 1, connections go to the least-loaded worker for 43–85% more req/s on short requests (Qwen3-0.6B, 32 in / 1 out tokens, PR benchmark).
  • Breaking: Python 3.10 dropped, default CORS origins restricted, cascade attention removed, and max_tokens is no longer reserved from the context window.
Read full story
v
vLLMvllm-project·
👀136
🔥90

vLLM v0.31.0: 717 commits, `vllm preload` fast restarts, DeepSeek-V4.1-Flash FlashMLA default, security gates and breaking changes

vLLM v0.31.0 (717 commits, 307 contributors, 96 new) adds the vllm preload weight-cache daemon for fast engine restarts and experimental CRIU engine snapshots, makes FlashMLA mega attention with NVFP4 compressed KV the SM100 default for DeepSeek-V4.1-Flash, brings draft-model speculative decoding to Model Runner V2, gates per-request multimodal kwargs behind a flag, and fixes prefix-cache key collisions between LoRA names and cache_salt. Several breaking changes ship too.

Key Takeaways

  • Scale: 717 commits from 307 contributors (96 new).
  • Fast restart: vllm preload keeps post-quantized weights resident in GPU memory across restarts (DP, MTP drafts, /health); experimental CRIU snapshots restore an initialized TP1 engine.
  • Security: per-request multimodal kwargs rejected unless --trust-request-mm-kwargs; LoRA path now part of the block hash to stop prefix-cache collisions.
  • Breaking: tokenizer_mode="slow" removed; online quantization="fp8" replaced by fp8_per_tensor; --enforce-eager also disables JIT warmup.
  • Model paths: GLM-5.3-Flash metadata ops 1.6–4.8x faster and 3 GiB indexer workspace saved; fused KimiViT QK RoPE up to 29x; ~25 s faster Qwen3.8-Flash-Next weight loading on DGX Spark.
Read full story

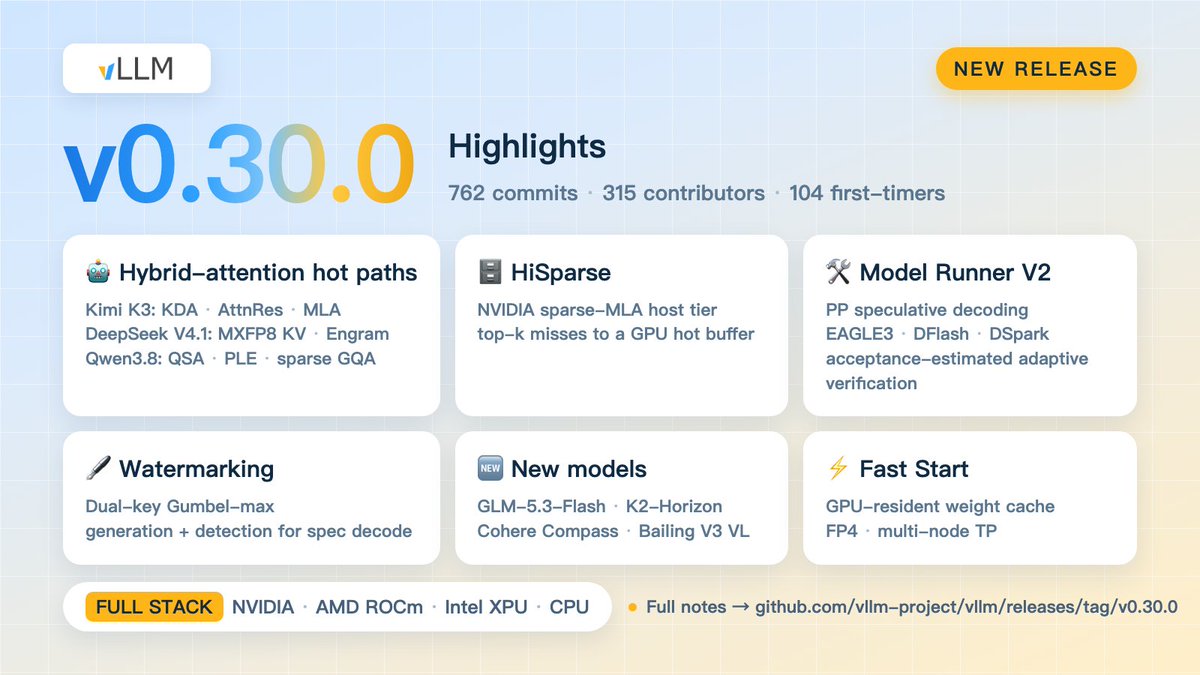
vLLM v0.30.0 ships 762 commits with hot paths for Kimi K3, DeepSeek-V4.1-Flash, Qwen3.8-Flash-Next

The vLLM project (@vllm_project) released v0.30.0 with 762 commits from 315 contributors. Highlights include hybrid-attention hot paths for Kimi K3 (KDA/AttnRes/MLA), DeepSeek-V4.1-Flash (MXFP8 KV and async Engram), and Qwen3.8-Flash-Next (QSA/PLE, lower sparse-GQA overhead); plus HiSparse host-tier decode, Model Runner V2 EAGLE3 pipeline parallelism with adaptive verification, dual-key Gumbel-max watermarking, Fast Start CUDA IPC weight cache, and new models such as GLM-5.3-Flash, K2-Horizon, Cohere Compass, and Bailing V3 VL.

vLLM v0.30.0 ships 762 commits with hot paths for Kimi K3, DeepSeek-V4.1-Flash, Qwen3.8-Flash-Next

Key Takeaways

  • Hybrid-attention hot paths cover Kimi K3, DeepSeek-V4.1-Flash, and Qwen3.8-Flash-Next.
  • Model Runner V2 brings EAGLE3-style drafts to pipeline parallelism with online acceptance estimation.
  • Fast Start maps post-quantized TP-sharded weights over CUDA IPC for faster restarts.
Read full story

vLLM 0.29.0: Model Runner V2 default, Mamba prefix cache, speculative-decoding stats

vLLM shipped v0.29.0 with Model Runner V2 as the default runner for all models (594 commits, 277 contributors). Highlights include another Kimi-K3 optimization pass, DeepSeek-V4 shared experts fused into MegaMoE, Mamba prefix caching that keeps internal prefill checkpoints (about 9–25% better TTFT), per-request speculative-decoding acceptance stats over the API, a sharded_rdt P2P backend for RL weight sync, and new model support such as Hy4-preview, Qwen3.8-Flash-Next, GraniteSWA, and NemotronH Omni Reasoning V3.

Key Takeaways

  • Model Runner V2 is now the default for all models.
  • Mamba prefix caching improves TTFT ~9–25%; speculative decoding exposes acceptance stats via API.
  • DeepSeek-V4 MegaMoE fusion, RL sharded_rdt P2P sync, and several new model backends.
Read full story
Linked Models & Agents:
ADSponsored

vLLM 0.28.0 Released: Kimi-K3 Full-Stack Optimizations, DeepSeek-V4 Sparse MLA, and 65% TTFT Boost

vLLM 0.28.0 landed with 584 commits, delivering stack-wide Kimi-K3 optimizations, DeepSeek-V4 sparse MLA support, adaptive speculative decoding with 65% TTFT gains, and Model Runner V2 disaggregation.

Key Takeaways

  • Adaptive speculative decoding with DFlash2/DSpark cuts time-to-first-token by 55-65% across deployments;
  • Native full-stack acceleration for cutting-edge architectures including Kimi-K3 and DeepSeek-V4 sparse MLA;
  • Broad hardware enablement across NVIDIA SM12x, AMD ROCm fused kernels, and Intel XPU backends.
Read full story
Linked Models & Agents:

vLLM 0.28.0 Released: Full-Stack Kimi-K3, DeepSeek-V4 Sparse MLA, and Tiered Disk KV Cache

vLLM 0.28.0 landed with 584 commits, bringing stack-wide Kimi-K3 support, end-to-end DeepSeek-V4 sparse MLA with DFlash2/DSpark speculative decoding, Model Runner V2 disaggregation, and tiered disk KV cache.

Key Takeaways

  • Adaptive speculative token budgets slash end-to-end TTFT by 55–65% with 1.5–3x faster sequence-parallel kernels;
  • End-to-end DeepSeek-V4 sparse MLA and Kimi-K3 shared-expert sharding save ~17 GiB VRAM per GPU;
  • Tiered KV cache introduces a disk tier, doubles max batched tokens to 16,384, and supports diverse hardware backends.
Read full story