AI Coding Live News

Parameter discloses a ChatGPT share-link flaw that let one opened link read private chats; OpenAI fixed it Oct 26 and rated it P1

Security firm Parameter published an exploit chain in which an attacker publishes a malicious conversation through ChatGPT's normal sharing feature; when a signed-in victim opens the /share/ link, the payload runs as chatgpt.com in their session, lists conversations, reads a private chat that was never shared, and sends data out. Parameter reported it through OpenAI's bug bounty on October 18; OpenAI raised it from P2 to P1, fixed it on October 26 and paid a $5,000 bounty. Parameter reports no real-world use, and users do not need to do anything.

Parameter discloses a ChatGPT share-link flaw that let one opened link read private chats; OpenAI fixed it Oct 26 and rated it P1

Key Takeaways

  • Timeline: reported Oct 18; OpenAI reproduced it Oct 21 and raised it from P2 to P1; both web frontends fixed by Oct 26; published Oct 28 (Parameter writeup)
  • Very low bar: no app install, project join or pasted code; in the auto-preview variant, opening the link was the only action, firing after about 4.5 seconds (per Parameter)
  • Three root causes: MathLive did not check the message sender, the message could carry raw HTML as keyboard-layout data, and that HTML could create an unsandboxed iframe with the chatgpt.com identity; YouTube JSONP was only the final CSP bypass
  • Bounty was $5,000; Simon Willison called it "a bit cheap" for a flaw this serious (blog)
  • MathLive 0.111.2 (Oct 31) now defaults to same-origin validation and blocks cross-window custom HTML layouts (changelog)
Read full story

DeepSeek Harness team open-sources dsh-superagent, a proactive coding agent prototype for a single GitHub repo, alongside its Super-agent architecture article

On Oct 31, deepseek-ai open-sourced dsh-superagent-prototype on GitHub under the MIT license: a proactive coding agent that runs as a DeepSeek Harness bundle, lives on one GitHub repository and can optionally listen to Feishu. When an allowed person asks for work, it opens a work item, works in its own session and directory, and answers in the original conversation, for example with a pull request. The README states it is a research prototype, not an official DeepSeek product. The companion article, Exploring Super-agent Design, proposes a two-layer Router-Worker architecture; the team test, as reproduced by media, reports a p95 completion time of 15.7 minutes versus 29.5 minutes for a single-session setup.

Key Takeaways

  • Open source: deepseek-ai/dsh-superagent-prototype went public on Oct 31 under MIT, written in TypeScript, with about 1,800 stars at the time of writing
  • Scope: each deployment serves 1 GitHub repository, with optional Feishu; it acts only when an allowed person addresses it or a team-written rule allows it
  • Delivery: by default it only allows auto-merge for an approved pull request opened for a ticket with fewer than 200 changed lines, and never enables auto-merge as the agent account
  • Team test (as reproduced by media, vendor-reported): in a simulation with about 300 messages and 20 requests, p50 / p95 completion was 12.4 / 15.7 minutes versus 20.4 / 29.5 for a single session with a subagent tool
  • Risk: worker sessions run commands without approval as the operator's OS user, and the README asks users to review and adapt the code first
Read full story

Microsoft Research and UC Berkeley open-source TokenEconomizer, a plugin that cuts Claude Code and Codex costs by 18.4–30.9% on SWE-Bench without changing the agent

Microsoft Research, Microsoft Security and UC Berkeley open-sourced TokenEconomizer on GitHub (Apache 2.0, v0.1.0 released October 26), a plugin for Claude Code, Codex, GitHub Copilot CLI and Pi, with experimental opencode support. It learns from earlier sessions in the same repository: micro-skills remember repo facts, tool pruning drops tool definitions that go unused, and a loop guard nudges an agent that is stuck. The paper reports 18.4–30.9% lower mean cost across five agent and model combinations on 277 SWE-Bench tasks (paper figures).

Microsoft Research and UC Berkeley open-source TokenEconomizer, a plugin that cuts Claude Code and Codex costs by 18.4–30.9% on SWE-Bench without changing the agent

Key Takeaways

  • Cost: on 277 SWE-Bench tasks across 6 repositories and 5 agent and model combinations, mean cost fell 18.4–30.9%, and all 30 repository-by-combination cells got cheaper (paper figures, including the plugin's own model calls)
  • Success rate: Pass@1 rose in 4 of 5 combinations, e.g. Copilot CLI with Sonnet 5 cost 18.4% less with Pass@1 +2.6, while Claude Code with Opus 4.8 cost 30.9% less with Pass@1 -1.0
  • Three mechanisms: micro-skills (repo facts stated only after three sessions confirm them), tool pruning (by default a tool unused over 10 prompts across 2 sessions is left out), and a failure-loop guard (one redirect when a judge is at least 0.7 confident, never stopping a turn itself)
  • Generalization: 16–21% lower cost on Web-Bench and 6–20% lower on two security-auditing benchmarks where every task is a new repository
  • Deployment: Apache 2.0, Python 3.10+, no API key of its own, and learned experience stays local in ~/.tokeneconomizer
Read full story

OpenAI Agents API ships Auto Review, async compaction, experimental time awareness and mid-session tool updates

The OpenAI Developers account shared a post by Steve (@stevendcoffey), who works on the API at OpenAI, listing five Agents API updates this week: Codex-style Auto Review of commands before execution, compaction that runs in the background, an experimental time-awareness feature, updating a session's tools at any time, and automatic caching of system prompts across all sessions. As of writing, the official API changelog does not list these items yet.

Key Takeaways

  • Five updates: Auto Review, async compaction, time awareness (experimental), updating session tools at any time, and automatic cross-session system prompt caching
  • Auto Review mirrors the Codex mechanism and evaluates commands for potential bad behavior before they run
  • Time awareness lets the model act on time-boxed instructions such as "timebox CI fixes to 10 minutes"
  • The Agents API entered public beta on September 10, and this is another round of features within 7 weeks (after computer use on Sep 29, sandbox prewarming on Oct 9 and Ultrafast mode on Oct 16)
  • OpenAI has published no latency or cost-saving numbers, and the changelog has not listed these items yet
Read full story
ADSponsored

OpenAI says Daybreak Blue sessions on personal accounts may be used for training even with the training toggle off, drawing security researcher backlash on X

OpenAI's "Data controls in ChatGPT" Help Center page now has a "Trusted Access on personal accounts" section: during sessions in Trusted Access programs such as Daybreak Blue, OpenAI may use interaction content to improve its models even when "Improve the model for everyone" is off, to strengthen safeguards against cyber misuse, while other activity still follows the user's setting. Emails that several users shared on X say the change takes effect November 29, and researchers including Sean Heelan criticized it for pulling unreported vulnerabilities and research into training data.

Key Takeaways

  • Official wording: Trusted Access sessions such as Daybreak Blue on personal accounts may be used to improve models regardless of the "Improve the model for everyone" toggle
  • The exception covers only Trusted Access sessions; other chats on the account still follow the existing setting
  • Managed workspaces such as Business and Enterprise, and the API, are still not used for training by default
  • Emails users shared on X say it takes effect November 29, and some users say individuals lose Daybreak Blue API access on November 20 (the official pages do not state either date yet)
  • Sean Heelan's critical post drew 600+ likes and 100+ reposts, and several bug bounty hunters said they would reconsider using the program
Read full story
A
Anthropic@AICoder·
👀93
🔥80

Claude Code 2.1.314 adds a block on writes outside working directories, IdP group routing for the apps gateway, and idle compaction in VS Code and Desktop

Anthropic published Claude Code v2.1.314 on GitHub at 01:06 UTC on Oct 30. The official CHANGELOG lists 119 entries, more than half of them fixes. The new features lean enterprise: permissions.blockWritesOutsideWorkingDirectories makes Write, Edit and NotebookEdit refuse paths outside the working directories in every permission mode; Claude apps gateway upstreams can be limited to IdP groups, and Bedrock upstreams can log which guardrail fired; idle compaction now also runs in VS Code and the Code tab of Claude Desktop. It also fixes sessions failing repeatedly when an admin caps effort, and claude -p exiting 0 with no output when startup failed.

Key Takeaways

  • Size: the official v2.1.314 CHANGELOG has 119 entries, more than half of them fixes; released at 01:06 UTC on Oct 30
  • Safety: the new permissions.blockWritesOutsideWorkingDirectories setting stops Write, Edit and NotebookEdit from writing outside the working directories in every permission mode
  • Enterprise gateway: upstreams take an optional groups list so only developers in those IdP groups are routed there, failover included; Bedrock upstreams gain guardrail_trace
  • Experience: idle compaction now runs in VS Code and the Claude Desktop Code tab, summarizing idle conversations above 200K tokens
  • Fixes: when an admin caps effort, Claude Code lowers it and retries; a failed claude -p startup now prints the error and exits 1
Read full story
Linked Models & Agents:

Google is winding down its async coding agent Jules: read-only after Nov 11 and shut down on Dec 31, with its learnings moving into Antigravity

On Oct 29, Google announced through the official @julesagent account and the Jules changelog that Jules will wind down on December 31, 2026. Users can keep finishing sessions until November 11, after which Jules becomes read-only until the end of the year. Google says its learnings from Jules are going into Google Antigravity, its agent-first development platform, to combine autonomous remote background task execution with an agent-first environment. Google also published an export path for settings, environment variables, scheduled tasks, repositories, memories and every session.

Key Takeaways

  • Key dates: sessions can run until Nov 11, then Jules is read-only, and it shuts down on Dec 31
  • Next stop: Jules learnings go into Google Antigravity; Google does not promise automatic migration of sessions, memories or schedules
  • Export: run npm install -g @google/jules and jules login, then paste the official export prompt into a CLI coding agent; data lands in ~/jules-export
  • Code, branches and PRs already live in GitHub and are unaffected; env-variables.json holds secrets, so keep the export folder out of repos
Read full story

Claude Code lead Boris Cherny on faster usage drain: every shared session reviewed, no regression found, fixes for a few smaller issues rolling out

Since Oct 21 many developers on X have complained that Claude Code was draining usage limits much faster. On Oct 28 (UTC) Boris Cherny, who leads Claude Code at Anthropic, replied on X that the team reviewed every session ID users shared, found no single root cause and no regression in Claude Code, and is rolling out fixes for a few smaller issues that made some sessions burn tokens faster. Most fast-drain cases traced back to one or two heavy sessions using xhigh effort, /goal, Workflows, Agent Teams or long SDK jobs.

Key Takeaways

  • The complaint post that started it said usage was draining 5x faster and drew about 1,660 likes and 240+ replies (a user claim, not official data)
  • Boris Cherny: the team checked every shared session ID, found no single root cause or Claude Code regression, and is rolling out fixes for a few smaller issues
  • Heavy features were the main driver: xhigh effort, /goal, Workflows, Agent Teams and long SDK jobs
  • Subagents inherit the session effort level by default, which adds up fast; /usage shows where tokens went
  • The official docs say Agent Teams use about 7x more tokens than standard sessions when teammates run in plan mode
Read full story
Linked Models & Agents:

Entire, led by ex-GitHub CEO Thomas Dohmke, launches a Git forge for agent-human collaboration: Trails replace PRs, pushes up to 89x faster than GitHub per its benchmarks

On Oct 26, Entire co-founder and CEO Thomas Dohmke announced on X and the company blog that Entire is live as "the Git forge for agent-human collaboration." It has three parts: Trails, which replace diff-based review with eval scores computed on every push; Git-compatible distributed hosting that can replicate across regions or mirror from GitHub; and Continuous Memory, which stores agent sessions in the repo. Buildkite and Depot are the first CI integrations, and it is open to any developer today.

Entire, led by ex-GitHub CEO Thomas Dohmke, launches a Git forge for agent-human collaboration: Trails replace PRs, pushes up to 89x faster than GitHub per its benchmarks

Key Takeaways

  • Push speed (vendor-reported, open-source benchmark): Entire 418 pushes/s vs Cursor Origin 65, Pierre 15, GitLab 10, GitHub 4.7, i.e. up to 89x faster than GitHub and 6x faster than Cursor Origin
  • Trails: on every push, several review agents score the change independently in cloud sandboxes (defaults include Security, Slop and Human Review Required), showing the last 5 runs plus the current one; per-repo Gates can require human approval and passing CI before merge
  • Continuous Memory: two open-source, local-first plugins, entire-graph and entire-brain; entire-graph saved up to 71% of tokens in Entire's testing
  • Regions at launch: US, EU, Australia and India; repos can be mirrored from GitHub with GitHub kept as the source of truth
  • Pricing: not stated in the launch post
Read full story

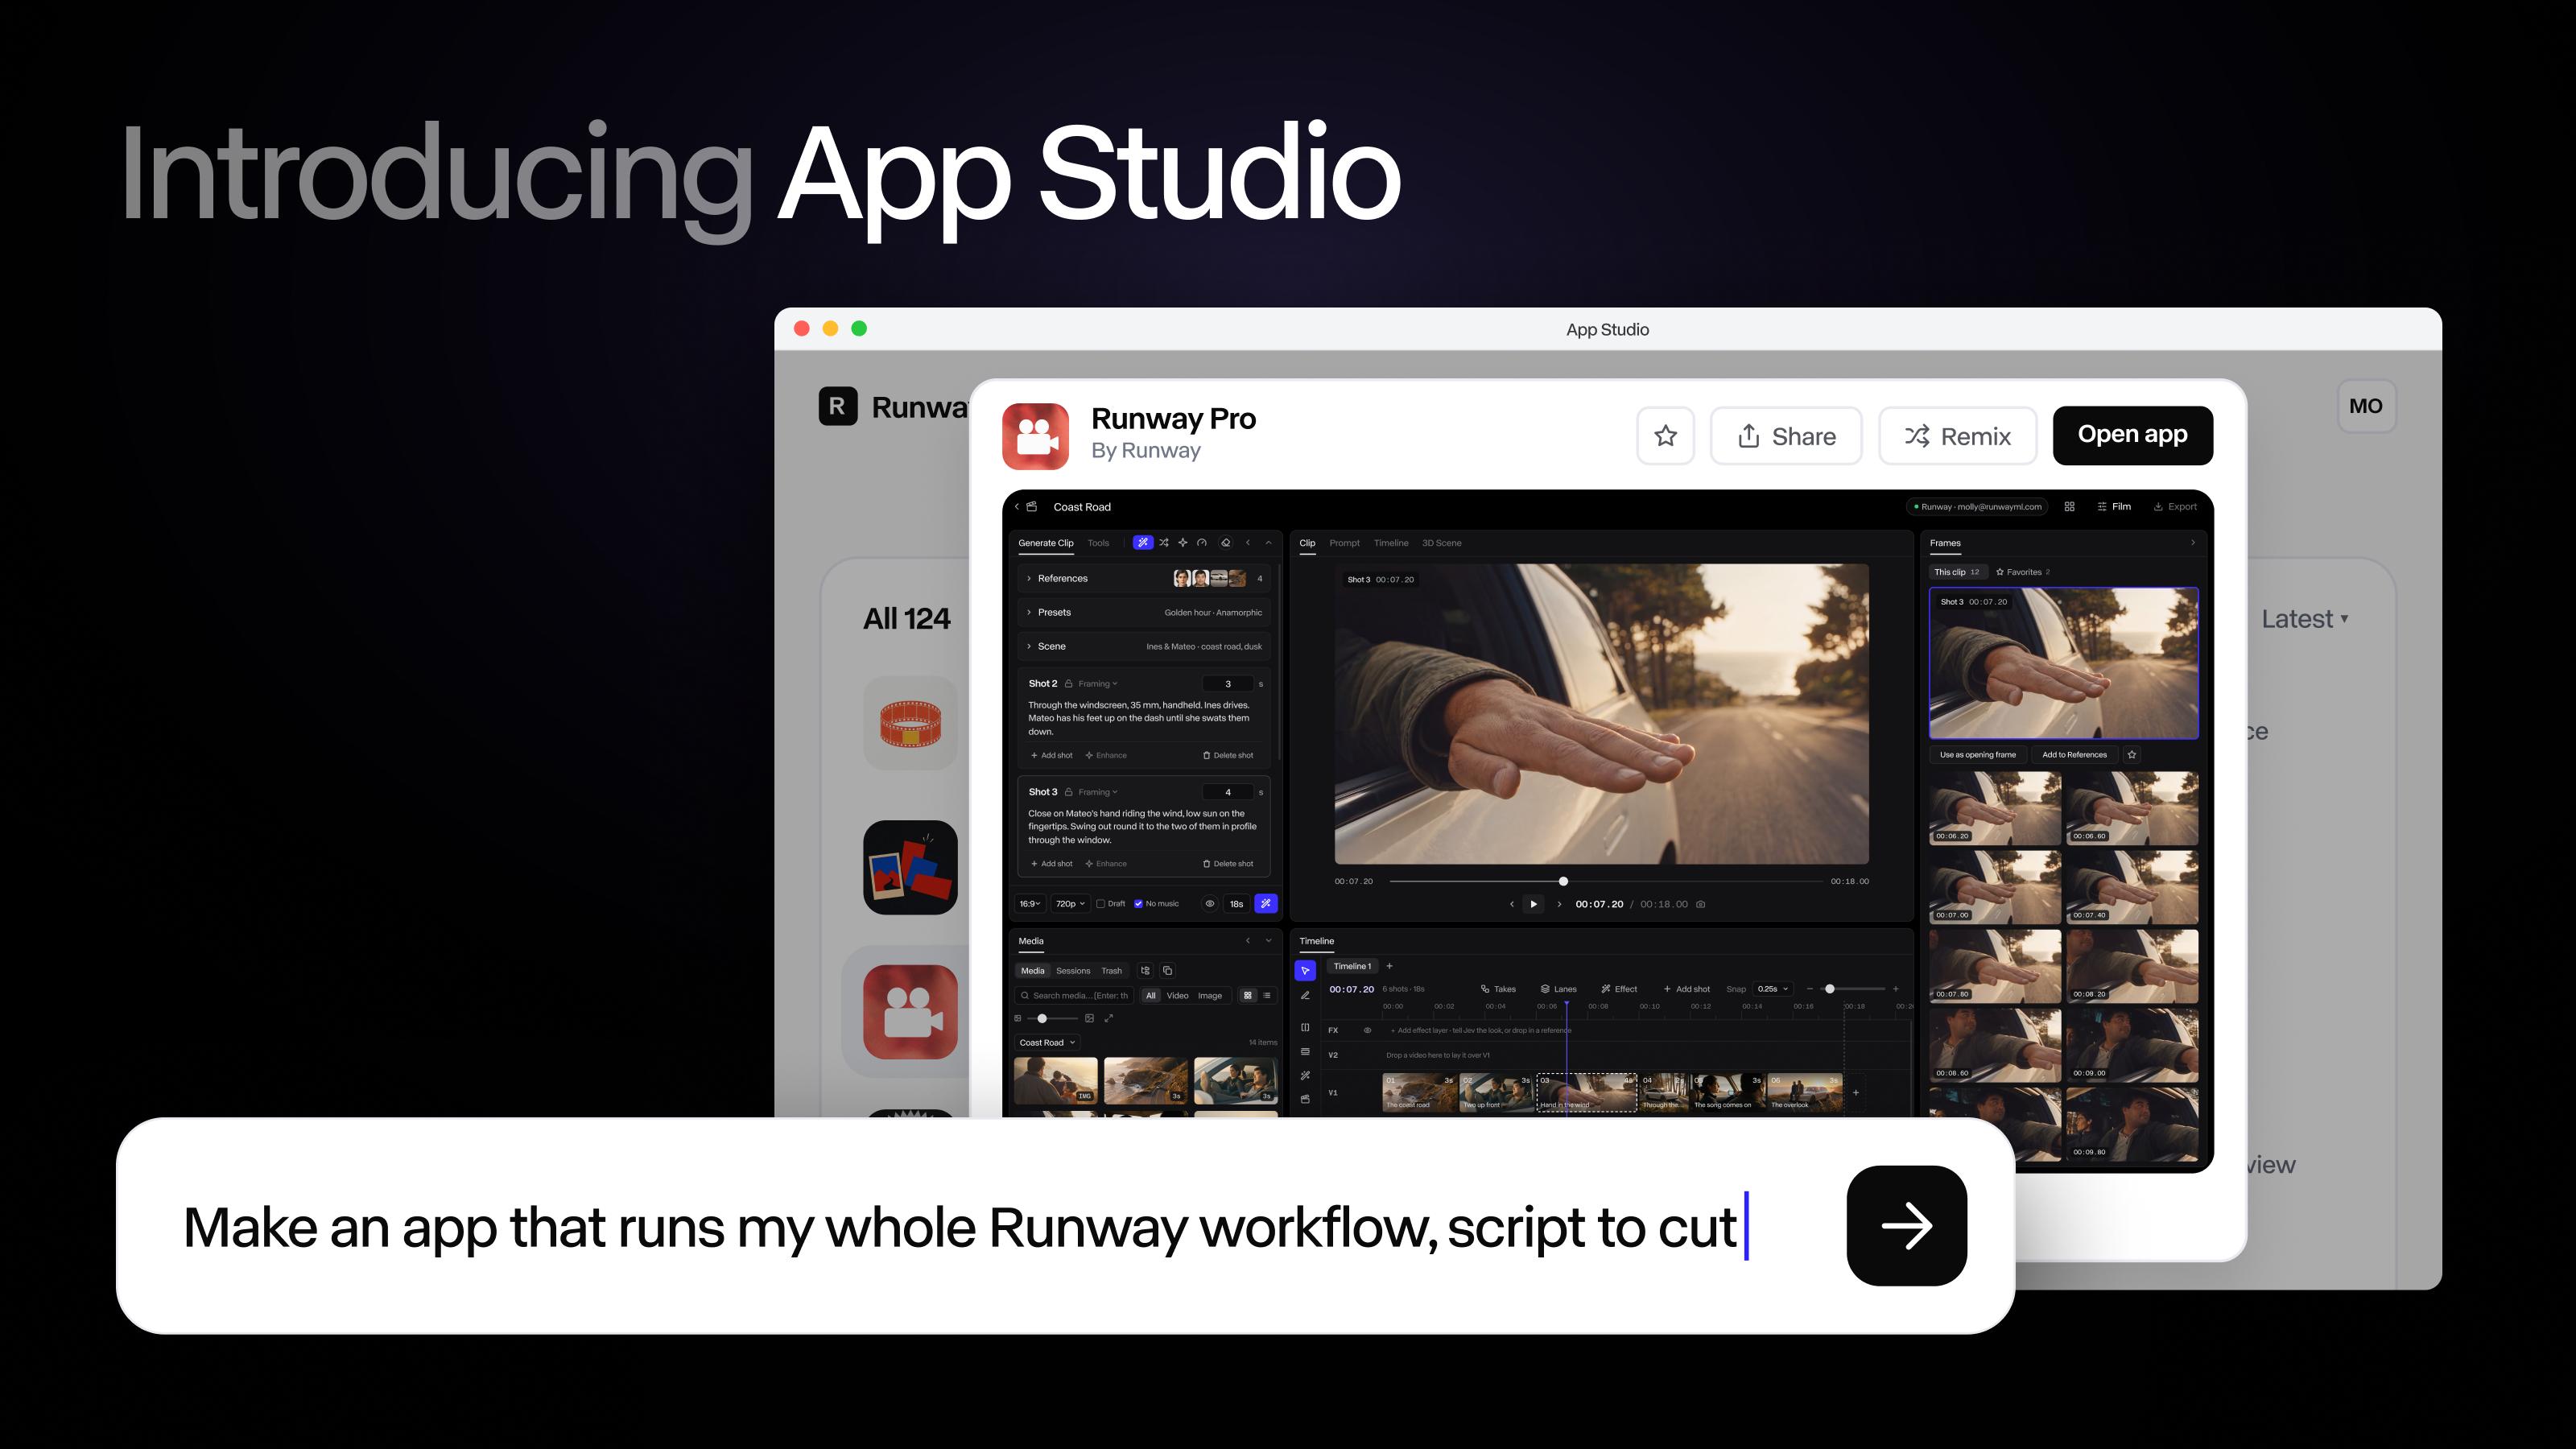
Runway launches App Studio: describe a creative tool in plain language and get a custom app that runs Runway's image, video and audio models on your Brand Kits

In an Oct 26 post on its blog, Runway launched App Studio: describe the tool you want in plain language and App Studio writes, tests and deploys an app with its own interface that generates images, video and audio with Runway's models, using your team's Brand Kits, Workflows and Assets. An existing Agent session or Workflow can be turned into an app in one click. Apps are private by default and can be shared with a team or published as a public link that visitors run on their own credits. Built-in apps at launch include Character Swap, AutoComp and 3D Camera Control. It is available now on every paid plan at no extra charge, drawing on existing Runway credits.

Runway launches App Studio: describe a creative tool in plain language and get a custom app that runs Runway's image, video and audio models on your Brand Kits

Key Takeaways

  • Pricing: available now on every paid plan with no add-on; building, running and hosting draw on existing Runway credits, and visitors to a public link pay for their own generations
  • Six built-in apps at launch: Character Swap, AutoComp (swap a product into footage while keeping packaging accurate), Product Portfolio, 3D Camera Control, Precise Edit and a customizable Runway Pro, each usable as is or remixable
  • One-click conversion: an existing Agent session or Workflow can lock in its prompt, model chain and settings and become an app that exposes only the inputs teammates need; the code stays visible, with preview and rollback
  • Enterprise controls: apps inherit the account's model controls, admins can turn App Studio off per workspace, block public links and see usage across all apps; Enterprise app links require a Runway sign-in
  • Early access (per Runway): architecture firm KPF built an app that turns design renderings into directed camera-move video, and design partners built dozens of custom apps
Read full story
Linked Models & Agents:
ADSponsored

VS Code 1.143 makes the Copilot SDK-based harness the default, adds multi-model comparison and on-device MAI Code 1.1 Flash

Microsoft shipped Visual Studio Code 1.143. The Copilot harness, built on the Copilot SDK, is now the default for new sessions and works across the editor and Agents window. A Compare Models preview runs several models on one task with an optional Judge model, an experimental mode runs MAI Code 1.1 Flash on a local NVIDIA GPU, and large chats open much faster.

VS Code 1.143 makes the Copilot SDK-based harness the default, adds multi-model comparison and on-device MAI Code 1.1 Flash

Key Takeaways

  • Default harness: new sessions use the Copilot harness built on the Copilot SDK, which can run in the background and move between the editor and the Agents window
  • Compare Models (Preview): one prompt runs 2 or more models in parallel, mixing Copilot, Claude and Codex harnesses, with an optional Judge model scoring time and token use and a Synthesize step
  • On-device models (Experimental): download MAI Code 1.1 Flash to run locally, labeled On-device with no AI credits used; needs an NVIDIA GPU with 96 GB+ memory
  • Performance (vendor figures): cold-opening a ~1,150-request chat dropped from 35.6 s to 9.0 s, and window freeze time from 28.3 s to 0.6 s
  • Also: the editor diagnostic highlight limit rises from 500 to 5,000 per file, and the Windows installer can install GitHub Copilot CLI
Read full story

ChatGPT Officially Rolls Out Locked Chats: Biometric Authentication and Complete Memory Isolation Across All Tiers

OpenAI officially rolled out 'Locked Chats' across all ChatGPT subscription tiers, including Free, Plus, Team, Enterprise, and Edu. Users can now safeguard sensitive individual conversation threads behind a device PIN, Face ID, or Touch ID biometric lock. Crucially, locked chats feature strict memory isolation: interactions inside locked sessions are physically barred from updating ChatGPT's persistent user memory bank. Confidential corporate discussions, sensitive health queries, or proprietary code audits remain strictly ephemeral to the local lockbox without contaminating future general chat contexts.

ChatGPT Officially Rolls Out Locked Chats: Biometric Authentication and Complete Memory Isolation Across All Tiers

Key Takeaways

  • OpenAI officially released Locked Chats, rolling out globally across Free, Plus, Team, Enterprise, and Edu subscriptions
  • Enables hardware-level protection via device PIN, Face ID, and Touch ID, shielding sensitive threads from physical shoulder surfing
  • Guarantees complete memory isolation: queries, uploaded documents, and confidential context are strictly prohibited from updating user memory
  • Eliminates context contamination risks when conducting proprietary code reviews, compliance audits, or medical inquiries
Read full story
Linked Models & Agents:

llm-d 1.0 ships: the Kubernetes-native open-source distributed inference stack led by Red Hat, IBM and Google hits production readiness, with vendors reporting 3,000 self-hosted coding agents at 5-10x lower cost than commercial APIs

At PyTorch Conference North America on Oct 20, the CNCF Sandbox project llm-d released version 1.0. It turns inference engines such as vLLM and SGLang into one coordinated serving pool, and 1.0 adds multi-tenant priority and fairness scheduling (flow control), router high availability with zero-downtime rolling upgrades (DisaggregatedSet), a v1 configuration API, and agent-aware session routing with Responses API state. Founded in 2025 by Red Hat, IBM, Google Cloud, CoreWeave and NVIDIA, the project has 500+ contributors, and JetBrains, DigitalOcean and Mistral already run it in production.

llm-d 1.0 ships: the Kubernetes-native open-source distributed inference stack led by Red Hat, IBM and Google hits production readiness, with vendors reporting 3,000 self-hosted coding agents at 5-10x lower cost than commercial APIs

Key Takeaways

  • Scale (Red Hat press release, vendor-reported): GLM 5.2, roughly 753B parameters, on NVIDIA GPUs peaked at 6.6M output tokens per minute and served up to 3,000 concurrent coding agents with zero preemptions, 5-10x cheaper per token than equivalent commercial API pricing at cloud rental rates
  • Cache reuse: IBM says the prefix-aware router captured 97% of available cache reuse on an agentic coding workload; an IBM Research quantum error correction project saw ~98% prefix hits, ~$0.11 per million tokens, and 11.5x lower cost than an all-proprietary setup
  • Google Cloud figures: on Ironwood TPU, prefix-aware routing plus host memory offload cut median time-to-first-token by more than 85% and raised throughput 2.4x on an agentic coding workload; the Gemini platform doubled its prefix cache hit rate from 35% to 70%
  • New in 1.0: flow-control multi-tenant QoS, router hot-standby HA, DisaggregatedSet for coordinated prefill/decode rollouts, a v1 config API, and previous_response_id support in the Responses API
  • Ecosystem: 500+ contributors from 25+ organizations; JetBrains' free Junie Lite, DigitalOcean Serverless Inference and Mistral's tiered commercial traffic run on it; the GitHub v1.0.0 notes admit not every tracked goal shipped
Read full story

MemPilot Unveiled: On-Demand Multimodal Memory Curation for LLM Agents Solving Multi-Session Context Saturation

Researchers introduced MemPilot (arXiv:2610.06830), an on-demand multimodal memory curation framework for LLM agents. Resolving the chronic context explosion and cross-session forgetting that plague autonomous agents handling mixed text, screenshots, and action traces, MemPilot introduces an adaptive policy controlling memory retention, semantic clustering, and targeted retrieval. Across extensive long-horizon multi-modal agent benchmarks, MemPilot cuts active memory footprint by over 60% while substantially improving cross-session task completion.

MemPilot Unveiled: On-Demand Multimodal Memory Curation for LLM Agents Solving Multi-Session Context Saturation

Key Takeaways

  • Researchers introduced MemPilot (arXiv:2610.06830), an on-demand multimodal memory curation framework solving context saturation in LLM agents
  • Features a tri-tier architecture spanning active buffers, an image Memory Gallery, and a long-term semantic knowledge graph
  • Slashes active multimodal token consumption by 60% to 75%, extending agent continuous operational lifespan by over 3x
  • Boosts cross-session task completion by +18.5% over text-only RAG, providing a scalable blueprint for persistent computer-use agents
Read full story
Linked Models & Agents:
A
Anthropicgithub.com·
👀63
🔥82

Claude Code 2.1.304 adds guided /auto-mode-setup and warns Pro/Max users before resuming an inactive conversation would eat into the 5-hour usage limit

Claude Code v2.1.304 (Oct 19 UTC) adds /auto-mode-setup, a guided setup that reads your project and recent sessions to teach auto mode about your environment, now also on Bedrock, Vertex, Foundry, Claude apps gateway and telemetry-disabled sessions. It adds a read-only /claude-api managed-agents-secure check against Anthropic's security guide, warns Pro/Max users when resuming an inactive conversation would use a noticeable share of the 5-hour limit, and fixes 40+ issues including claude --worktree deleting a worktree and branch without asking, which could lose commits.

Key Takeaways

  • New /auto-mode-setup reads your project and recent sessions to teach auto mode your environment, now on Bedrock, Vertex, Foundry, Claude apps gateway and telemetry-disabled sessions
  • New read-only /claude-api managed-agents-secure compares a Managed Agents agent's settings with Anthropic's published security guide
  • Pro/Max plans get a warning when resuming an inactive conversation would use a noticeable share of the 5-hour usage limit
  • Mods gain decider: "person" and e.isReadOnly in tool.check, so only a human permission dialog can approve certain calls
  • 40+ fixes, incl. claude --worktree removing the worktree and branch without asking (could lose commits) and CLAUDE_CODE_AUTO_COMPACT_WINDOW=200k silently becoming 100K
Read full story