AI Coding Live News

Google releases Gemini 4 Carbon two weeks after Argon: 59 and first place on the Artificial Analysis Intelligence Index v5, state-of-the-art cybersecurity and long-horizon coding, with early access for cyber defenders in the Fairwind program

Google DeepMind announced Gemini 4 Carbon on Oct 28, calling it its strongest model, just two weeks after Gemini 4 Argon. The official blog says it ranks first on v5.0 of the Artificial Analysis Intelligence Index at 59 and leads three cybersecurity evaluations: 88.2% on SEC-bench Pro for finding vulnerabilities, 54.8% on ExploitGym for exploitation and 71.0% on CWE-bench for patching; it also gains 89 points to rank fourth on WebDev Arena at 1769. Access starts this week for a subset of cyber defenders in the Fairwind program, with developers, businesses and consumers to follow. Introductory pricing matches Argon at $2 per million input tokens and $10 per million output tokens, rising to $4 and $20 afterwards.

Google releases Gemini 4 Carbon two weeks after Argon: 59 and first place on the Artificial Analysis Intelligence Index v5, state-of-the-art cybersecurity and long-horizon coding, with early access for cyber defenders in the Fairwind program

Key Takeaways

  • Positioning: Google calls it its strongest model, aimed at cybersecurity and long-horizon agentic work; internal teams saw it run for days to root-cause and patch subtle bugs across large codebases and low-level systems
  • Official scores (evaluated without guardrails): 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on Collinear's CWE-bench; 59 and first place on the Artificial Analysis Intelligence Index v5.0; +89 to fourth place on WebDev Arena at 1769
  • Safety and alignment: successful cheating on Terminal-Bench 4.0 fell to 0.0% with a 0.4% attempt rate, high-severity misalignment alerts in internal live coding dropped by almost 80%, unsupported claims are about half of Argon's, and the Gray Swan indirect prompt injection attack success rate fell from Argon's 0.7% to 0.0%
  • Internal examples: more than 2x Argon's success rate at generating secure code, and the Chrome team reports more than 10x better high-quality patches than another lab's large frontier model
  • Rollout: a subset of cyber defenders in the Fairwind program first, alongside the U.S. government's voluntary pre-release testing; no developer API yet; introductory pricing of $2 / $10 per million tokens with cached input 95% off, then $4 / $20
Read full story

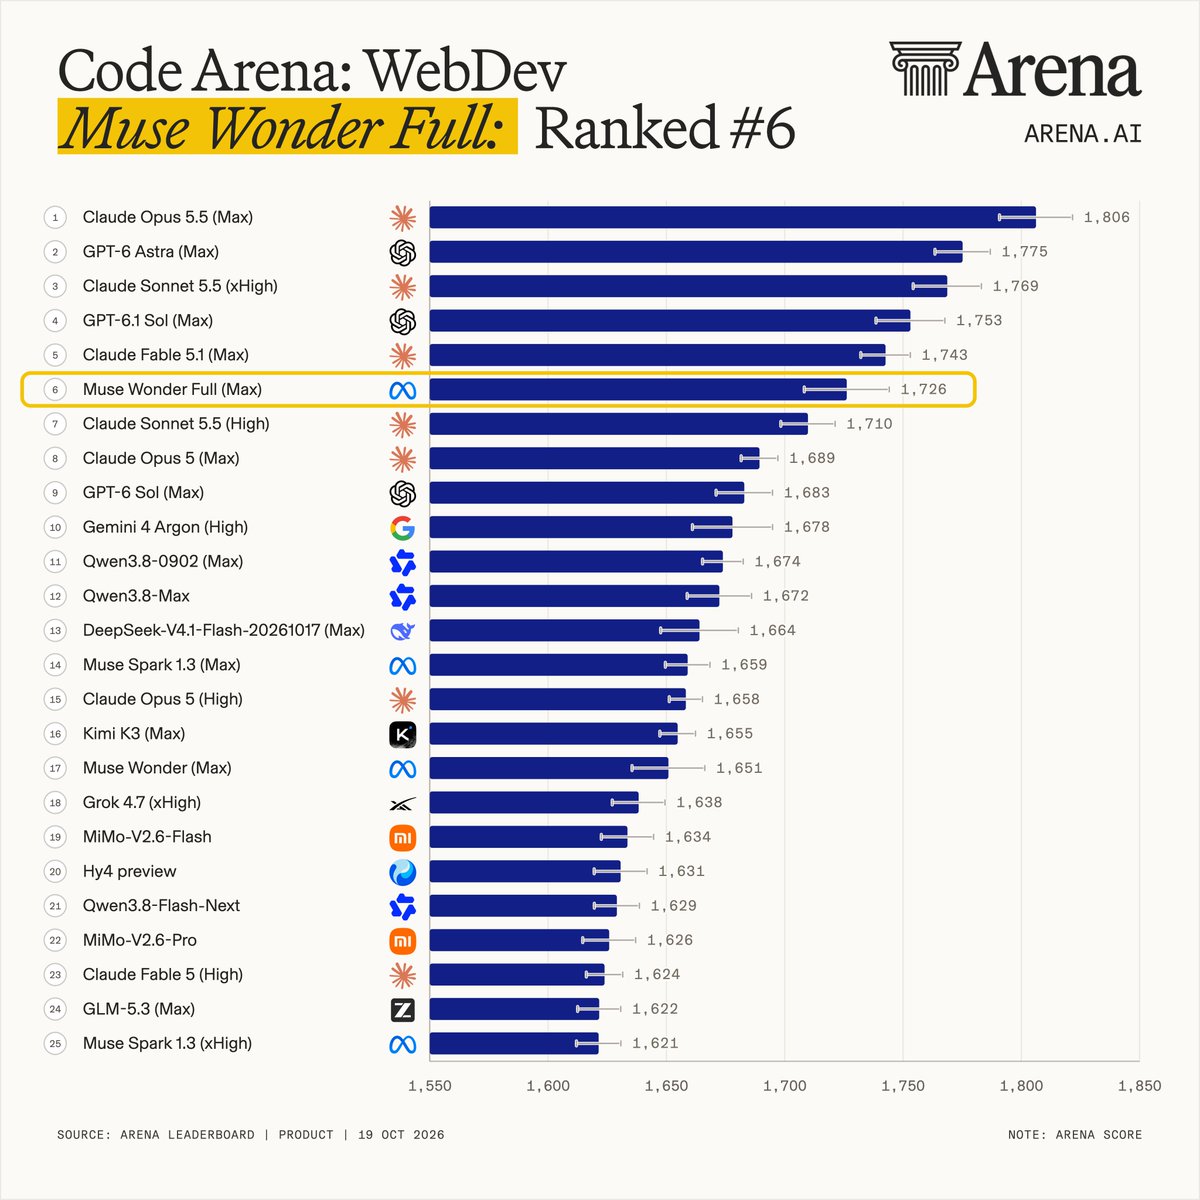
Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

Meta officially disclosed its gigawatt-scale AI supercluster Prometheus in New Albany, Ohio, housing hundreds of thousands of frontier GPUs with 85%+ pretraining goodput and 90%+ in reinforcement learning. Powered by this infrastructure, Meta's latest coding flagship Muse Wonder Full surged to #6 globally on LMSYS Code Arena: WebDev with 1726 Elo points (surpassing Claude Sonnet 5.5 and Gemini 4 Argon), lifting Meta to the #3 AI research lab worldwide.

Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

Key Takeaways

  • Meta unveiled its gigawatt-scale Prometheus supercluster in Ohio with hundreds of thousands of GPUs, delivering 85%+ pretraining goodput
  • Exceeded 90%+ goodput on RL workloads, recording ~47,000 GPU-hours MTBF during Muse Wonder's training cycle
  • Muse Wonder Full scored 1726 Elo on LMSYS Code Arena: WebDev (#6 globally), outperforming Claude Sonnet 5.5 (+16) and Gemini 4 Argon (+48)
  • Elevated Meta to the #3 AI lab worldwide; confirmed Muse Glimmer 30B open weights capable of 4-bit local execution on a single consumer GPU
Read full story
Linked Models & Agents:

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

MiniMax officially announced M3.1 Flash, its next-generation lightweight frontier model (previously dominating leaderboards as the secret model Space Bunny across 200T+ tokens). Featuring a native 1M context window, flat-rate API pricing of $0.15 / $0.60 per 1M input/output tokens ($0.015 cache reads), and 3x faster inference at 1/3 the cost of M3. It surged +106 points to 1588 on LMSYS Code Arena: WebDev (#12 among open models), with full weights set for open release on October 23.

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

Key Takeaways

  • MiniMax officially launched M3.1 Flash, unveiling that it was the mystery model Space Bunny evaluated across 200T+ tokens
  • Features native 1M context with flat-rate API pricing of $0.15/$0.60 per 1M tokens ($0.015 cache reads), offering 3x speed at 1/3 cost of M3
  • Debuts on LMSYS Code Arena: WebDev at 1588 Elo (+106 pts over M3), ranking #12 among open models with major leaps in Gaming (+179) and Reference Design (+155)
  • Artificial Analysis benchmark confirms Intelligence Index of 42 and HLE of 48% at half the token consumption of rivals; weights release on Oct 23
Read full story
Linked Models & Agents:

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Arena announced a major update to Code Arena: WebDev: DeepSeek-V4.1-Flash-20261017 (Max) clinched the #1 position among open models with 1670 points, surpassing Kimi K3 (Max) at a 10x lower cost. Ranking #12 overall, it outperforms Claude Opus 5 (High) and narrows the gap with closed-source frontier GPT-6 Sol (Max) to roughly 10 points, resetting the Pareto efficiency curve at $0.30 input / $1.20 output per million tokens.

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Key Takeaways

  • DeepSeek-V4.1-Flash-20261017 (Max) captured the #1 open model position in Arena Code Arena: WebDev with 1670 points, surpassing Kimi K3 (Max)
  • Ranks #12 overall on the leaderboard, defeating Claude Opus 5 (High) and trailing closed-source champion GPT-6 Sol (Max) by only ~10 points
  • Resets the Pareto efficiency frontier at $0.30 input / $1.20 output per million tokens, cutting operational costs by ~10x against rival models
  • Gains +52 points over its previous 20260910 checkpoint in just over a month
Read full story
Linked Models & Agents:
ADSponsored

LMArena: MiMo-V2.6-Pro enters Code Arena WebDev top 10 at AutoEval 1628

@arena reports Xiaomi MiMo-V2.6-Pro debuted on Code Arena: WebDev around #10 overall and about #3 among MIT-licensed open-weights models, scoring 1628 AutoEval points—tying Claude Fable 5 (High) and just ahead of Hy4-preview (1624). That is a +153 jump from MiMo-V2.5-Pro (1475). Live human votes are still coming in.

LMArena: MiMo-V2.6-Pro enters Code Arena WebDev top 10 at AutoEval 1628

Key Takeaways

  • Code Arena WebDev: MiMo-V2.6-Pro ~#10 overall, ~#3 among MIT open-weights.
  • AutoEval 1628, tying Claude Fable 5 (High), just ahead of Hy4-preview (1624).
  • +153 vs MiMo-V2.5-Pro (1475); human votes still open.
Read full story
Linked Models & Agents:
⚡ Xiaomi Mimo V2 6 Pro

Code Arena WebDev: GPT-6 Astra (Max) Leads at 1800; Claude Fable 5.1 at 1758

LMSYS Arena updated Code Arena: WebDev rankings: OpenAI GPT-6 Astra (Max) leads at 1800 points, with Anthropic Claude Fable 5.1 (Max) second at 1758. Anonymous win-rate charts show Astra dominating most matchups, including about 72.5% against GPT-5.6 Sol (xHigh).

Key Takeaways

  • WebDev board: GPT-6 Astra (Max) #1 at 1800; Claude Fable 5.1 (Max) #2 at 1758
  • Anonymous win rates show Astra ahead of most rivals
  • About 72.5% win rate versus GPT-5.6 Sol (xHigh)
Read full story

Agent Arena Image-to-WebDev: GPT-6 Astra (Max) leads at 1733; Claude Fable 5.1 second

Arena updated the Image-to-WebDev leaderboard: GPT-6 Astra (Max) leads at 1733 points, 129 above GPT-5.6 Sol (xHigh); Claude Fable 5.1 (Max) is second at 1710. The board compares newly evaluated model releases on image-to-webdev delivery.

Key Takeaways

  • GPT-6 Astra (Max) leads Image-to-WebDev at 1733 points.
  • Claude Fable 5.1 (Max) ranks second at 1710.
  • Four newly evaluated model releases landed on the board.
Read full story

LMArena: GPT-6 Astra (Max) tops Code Arena WebDev at 1797, +35 over Fable 5.1 Max

LMArena: OpenAI GPT-6 Astra (Max) takes #1 on Code Arena WebDev at 1797 pts, about +35 over Claude Fable 5.1 (Max) at 1762 and ahead of Claude Opus 5 (Max) and GPT-5.6 Sol (xHigh). It also reshapes the quality-price Pareto frontier at ~$40/Mtoken matching latest Claude pricing, on agentic web-dev workflows with multi-step reasoning and tool use.

Key Takeaways

  • Astra (Max) scores 1797 on WebDev, ~+35 over Fable 5.1 Max (1762).
  • Best-performing model on the ~$40/Mtoken Pareto frontier, matching latest Claude pricing.
  • Ranks agentic web-dev workflows with multi-step reasoning and tool use.
Read full story

LMArena: Claude Fable 5.1 Max tops Code Arena WebDev at 1765 (~77 pts ahead)

Arena.ai reports Claude Fable 5.1 (Max) takes #1 on Code Arena: WebDev at 1765 pts—up from Fable 5 (Max) at #8 / 1628 (+137 overall)—and leads Qwen3.8-Max-0902 by ~77 pts. It ranks #1 in five of six domains with large gains in Gaming, Simulations, and Reference-Based Design, and at ~$40/MToken reshapes the higher-price Pareto frontier.

Key Takeaways

  • Overall: WebDev 1765 #1 vs Fable 5 Max 1628/#8 (+137); ~77 pts over #2.
  • Domains: #1 in five of six; Gaming +234, Simulations +196, Reference-Based Design +160.
  • Cost: ~$40/MToken, lifting the higher-price Pareto performance bar.
Read full story
Linked Models & Agents:

LMArena: Fable 5.1 (Max) leads five of six WebDev domains; Gaming +234 pts

LMArena published Claude Fable 5.1 (Max) domain splits for Code Arena WebDev: overall 1765 vs Fable 5’s 1628 at #1, leading five of six domains (Gaming, Simulations, Reference-Based Design, Brand & Marketing, Consumer Product). Data & Analytics rose only +17. Scores for Content Creation and Fullstack are still forthcoming.

Key Takeaways

  • WebDev overall: Fable 5.1 (Max) #1 at 1765, ~+137 vs Fable 5.
  • Leads five of six domains; Gaming +234, Simulations +196, Reference-Based Design +160.
  • Data & Analytics only +17; Content Creation / Fullstack scores still pending.
Read full story
Linked Models & Agents:
ADSponsored

LMArena: Muse Spark 1.3 (xHigh) back in Code Arena WebDev top 10 at 1623 AutoEval

LMArena says Meta Muse Spark 1.3 (xHigh) lands ~#10 on Code Arena: WebDev with 1623 AutoEval pts, near Claude Fable 5 (#8, 1628) and GPT-5.6 Sol (#11, 1616). That is a large jump from Muse Spark 1.1 (#25, 1540) and 1.2 xHigh (#30, 1534). Scores are early AutoEval and may shift as live human votes arrive.

Key Takeaways

  • WebDev AutoEval ~1623, back in top 10, near Fable 5 and GPT-5.6 Sol.
  • ~80+ point jump vs Muse Spark 1.1 / 1.2 xHigh.
  • Early reward-model AutoEval; live human votes may move the rank.
Read full story
Linked Models & Agents:

LMArena: Meta Muse Spark 1.3 enters Agent/Code Arena; voting open, scores soon

Arena.ai (@arena) says Meta Muse Spark 1.3 is now in the Arena: Agent Arena measures long-horizon agentic tasks with web search, filesystem, and terminal tools via causal tracing vs the average model; it is also in Code Arena WebDev/Text/Vision/Document. Voting is open and scores are coming soon.

Key Takeaways

  • Muse Spark 1.3 is live in Agent Arena and Code Arena (including WebDev).
  • Agent Arena scores long-horizon tool-using workflows; leaderboard scores coming soon.
  • Voting is open so builders can stress-test prompts against frontier peers.
Read full story

LMArena: Fable 5.1 (Max) tops Code Arena WebDev at 1765, +77 over #2

LMArena (@arena) reports Anthropic’s Fable 5.1 (Max) leads Code Arena WebDev at 1765 pts, +77 over #2 Qwen3.8-Max-0902 and +78 over #3 Opus 5 (Max). That is a big jump from Fable 5 (Max) at #8 (1628). At a blended ~$40/MToken it also lifts the higher-priced Pareto frontier.

Key Takeaways

  • #1 on Code Arena WebDev at 1765, roughly +77/+78 vs Qwen3.8-Max-0902 and Opus 5 (Max).
  • Huge jump from Fable 5 (Max) at #8 (1628), raising the Max-tier coding bar.
  • Blended ~$40/MToken stays premium but reshapes the high-price Pareto frontier.
Read full story

LMArena: Gemini 3.8 Flash debuts in Agent/Text/Code Arena — #14 Agent, #7 Text

LMArena (@arena) says Gemini 3.8 Flash (High) is live across Agent Arena, Text Arena, and Code Arena WebDev. It ranks #14 in Agent Arena (+5.94% net, up from 3.7 Flash at #32), #7 in Text Arena (1494 pts) with Coding category jumping #22→#7, and #18 in Code Arena WebDev (1567 pts).

Key Takeaways

  • Live in Agent, Text, and Code WebDev Arenas for tool-use and coding evals.
  • Agent Arena #14 (+5.94%), a big jump from Gemini 3.7 Flash at #32.
  • Text Arena #7; Coding category #22→#7; WebDev #18 keeps DeepMind near the lab top.
Read full story

Qwen3.8-Max-0902 Hits #1 on Code Arena With 2.4T Params and 1M Context

Alibaba’s Qwen released Qwen3.8-Max-0902, a 2.4T-parameter, 1M-context model further post-trained for coding and cowork. It debuted at #1 on Code Arena: WebDev with 1,691 points, edging Claude Opus 5, while sitting on the Pareto frontier at a blended per million tokens.

Key Takeaways

  • 2.4T parameters and 1M-token context, post-trained for coding, cowork, research, and long-horizon workflows
  • #1 on Code Arena: WebDev at 1,691 pts, above Claude Opus 5 (1,688) and Kimi K3 (1,674)
  • Priced at input / output per 1M tokens, now live on QwenCloud
Read full story
Linked Models & Agents: