
vLLM and NVIDIA unveiled a unified CuTe DSL decode megakernel (~12,000 LoC authored by NVIDIA CentML's Benjamin Chislett) for Moonshot AI's frontier Kimi K3 model on NVIDIA GB300 NVL72. By fusing attention, MoE, and cross-GPU communication, the optimization cuts per-layer latency from 130 µs (23 kernels) to 69 µs (13 kernels), delivering 842 tokens/s at batch=1 with DSpark speculative decoding (1.73x faster than stock vLLM) and up to 1.8x higher P90 per-user interactivity (403.2–423 tok/s/user) on SemiAnalysis AgentX, with DeepSeek-V4.1-Flash (PR #61868) and GLM-5.3 support coming next.
Key Takeaways
- ✓NVIDIA and vLLM introduce a 12,000-line CuTe DSL decode megakernel for the 2.8T-parameter Kimi K3, reducing per-layer execution from 23 kernels (130 µs) to 13 kernels (69 µs)
- ✓On 16x NVIDIA GB300 NVL72 GPUs, batch-1 decode hits 842 tok/s with DSpark speculative decoding (1.73x faster) and 256.4 tok/s without speculation (1.88x faster)
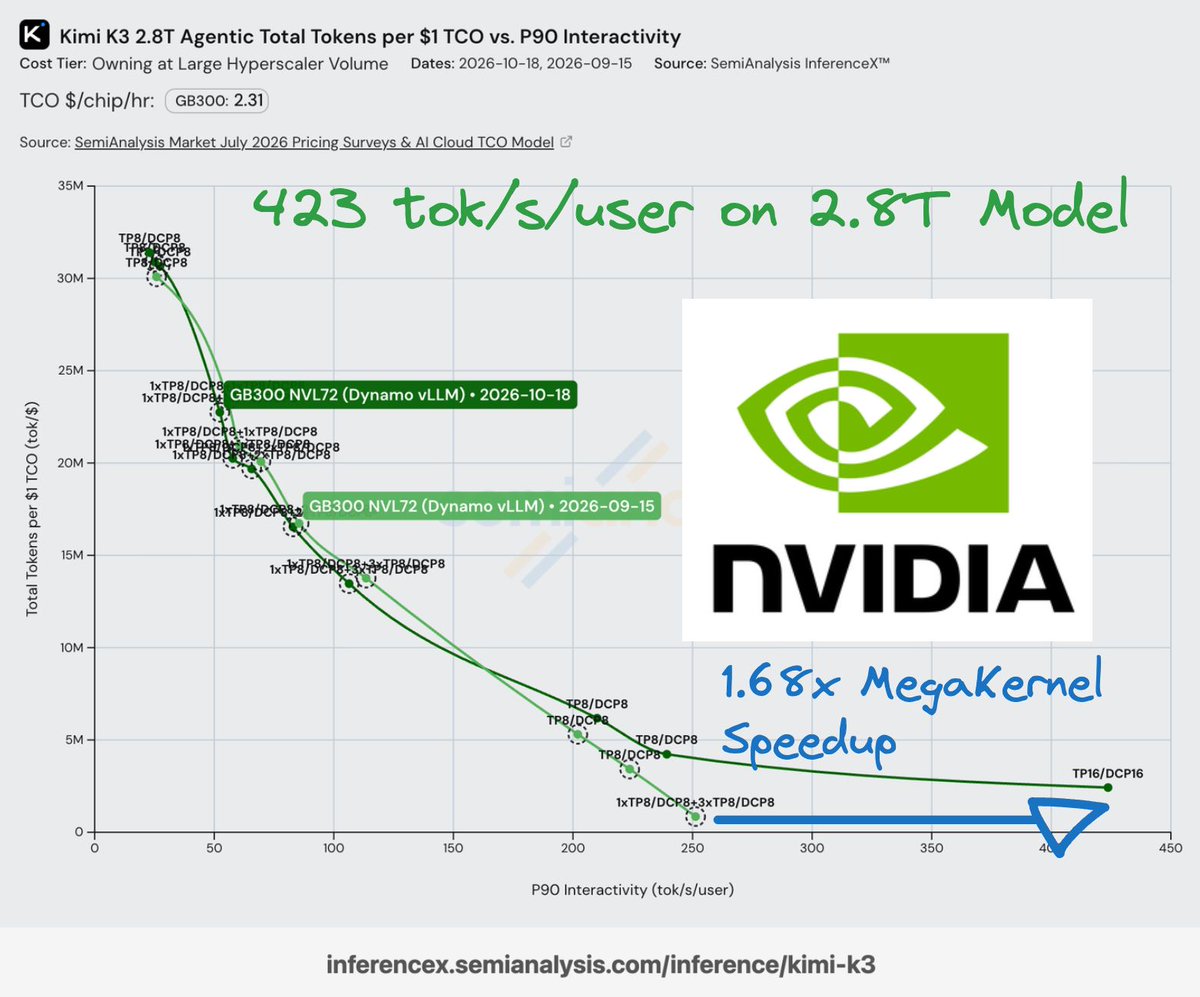
- ✓Delivers up to 1.8x higher P90 interactivity (403.2-423 tok/s/user) on SemiAnalysis AgentX, with DeepSeek-V4.1-Flash (vLLM PR #61868) and GLM-5.3 megakernels following next
Not enough VRAM? Compare cloud API and self-hosting costs
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
As frontier Mixture-of-Experts (MoE) foundation models scale into the multi-trillion-parameter regime—exemplified by Moonshot AI's Kimi K3 (reported by SemiAnalysis at 2.8 trillion parameters)—low-latency token decoding on rack-scale NVIDIA GB300 NVL72 superpods hits a wall dominated by kernel launch overhead and fine-grained inter-GPU synchronization. In interactive coding agent workloads, GPU Tensor Cores are frequently starved while waiting on 23 separate CUDA kernel launches per transformer layer across attention, MoE routing/GEMMs, and cross-GPU NVLink collectives.
Architectural Highlights & Core Mechanisms
Today, vLLM (@vllm_project) and NVIDIA unveiled a unified CuTe DSL Decode Megakernel for Kimi K3 authored by NVIDIA (CentML) engineer Benjamin Chislett, alongside an independent hardware benchmark analysis by SemiAnalysis (@SemiAnalysis_):
- 12,000-Line
CuTe DSLMegakernel Fusion: Written in NVIDIA'sCuTe DSL, the new decode path fuses attention, MoE expert computation, and multi-GPU communication into a unified execution flow. - Per-Layer Latency Slashed from 130 µs to 69 µs: Across each
Kimi K3transformer layer, kernel count drops from 23 kernels down to 13 kernels, cutting per-layer execution time by 46.9% (from 130 µs to 69 µs). - DSpark Speculative Decoding & Upcoming
DeepSeek-V4.1-Flash/GLM-5.3Support: The megakernel composes directly withvLLM'sDSparkspeculative decoding stack while passing strict long-context numerical evaluations. Equivalent megakernel pipelines are already underway forDeepSeek-V4.1-Flash(vLLM PR #61868) andGLM-5.3.
Authoritative Benchmarks & Empirical Comparisons
Evaluated on NVIDIA GB300 NVL72 across batch sizes, context lengths, and parallelism topologies:
- 842 tokens/s at Batch 1 with DSpark Speculative Decoding: On 16
GB300GPUs, single-request decode speed jumps from488 tokens/son stockvLLMto 842 tokens/s (1.73x faster). - 1.58x–1.88x Pure Decode Speedups Across Batch Sweeps: Without speculative decoding,
batch=1throughput reaches 193.3 tok/s on 8 GPUs (1.58x) and 256.4 tok/s on 16 GPUs (1.88x); atbatch=64, throughput hits 2,375.9 tok/s on 8 GPUs (1.31x) and 3,606.1 tok/s on 16 GPUs (1.62x). - Up to 1.8x Higher P90 Interactivity on SemiAnalysis AgentX: On the SemiAnalysis AgentX workload,
vLLMreportsP90interactivity rising from223.7to 403.2 tokens/s per user (1.8x), while@SemiAnalysis_highlights a 423 tok/s per user milestone (1.68x faster on identical hardware).
Developer Practical Guide & Quickstart
Infrastructure teams deploying Kimi K3 on NVIDIA GB300 NVL72 can review the full benchmark sweep and parallelism configurations in the official write-up (https://vllm.ai/blog/2026-10-16-kimi-k3-megakernel) and track vLLM PR #61868 for upcoming DeepSeek-V4.1-Flash and GLM-5.3 CuTe DSL megakernel integration.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.