
On 2026-11-06 Artificial Analysis launched Endpoint Accuracy Index v1.1: each serverless endpoint is scored as a percentage of a self-hosted official-weights reference across equally weighted BFCL-500, HLE-250, and AA-LCR-25. Vendor claim: nearly 1 in 4 of 100+ benchmarked endpoints score below the reference. AA-LCR-25 moved to v1.1 with repeats raised from 10 to 25 (average 95% CI ~±4.7 to ±2.6), and coverage expanded to six open-weights models including GLM-5.3 Flash and Muse Spark Open.
Key Takeaways
- ✓Official: @ArtificialAnlys 2026-11-06 02:44 UTC; changelog 05 Nov 2026; methodology Endpoint Accuracy Index v1.1
- ✓Vendor claim: nearly 1 in 4 of 100+ serverless endpoints score below the self-hosted reference; providers often quantize, custom-kernel, tune stacks, or cap outputs
- ✓Equal-weight suite: BFCL v4-500 (3 repeats), HLE-250 (10), AA-LCR-25 (25); 95% CIs vs reference with significance flags
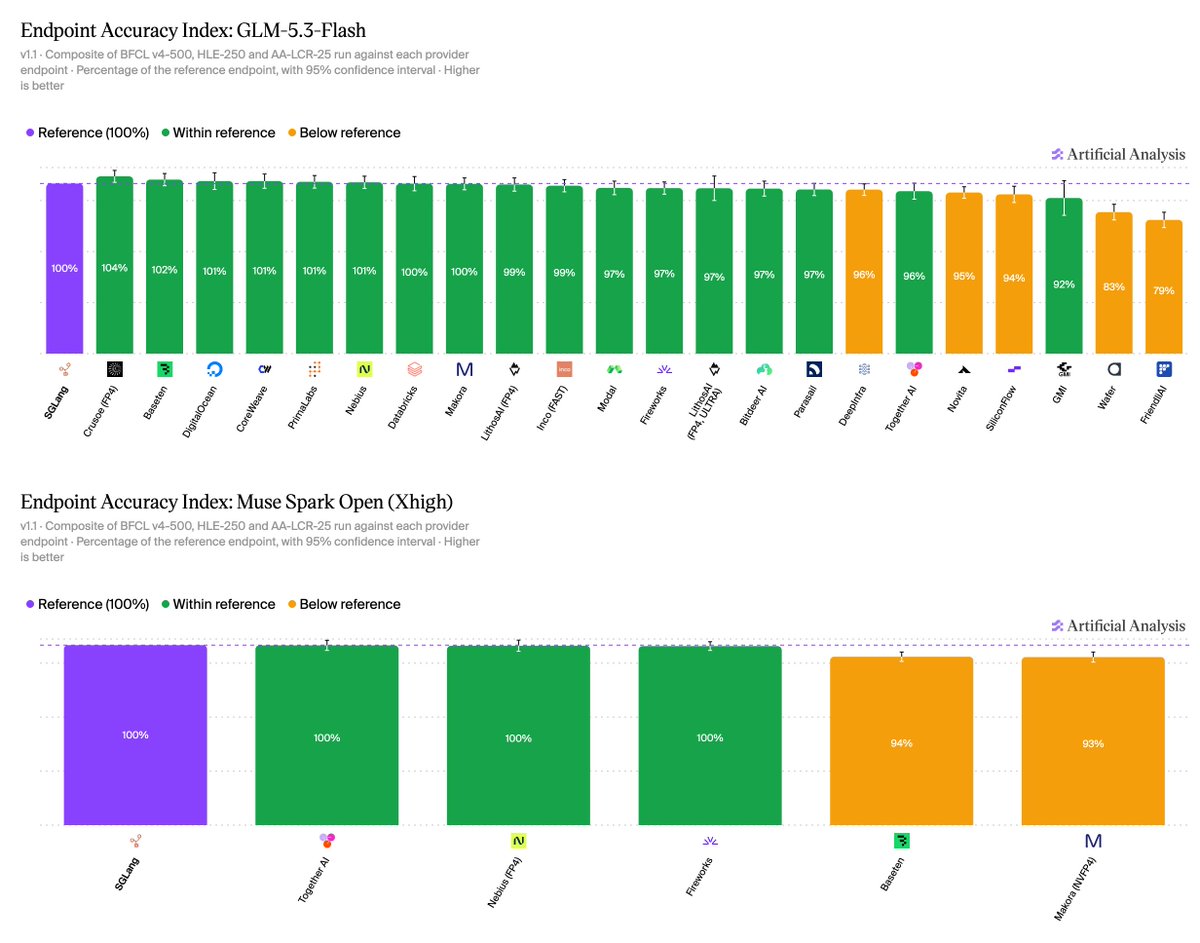
- ✓GLM-5.3 Flash: 16 of 22 endpoints statistically in line, one ~104.2; ~32K output caps scored ~22%/29% on HLE-250 vs 55% reference
- ✓Muse Spark Open: 3 of 5 endpoints ~99.5–99.9 (incl. FP4); two mainly lose on tool calling (BFCL-500 ~50%/51% vs 59%)
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
The same open weights can lose accuracy when hosted by different API providers through quantization, sampling defaults, context truncation, output caps, or tool-call parsing differences. Teams that shop only on price and speed can unknowingly buy a same-named model with lower effective accuracy. Artificial Analysis Endpoint Accuracy Index turns that gap into a comparable score.
Architecture Highlights & Internals
Each serverless endpoint is rescored against a fixed suite and reported as a percentage of a self-hosted official-weights reference (100%), with equal weights and 95% confidence intervals from repeats. v1.1 upgrades AA-LCR-25 to AA-LCR v1.1 (answer-key fixes; grading via GPT-5.6 Luna medium) and raises repeats from 10 to 25; Artificial Analysis says the average 95% CI tightened from about ±4.7 to ±2.6 points. Coverage expands to six open-weights models: DeepSeek V4.1 Flash 1017 (max), GLM-5.3 (max), Kimi K3 (max), gpt-oss-120b (high), plus new GLM-5.3 Flash (max) and Meta Muse Spark Open (xhigh). Results are dated point-in-time snapshots, not live monitoring.
Authoritative Benchmarks & Measured Scores
Figures below are Artificial Analysis official/vendor-reported. Overall: nearly 1 in 4 of 100+ endpoints score below the reference. GLM-5.3 Flash: 16 of 22 endpoints statistically in line with the reference, one about 104.2; two endpoints capped near 32K output tokens cut off roughly half of HLE-250 answers, scoring about 22% and 29% versus 55% for the reference; other endpoints that produced about 30% fewer reasoning tokens without truncation scored about 48% versus 55% on HLE-250. Muse Spark Open: three of five endpoints about 99.5–99.9 (including FP4); two mainly lose on BFCL-500 (about 50%/51% versus 59%) by returning text-typed tool args (e.g., booking IDs) as numbers. Always re-check methodology and per-model provider pages for the latest snapshot dates.
Developer Hands-on Guide
When picking a provider, use Endpoint Accuracy Index alongside price/speed: prefer endpoints whose confidence intervals overlap the reference; when debugging low scores, inspect output caps, default reasoning effort, tool-call JSON/typing, and context truncation. Self-hosted or first-party endpoints remain useful baselines. See artificialanalysis.ai methodology and provider pages; this index does not replace your own online evals and regression suites.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.