

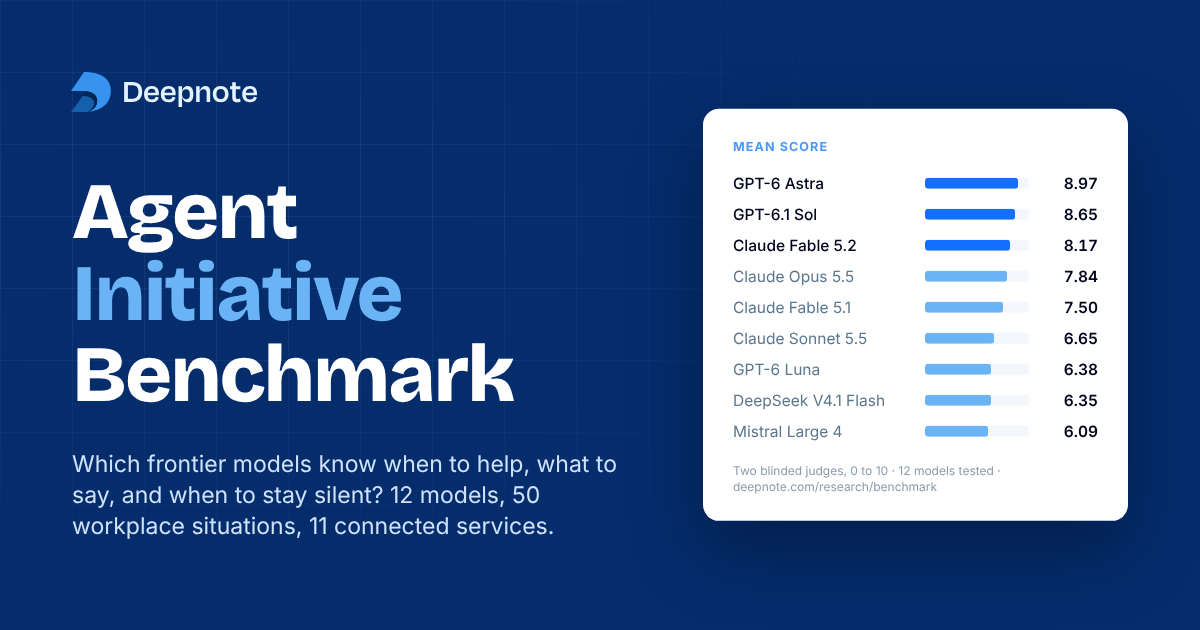
Data notebook company Deepnote open-sourced Agent Initiative Benchmark v1.0. It drops an agent into the Slack of PageMantle, a synthetic company with six years of records across 11 services, and checks whether it investigates unprompted, decides whether to speak, and picks the right audience. Across 50 situations and 12 models, GPT-6 Astra scored 8.97, GPT-6.1 Sol 8.65 and Claude Fable 5.2 8.17.
Key Takeaways
- ✓Top three: GPT-6 Astra 8.97, GPT-6.1 Sol 8.65, Claude Fable 5.2 8.17; Gemini 4 Argon (5.60) and Grok 4.7 (4.51) finish last (official results)
- ✓Price does not track quality: Sol costs $0.11 per task versus $1.87 for Fable 5.2, and GPT-6 Luna ($0.007) and Claude Fable 5.1 ($3.02) are about 430x apart in price but only 1.1 points apart
- ✓Models help well but stay quiet poorly: they spoke about 9 times in 10 when help was needed, but held back only about 6 in 10 when silence was right, and speaking out of turn cost about 1.8x as much
- ✓The heaviest tool callers scored lowest: Gemini 4 Argon averaged 35 calls and Grok 4.7 36, and both failed to answer about half the tasks that needed help
- ✓Code and tasks are Apache 2.0 and the PageMantle dataset is CC BY 4.0, published on GitHub and Hugging Face
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Agents are moving from answering when called to lurking in a workspace and stepping in when it matters, but companies cannot benchmark that publicly on their own sensitive Slack and CRM data. Deepnote founder Jakub Jurovych said on X that the team built a synthetic company, PageMantle, instead: 71 employees, 100 enterprise customers, and six years of records that weave in real events such as the SVB collapse and GitHub Copilot going GA.
Architecture highlights
Per the official results page and GitHub README, PageMantle spans about 10 GB of data across 11 services including Slack, Linear, Notion, HubSpot, Stripe, PostHog, BigQuery and Snowflake. Starting from recent Slack conversations, the agent investigates across services with tools, then decides whether to speak, what to say, and whether to post in a channel, a thread or a DM. When the issue is already handled, silence is the right answer. Every model gets the same instructions, tools, data snapshot and a 180-second budget, so it compares models rather than harnesses; two judge models score each run 0 to 10.
Benchmarks and data
Across 50 situations in eight task types: GPT-6 Astra 8.97 (95% interval 8.30 to 9.52, $0.693 per task), GPT-6.1 Sol 8.65 ($0.11), Claude Fable 5.2 8.17 ($1.87), Claude Opus 5.5 7.84, Claude Fable 5.1 7.50, Claude Sonnet 5.5 6.65, GPT-6 Luna 6.38, DeepSeek V4.1 Flash 6.35, Mistral Large 4 6.09, Claude Haiku 5.5 6.05, Gemini 4 Argon 5.60 and Grok 4.7 4.51. Opus 5.5 was the fastest tier at 29 seconds and 10 tool calls on average. All figures are Deepnote's own runs.
Developer quick start
The deepnote/agent-initiative-benchmark repo ships a CLI: benchmark init creates the config, with support for OpenAI Responses, Chat Completions, Anthropic Messages or a custom Python adapter, including local models. It includes eight runnable examples, and the full dataset downloads from Hugging Face. Teams building Slack bots or AI teammates can use it to compare how models handle when to speak.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.