
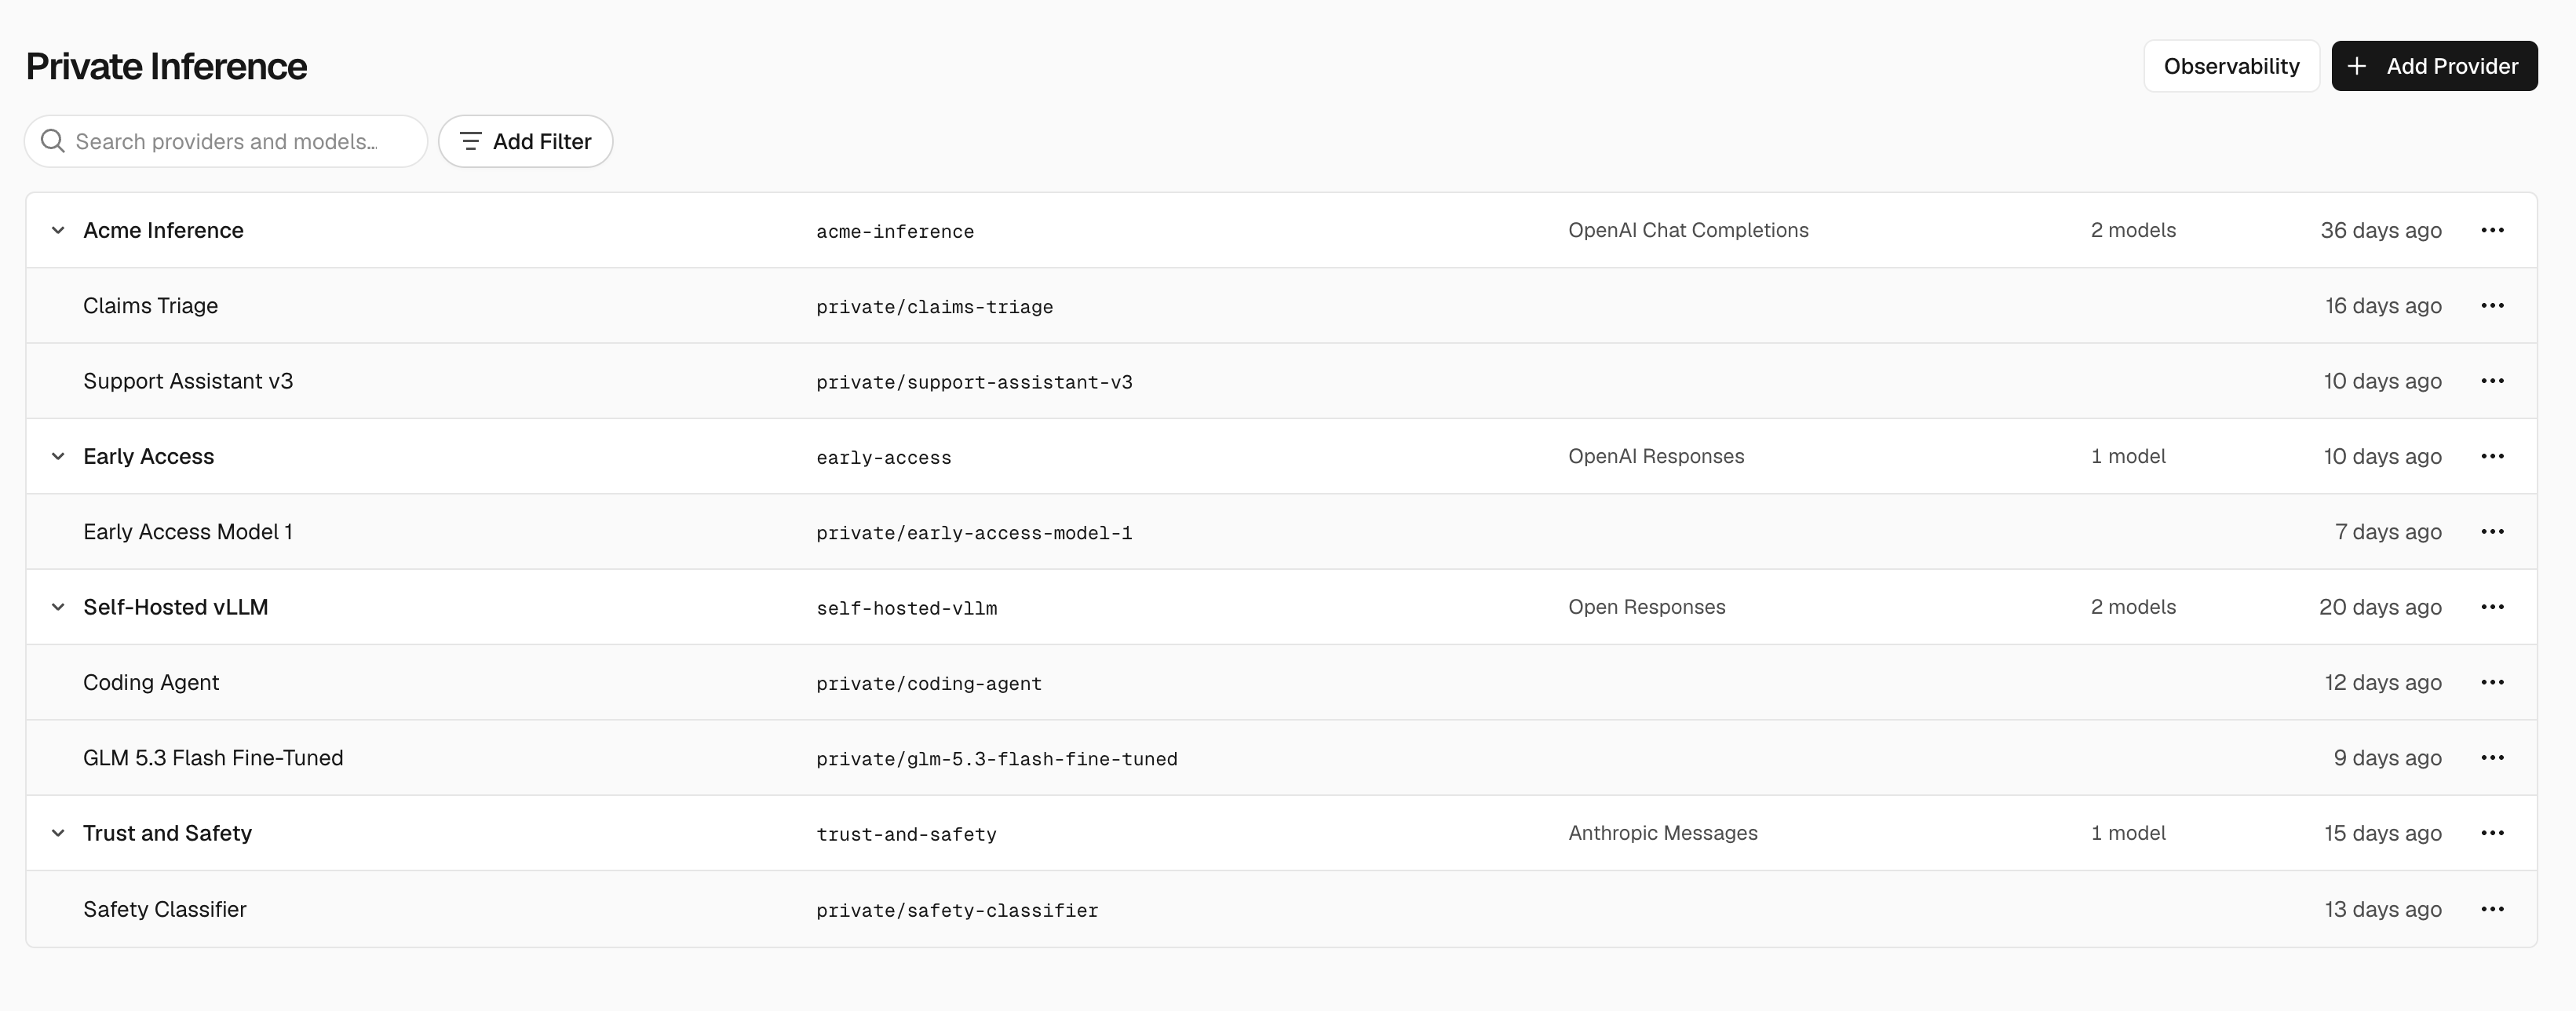
Vercel announced on X and its changelog that AI Gateway now supports Private Inference: enterprises can register their own model endpoints as private providers and call them with private/<slug> model IDs through Chat Completions, Responses or Messages, with the gateway translating each request to the endpoint format. Private models are visible only to the team, credentials are stored encrypted, Zero Data Retention can be enabled per provider, the models work in coding agents such as Claude Code, Codex and Cursor, and requests can fall back to a catalog model if the endpoint fails.
Key Takeaways
- ✓Register fine-tuned, self-hosted or prerelease model endpoints as private providers and call them with private/<slug> IDs, so switching models only changes the model ID
- ✓Supports the Chat Completions, Responses and Messages APIs, with the gateway translating each request to the endpoint format
- ✓Private models are visible only to your Vercel team and not listed in the public catalog; credentials are encrypted and Zero Data Retention can be enabled per provider
- ✓Works in coding agents connected to AI Gateway such as Claude Code, Codex and Cursor; logs, trace drains and reporting show private and catalog traffic together
- ✓Optional fallback to a catalog model if the private endpoint fails; Vercel CLI 65.16.0 or later adds private-inference providers and models create commands
Key Decision Metrics at a Glance
Not enough VRAM? Compare cloud API and self-hosting costs
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Background
Enterprises running fine-tuned or self-hosted models used to need separate keys, client code and logs for them, apart from catalog models from providers like OpenAI and Anthropic. Vercel announced on X and its changelog that AI Gateway now supports Private Inference.
How it works
On the Private Inference page you enter an endpoint base URL, API format and credentials to register a private provider, then add the models it serves. They are called with private/<slug> IDs through Chat Completions, Responses or Messages, and the gateway translates each request to the endpoint format. Private models are visible only to your team, credentials are stored encrypted, Zero Data Retention can be enabled per provider, and requests can optionally fall back to a catalog model if the endpoint fails.
Numbers that matter
This is a platform feature, and Vercel did not publish performance benchmarks or pricing figures; billing details are in the Private Inference documentation. Observability charts break down requests, tokens and time to first token by private model, next to catalog traffic in logs and trace drains.
What it means for developers
With Vercel CLI 65.16.0 or later, run the private-inference providers create and models create commands to register an endpoint, then set the model to a private/ ID in the AI SDK. After running npx vercel@latest ai-gateway setup, private models also appear in the /model picker in Claude Code and Codex.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.