
AI Coding Live News

Exin Therapeutics: Claude Sonnet 5 agent picks a gene therapy and drives a live mouse brain injection; Opus 5.5 declined

Exin Therapeutics co-founder and CEO Gabriel Ocana-Santero said on X on Oct 28 that an AI agent chose one of 19 gene therapy vectors, picked the brain region, derived coordinates from three papers and drove a stereotaxic rig to inject 250 nanolitres into an epilepsy-model mouse. WIRED reports Claude Opus 5.5 refused and Sonnet 5 did the run; a vet gated every irreversible step, and the work is not peer-reviewed.
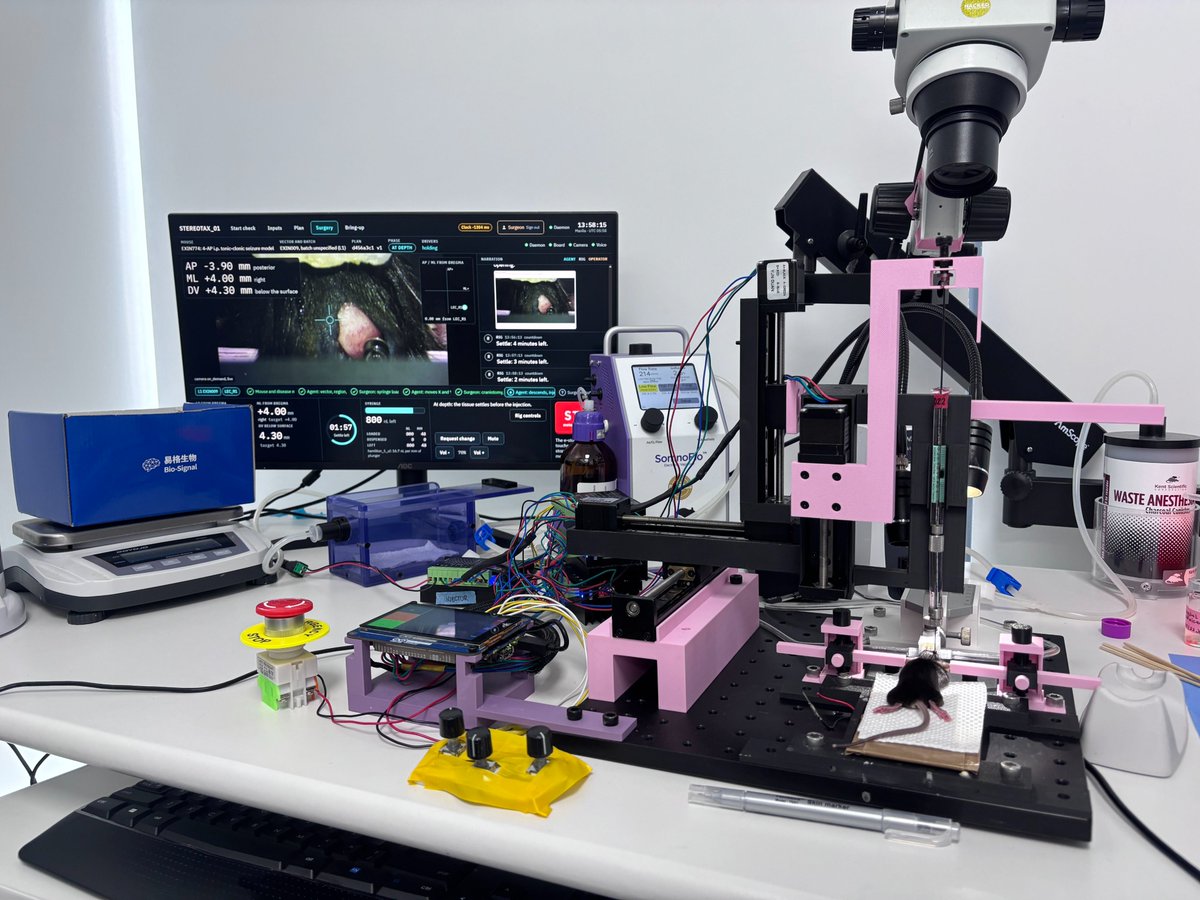
Exin Therapeutics: Claude Sonnet 5 agent picks a gene therapy and drives a live mouse brain injection; Opus 5.5 declined

Key Takeaways

  • The agent chose the drug from 19 vectors, picked the brain region and derived coordinates from 3 papers (per the CEO)
  • It injected 250 nL while watching for bleeding via the rig camera; The Decoder reports 32 observations during the procedure
  • Per WIRED, Claude Opus 5.5 refused to inject, so the team used Sonnet 5; the run took just over 1 hour vs about 45 minutes normally
  • After a coordinate fault the agent refused to bypass its safety limits and the team had to fix the code separately; a vet still did the craniotomy
  • The original post drew 9,426 likes and 1.6M+ views; seizure outcomes are pending and nothing is peer-reviewed
Read full story

xAI adds a guidelines field to the Grok API for per-request moderation of NSFW, violence and profanity

On Oct 28 xAI announced on the official @grok account that all API customers can now add a guidelines array to text requests and set the nsfw, violence and profanity categories to decline, so Grok tightens that content while it writes rather than through after-the-fact filtering. The field works on the Responses API, Chat Completions and the xAI Python SDK; multi-agent models and deferred completions are not supported, and invalid values are rejected with 400 or 422 before the model runs.

xAI adds a guidelines field to the Grok API for per-request moderation of NSFW, violence and profanity

Key Takeaways

  • Three categories: nsfw, violence and profanity; the only behavior today is decline, and unlisted categories keep the default (docs)
  • Works on the Responses API, Chat Completions and chat.create in the xAI Python SDK; with the OpenAI Python SDK pass it via extra_body
  • Applies only to the request that carries it, so send it on every turn; the xAI SDK chat object stores it for you
  • Not supported on multi-agent models such as grok-4.20-multi-agent or deferred completions; duplicate categories return 400 and unknown values return 422
  • The official post had about 592K views and 271 likes when this was written
Read full story
Linked Models & Agents:

VS Code Preview Introduces Canvases: Shared Workspaces for Developers and Coding Agents

The Microsoft VS Code team announced Canvases in VS Code Preview (v1.142), introducing dedicated shared visual workspaces connecting developers with autonomous coding agents. Addressing the severe UX limitations of cramped sidebar chat windows—where complex multi-file architectural modifications and agent diffs become hard to track—Canvases provides an expansive, interactive infinite-canvas whiteboard. Developers and agents (such as GitHub Copilot, Claude Code, and Cline) can collaboratively organize system flowcharts, live interactive code diffs, execution traces, and unit test rollouts side by side.

VS Code Preview Introduces Canvases: Shared Workspaces for Developers and Coding Agents

Key Takeaways

  • Microsoft VS Code Preview v1.142 introduced Canvases, pioneering a spatial human-agent collaborative interface
  • Transceives beyond claustrophobic sidebar chats to an expansive, pan-and-zoom whiteboard mapping concurrent multi-file agent diffs
  • Embeds code files, architecture diagrams, interactive git diffs, terminal outputs, and test runners as unified interactive cards
  • Natively bridges GitHub Copilot, Claude Code, and third-party coding agent harnesses, accelerating IDE spatial development
Read full story

SemiAnalysis Breaks Down 1.3B Tokens/$ AgentX Record: vLLM + Inferact Disaggregated Serving Beats Aggregated B300 by 4x, While Cline Highlights Multi-Harness RL

SemiAnalysis published the architectural breakdown behind the 1.3B tokens per dollar TCO record on AgentX: vLLM and Inferact utilized Prefill/Decode disaggregated serving at hyperscaler volume pricing to achieve 4x better cost-efficiency than an aggregated NVIDIA B300 configuration. Concurrently, open-source coding agent Cline reported that DeepSeek-V4.1-Flash-1017 beats GPT-5.6-Sol on Terminal-Bench at ~17x lower cost (+35% over prior V4.1-Flash) purely by scaling RL training across multiple coding agent harnesses.

SemiAnalysis Breaks Down 1.3B Tokens/$ AgentX Record: vLLM + Inferact Disaggregated Serving Beats Aggregated B300 by 4x, While Cline Highlights Multi-Harness RL

Key Takeaways

  • SemiAnalysis confirms vLLM and Inferact achieve 1.3B tokens per dollar TCO on AgentX via disaggregated serving—4x better than an aggregated NVIDIA B300 configuration
  • Cline reports that DeepSeek-V4.1-Flash-1017 improves prior V4.1-Flash Terminal-Bench performance by 35%, beating GPT-5.6-Sol at ~17x lower cost
  • The 35% agentic coding leap was achieved without base algorithmic changes by scaling reinforcement learning directly across multiple coding agent harnesses
Read full story
Linked Models & Agents:
ADSponsored

First Empirical Study on Agent Skill Evolution Reveals Concrete Rules in SKILL.md Boost Agent Correctness

In modern coding agent ecosystems (such as Claude Code, Cursor, Cline, and Antigravity), Agent Skills—specialized instruction files like SKILL.md and CLAUDE.md that dictate project architecture, commands, and rules—are continuously revised by developers alongside source code. Yet the concrete impact of these revisions on agent behavior and inference cost has remained largely unquantified. In a comprehensive empirical audit (arXiv:2610.04832), researchers analyze 2,608 first/last revision pairs across 3,159 Skills to measure the effects of revisions across 21 foundation models and four sandboxed coding agents. The study reveals that 55% of revisions alter specific rules or procedures. Adding a concrete rule raises compliance in single answers by +0.41 across open-weight models, increases required action adherence by +0.23 across sandboxed agents, and improves final task correctness by +0.10 in blind evaluations. Critically, these gains are overwhelmingly driven by rules that specify explicit CLI commands or exact file paths, whereas abstract stylistic guidance offers negligible lift. The paper also documents the performance and token trade-offs of dynamic on-demand skill loading.

Key Takeaways

  • First empirical study on Agent Skill evolution audits 3,159 Skills and 2,608 revisions across 21 models and 4 agents
  • Adding a concrete rule raises compliance by +0.41, sandbox action execution by +0.23, and final correctness by +0.10
  • Performance gains stem almost entirely from explicit commands and paths; dynamic on-demand loading retains 51% of efficacy
Read full story
Linked Models & Agents:

Cline launches Cloud Agents: assign tasks in the browser, cloud sandboxes code/test and open PRs, up to 10 in parallel

Cline moved its open coding agent into the browser: connect GitHub, pick a repo and model, and each task runs in an isolated cloud sandbox that commits to a cline/ branch and can open a PR—even with your laptop closed. Limits: 10 concurrent sessions and 50 new sessions/day. Providers: ClineFree, ClinePass ($9.99), and usage-billing. Cloud sessions do not yet load Rules, Skills, MCP, or Connectors.

Key Takeaways

  • Surface: no install; assign work from app.cline.bot Agents; each session gets its own sandbox and repo copy (docs)
  • Delivery: continuous commits on a dedicated cline/ branch, then optional PR; idle 15 minutes pauses the sandbox, resume keeps the workspace
  • Scale: up to 10 concurrent sessions and 50 new sessions/day; mobile browser for approvals/follow-ups
  • Models: ClineFree trials, ClinePass $9.99/mo (~2–5× open-model usage), usage-billing; switch mid-session
  • Security / gaps: GitHub token scoped to the single chosen repo; cloud does not load Rules/Skills/MCP/Connectors yet (local IDE/CLI/Desktop remain full-featured)
Read full story

Mid-Harness Scales Actions at Model-Harness Boundary: Action Verification Lifts TerminalBench Pass@1 by 18%

Terminal agents operate through stochastic model generations, but a single errant command can irreversibly degrade sandbox environments. Mid-Harness introduces test-time compute scaling at the boundary between model and harness. By sampling and verifying candidate actions before terminal dispatch without modifying the underlying generator or harness, Mid-Harness boosts Pass@1 on TerminalBench-Lite from 50.00% to 68.03% under a GPT-5.6 Sol verifier, outperforming whole-trajectory scaling at lower token expenditure.

Mid-Harness Scales Actions at Model-Harness Boundary: Action Verification Lifts TerminalBench Pass@1 by 18%

Key Takeaways

  • Allocates test-time compute at model-harness boundary, lifting TerminalBench-Lite Pass@1 from 50.00% to 68.03%
  • Pairwise action verification and distillation enable compact local models to filter errant commands effectively
  • Reduces estimated token overhead by over 35% compared to whole-trajectory sampling while increasing task completion
Read full story

Cline CLI 3.0.67 / SDK 0.0.89 / Desktop 0.0.40: pageable MCP oversized results; custom providers actually run tasks

Cline shipped cli-v3.0.67, sdk/sdk/v0.0.89, and desktop-v0.0.40 on 2026-09-30: oversized MCP/Composio tool results are cached with a bounded preview plus a cline://cache/... URI pageable via read_files (16 MiB/session, expire after five unread model iterations); custom providers from providers.json/models.json now resolve on the agent path instead of failing with Unknown or disabled provider; recommended catalog adds GPT-6.1 Sol and refreshes several gateway defaults.

Cline CLI 3.0.67 / SDK 0.0.89 / Desktop 0.0.40: pageable MCP oversized results; custom providers actually run tasks

Key Takeaways

  • Trio: CLI 3.0.67 (23:42:02Z), SDK 0.0.89 (23:34:22Z), Desktop 0.0.40 (23:56:13Z) on 2026-09-30
  • Oversized MCP/Composio: preview + cline://cache/... pageable via read_files; opt-in resultPolicy: "cache-oversized"; 16 MiB/session, expire after 5 unread iterations
  • Custom providers now register via resolveGatewayProviderRegistration(Sync) on the agent path
  • Catalog: GPT-6.1 Sol recommended; refreshed defaults for 302.AI/NanoGPT/Vivgrid/Vultr; Vultr id renames may need re-pin
  • Desktop remembers Cloud vs Local + Cloud model; MCP settings honor CLINE_* path env vars consistently
Read full story

Cline 4.1.22: GPT-6.1 Sol becomes default across gateways; Anthropic server-side refusal fallback; Bee & Pareto providers

Cline shipped v4.1.22 on 2026-09-30 (59 commits ahead of v4.1.21): refreshed catalog makes GPT-6.1 Sol the default for OpenAI, OpenRouter, GitHub Copilot, Requesty and more when unpinned; direct Anthropic uses server-side refusal fallback with OpenRouter/Cline failover; adds Bee (HEOSSI) and Pareto Inference (PARETO_API_KEY); fixes cancel races, double-counted reasoning tokens, and Bedrock inference-profile routing. SDK @cline/[email protected] ships the same day.

Cline 4.1.22: GPT-6.1 Sol becomes default across gateways; Anthropic server-side refusal fallback; Bee & Pareto providers

Key Takeaways

  • Release v4.1.22; 59 commits ahead of v4.1.21
  • Unpinned defaults: GPT-6.1 Sol on OpenAI/OpenRouter/Copilot/Requesty and more; Vercel AI Gateway→Ling 3.1 Flash; CrossModel/Ofox→Sonnet 5.5
  • Anthropic server-side refusal fallback + OpenRouter/Cline allow_fallovers; content-filter finish reason instead of empty response
  • New providers: Bee (HEOSSI), Pareto Inference (PARETO_API_KEY)
  • SDK @cline/[email protected]; docs https://docs.cline.bot/
Read full story

Cline SDK 0.0.87: Windows proxy-safe hub startup; reasoning tokens not double-counted; Bedrock GPT-6 via inference profiles

Cline shipped SDK v0.0.87 on 2026-09-29: Windows hub startup works when HTTP(S)_PROXY is set—ensureLoopbackProxyBypass() adds loopback to NO_PROXY so Bun fetch no longer routes health probes through Clash/v2ray/corp proxies; normalizeUsage() excludes reasoning from outputTokens to stop double-counting; Gateway models keep per-model apiProtocol; bare GPT-6/GPT-5.6 on Bedrock use inference profiles (@ai-sdk/amazon-bedrock ^5.0.96); catalog 209→211 providers, 6,386→6,447 models; recommended list adds Claude Sonnet/Opus 5.5.

Cline SDK 0.0.87: Windows proxy-safe hub startup; reasoning tokens not double-counted; Bedrock GPT-6 via inference profiles

Key Takeaways

  • Release sdk/v0.0.87 vs v0.0.86
  • Windows proxy: ensureLoopbackProxyBypass() stops hub probes from going through HTTP(S)_PROXY
  • outputTokens excludes reasoning subset (cost still on full output); no double-count in session totals
  • Bedrock GPT-6/GPT-5.6 via inference profiles; @ai-sdk/amazon-bedrock ^5.0.96
  • Catalog 209→211 providers, 6,386→6,447 models; Sonnet/Opus 5.5 on recommended list
Read full story
ADSponsored

Cline Desktop v0.0.37 Released: Adds Built-in Updater & Highlights Dialog, Patches Bedrock Reasoning Config

Cline Desktop (@cline_dev) has shipped release v0.0.37. The update introduces a comprehensive lifecycle management experience, embedding a dedicated 'About' view within Settings that enables in-app update checks, one-click restarts, and inline changelog inspection. Users are greeted with an updated 'What's New' dialog highlighting recent architectural milestones including SSH remotes, Git worktrees, pull request telemetry, and parallel sub-agents. Crucially, the release patches an AWS Bedrock inference bug that triggered 'Unknown parameter: reasoningConfig' on OpenAI models, while adding a macOS diagnostic export shortcut.

Cline Desktop v0.0.37 Released: Adds Built-in Updater & Highlights Dialog, Patches Bedrock Reasoning Config

Key Takeaways

  • Introduces an in-app About settings pane featuring direct update checking, automated restart patching, and release notes.
  • Launches a unified What's New dialog summarizing SSH remotes, Git worktrees, PR composer status, and parallel sub-agents.
  • Fixes an AWS Bedrock regression causing OpenAI models to crash with 'Unknown parameter: reasoningConfig'.
  • Adds a direct macOS Help menu shortcut for one-click diagnostic log exporting.
  • Signed binaries for macOS, Windows, and Linux available directly on GitHub Releases.
Read full story

Cline Desktop v0.0.37: About & What's new surfaces; Bedrock OpenAI inference profiles fix reasoningConfig errors

Cline Desktop v0.0.37 (2026-09-26) adds Settings → About (version/channel, check/restart updates, recent release notes, report issue), a one-time What's new dialog after updates, macOS Help→Export Diagnostics, and fixes Bedrock OpenAI inference-profile calls that failed with Unknown parameter reasoningConfig when reasoning effort was set.

Cline Desktop v0.0.37: About & What's new surfaces; Bedrock OpenAI inference profiles fix reasoningConfig errors

Key Takeaways

  • Shipped: desktop-v0.0.37 vs desktop-v0.0.36 on GitHub Releases
  • UX: Settings About page with version/channel, update buttons, release notes links, Report an issue
  • Onboarding: one-time What's new after update; Highlights on About reopens it
  • Ops: macOS Help→Export Diagnostics opens the export directly
  • Bedrock: OpenAI models via us.openai./global.openai. inference profiles no longer fail on reasoningConfig when reasoning effort is set
Read full story

Cline Desktop v0.0.36: proxy-safe local hub, fit-to-screen UI, Bedrock GPT-6 without cross-region

Cline Desktop v0.0.36 (2026-09-25) skips system HTTP(S) proxies for local hub checks, fits oversized windows to small/scaled displays, loads plugin slash commands on workspace open, and runs Bedrock GPT-6/GPT-5.6 without cross-region inference (India via in. profiles).

Cline Desktop v0.0.36: proxy-safe local hub, fit-to-screen UI, Bedrock GPT-6 without cross-region

Key Takeaways

  • Local hub checks bypass system HTTP(S) proxies (Clash/v2ray/corporate)
  • Oversized windows shrink to fit and center on scaled 1080p displays
  • Plugin slash commands load on workspace open with background retry
  • Bedrock GPT-6/GPT-5.6 work without cross-region; India uses in. profiles
  • Artifacts: deb/rpm/dmg/exe + signatures; Providers panel scrolls model lists
Read full story
Linked Models & Agents:

Cline v4.1.21 Released: Refreshes Catalog to 6,386 Models Across 209 Providers, Defaults to Claude Opus 5.5

Open-source autonomous coding agent Cline (@cline_dev) shipped v4.1.21. The update refreshes Cline's model directory to 6,386 models across 209 providers, switching the resolved default to Anthropic's new Claude Opus 5.5 for 11 major providers (including GitHub Copilot and Google Cloud Vertex AI). It also introduces the Japanese open-weight provider ai& and patches a critical parser vulnerability in js-yaml.

Cline v4.1.21 Released: Refreshes Catalog to 6,386 Models Across 209 Providers, Defaults to Claude Opus 5.5

Key Takeaways

  • Expands provider coverage to 209 endpoints and 6,386 distinct models, the widest catalog among open-source coding agents.
  • Automatically updates the resolved default model to Claude Opus 5.5 across 11 major providers without user re-configuration.
  • Integrates OpenAI-compatible provider ai& to expand low-latency open-weight model serving in the Asia-Pacific region.
  • Upgrades core parser dependencies to js-yaml 4.3.2 to eradicate security vulnerabilities in untrusted config parsing.
Read full story

Cline v4.1.21: ai& Japan OpenAI-compatible provider, 6,386 models / 209 providers, local long-reply compact retry

Cline VS Code extension shipped v4.1.21 on 2026-09-24 with a new Japan OpenAI-compatible provider (ai&), a refreshed catalog of 6,386 models across 209 providers (19 unpinned defaults change—11 to Claude Opus 5.5 including GitHub Copilot and Vertex), and compact-and-retry once when local servers (llama.cpp/Ollama/LM Studio) hit output-token limits. Minimum js-yaml raised to 4.3.2 for frontmatter parsing security.

Cline v4.1.21: ai& Japan OpenAI-compatible provider, 6,386 models / 209 providers, local long-reply compact retry

Key Takeaways

  • New provider ai& (Japan OpenAI-compatible open-weight endpoint)
  • Catalog: 6,386 models / 209 providers; 19 unpinned defaults shift (11 → Opus 5.5 incl. Copilot & Vertex)
  • Local models compact-and-retry once on output-token caps
  • js-yaml floor 4.3.2 for rule/skill frontmatter
  • Install via Marketplace or cline-4.1.21.vsix
Read full story