AI Coding Live News

GitHub Universe 2026: Copilot Fusion is generally available, routing and orchestrating models automatically, with Fusion Max scoring 60 on the Artificial Analysis Coding Agent Index at about half the cost of Claude Code with Opus 5.5 Max

At GitHub Universe 2026 on Oct 28, GitHub made Copilot Fusion generally available. It merges the multi-model orchestration of the Project HydraFusion research preview with Copilot auto model selection: users pick Copilot Fusion and an effort level (Standard, High or Max) in the model picker, and the system decides which models to use and whether to run a Single, Cascade or Critique workflow. GitHub says Fusion Max scored 60 on the Artificial Analysis Coding Agent Index, two points below Claude Code with Opus 5.5 Max, at about half the API cost per task, about half the tokens and about 40% less time. Each underlying model is billed at its standard rate, and paid plans get 30% off through Nov 30.

GitHub Universe 2026: Copilot Fusion is generally available, routing and orchestrating models automatically, with Fusion Max scoring 60 on the Artificial Analysis Coding Agent Index at about half the cost of Claude Code with Opus 5.5 Max

Key Takeaways

  • Scores (Artificial Analysis Coding Agent Index v2.0): Fusion Max 60 versus 62 for Claude Code with Opus 5.5 Max; $5.59 per task versus $11.42, while the Devin Fusion pairing scores 62 at $8.00
  • Breakdown: a slight lead on Terminal-Bench 4.0 at 71, third on FrontierCode at 51 (Claude Code 56, Devin Fusion 54), and a weaker 57 on SWE-Atlas-QnA-AA
  • Efficiency: about 7.2M tokens per task, roughly half of Claude Code with Opus 5.5 and 30% fewer than Devin Fusion; GitHub reports about 40% less time per task
  • The pool includes Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra and GPT-6 Sol; admins can disable individual models for Fusion only and set Fusion as the default
  • Availability: all Copilot plans in VS Code, the Copilot app, Copilot CLI and JetBrains IDEs; existing auto, HydraFusion and HydraFusion Max selections migrate to matching effort levels
Read full story

Artificial Analysis launches Coding Agent Index v2.0: FrontierCode from Cognition replaces DeepSWE, and Claude Code with Opus 5.5 leads at 61.7

On 2026-10-23 Artificial Analysis launched Coding Agent Index v2.0, which scores model-plus-harness combinations across 290 tasks with three equally weighted benchmarks: FrontierCode v1.1 from Cognition (100 tasks on real open-source repos, graded on whether a maintainer would merge the change) replaces DeepSWE v1.1, SWE-Atlas-QnA becomes the stricter SWE-Atlas-QnA-AA, and Terminal-Bench 4.0 is unchanged. Claude Code with Claude Opus 5.5 (max) leads at 61.7, ahead of Sonnet 5.5 at 59.3 and Muse Wonder Full at 58.9. Scores fall across the board: the 21 configurations measured on both versions drop from a mean of 54.8 to 47.4.

Artificial Analysis launches Coding Agent Index v2.0: FrontierCode from Cognition replaces DeepSWE, and Claude Code with Opus 5.5 leads at 61.7

Key Takeaways

  • Top of the index: Claude Code with Claude Opus 5.5 (max) 61.7, Claude Sonnet 5.5 (max) 59.3, Muse Code with Muse Wonder Full (max) 58.9, Claude Fable 5.1 (max with fallback) 57.6 (Artificial Analysis figures)
  • On FrontierCode v1.1, Opus 5.5 scores 56.0%, ahead of Codex with DeepSeek V4.1 Flash at 52.6%; 15 of 24 configurations sit between 43% and 49%
  • Version shift: 21 configurations average 54.8 on v1.5 and 47.4 on v2.0, with 20 of 21 moving down; the same set averages 45.1% on FrontierCode versus 65.6% on DeepSWE
  • Four points on the cost frontier: DeepSeek V4.1 Flash 47.3 at $0.39 per task, GPT-6.1 Sol 54.1 at $1.50, GPT-6 Astra 54.7 at $7.04, Opus 5.5 61.7 at $11.42 (pay-per-token API costs, not subscriptions)
  • SWE-Atlas-QnA-AA rewords 127 of 1,306 rubric criteria and uses GPT-6 Luna (xhigh) as judge with five votes per criterion; dataset and judge config are on Hugging Face
Read full story

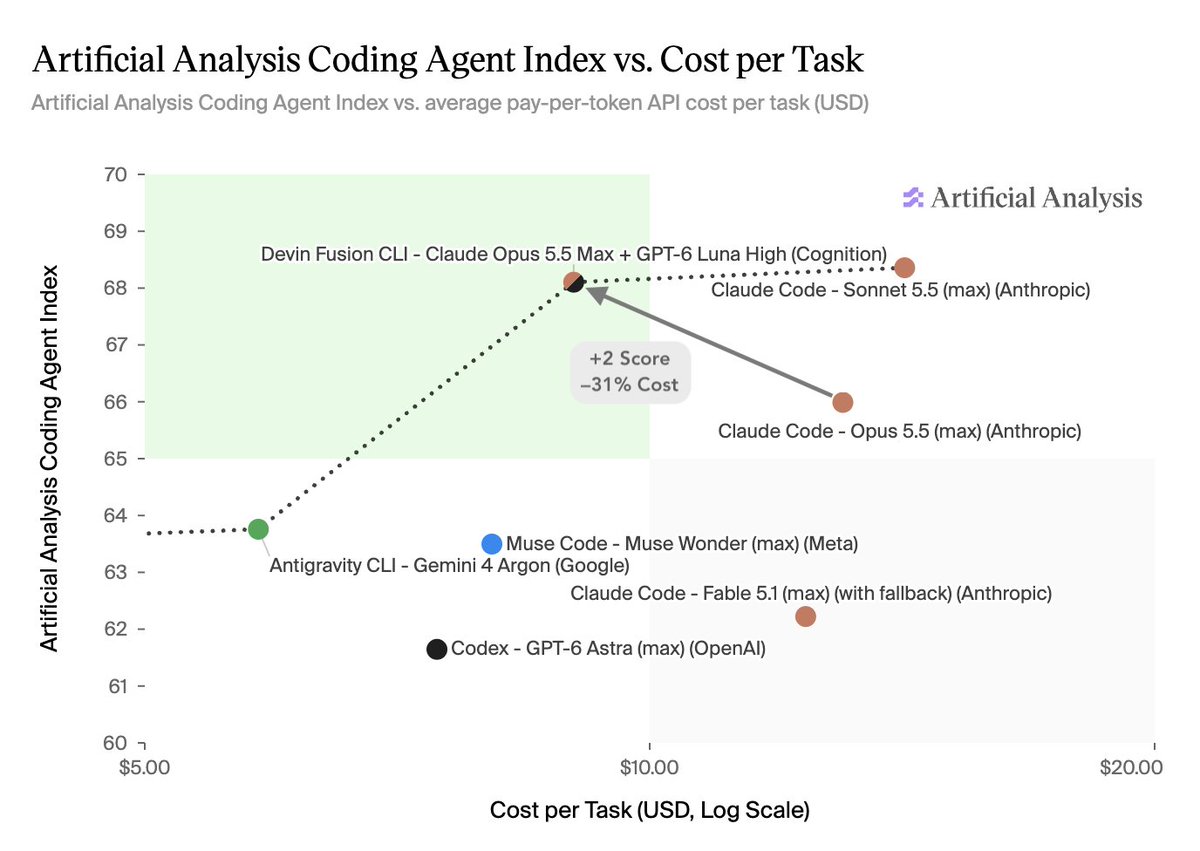
Artificial Analysis Benchmarks Devin Fusion: Scoring 68.1 on Coding Agent Index While Slashing Task Cost by 31%

Artificial Analysis released an independent evaluation of Cognition's new coding agent, Devin Fusion. Moving beyond single-model execution, Devin Fusion employs an asymmetric multi-agent architecture pairing Claude Opus 5.5 (max) as the lead reasoning orchestrator alongside GPT-6 Luna (high) as a high-speed parallel worker. In the standardized Coding Agent Index, Devin Fusion achieved an elite score of 68.1 (matching Muse Code at 68.0 and rivaling Claude Code Sonnet 5.5 at 68.4). Crucially, the hybrid architecture slashes average task expense from $13.04 down to $9.01 (a 31% cost reduction) while shortening execution runtime from 65 to 55 minutes.

Artificial Analysis Benchmarks Devin Fusion: Scoring 68.1 on Coding Agent Index While Slashing Task Cost by 31%

Key Takeaways

  • Artificial Analysis independently benchmarked Devin Fusion, scoring 68.1 on the standardized Coding Agent Index
  • Pioneers asymmetric model collaboration: Claude Opus 5.5 orchestrates architecture while GPT-6 Luna executes parallel sub-tasks
  • Cuts per-task execution costs from $13.04 to $9.01 (a 31% savings) and trims average completion time from 65 to 55 minutes
  • Outperforms Claude Code with Opus 5.5 on DeepSWE v1.1 (72.6% vs 68.4%) and SWE-Atlas-QnA (69.6% vs 66.4%)
Read full story

Devin Fusion with an Opus 5.5 lead and GPT-6 Luna sidekick tops the Artificial Analysis Coding Agent Index at 68.1, at what Cognition says is 31% lower cost per task than Claude Code with Opus 5.5

Cognition said on October 19 that Devin Fusion, pairing Claude Opus 5.5 as the lead with GPT-6 Luna as the sidekick, scored 68.1 on the Artificial Analysis Coding Agent Index v1.5. Artificial Analysis's current data puts it first, but only 0.1 ahead of Muse Code with Muse Wonder Full at 68.0, effectively a tie; Antigravity CLI with Gemini 4 Argon is third at 63.8. Cognition says the pairing costs 31% less per task than Claude Code with Opus 5.5 (vendor-reported). Fusion ships in Devin CLI and Desktop.

Devin Fusion with an Opus 5.5 lead and GPT-6 Luna sidekick tops the Artificial Analysis Coding Agent Index at 68.1, at what Cognition says is 31% lower cost per task than Claude Code with Opus 5.5

Key Takeaways

  • 68.1 overall: DeepSWE v1.1 72.6, SWE-Atlas-QnA 69.6, Terminal-Bench v4 62.1, equally weighted (Artificial Analysis data).
  • Just 0.1 ahead of Muse Code with Muse Wonder Full (68.0); Antigravity CLI with Gemini 4 Argon 63.8, Codex with GPT-6.1 Sol (xhigh) 62.9.
  • Cost: Cognition says 31% lower per task than Claude Code with Opus 5.5 (vendor-reported).
  • Earlier, Fusion with Fable 5.1 + SWE-2 cut DeepSWE 1.1 cost per task from $14.63 to $7.88 (-46%) while scoring 63.1 vs 64.3.
  • Recommended pairing is Opus 5.5 + GPT-6 Luna, available by installing Devin CLI.
Read full story
ADSponsored

Artificial Analysis: Grok 4.7 + Grok Build hits Coding Agent Index 56 (4th); Intelligence Index 46 puts SpaceXAI in top 4 labs

@ArtificialAnlys evaluated Grok 4.7 (xhigh): Intelligence Index 46 (+2 vs 4.6), putting SpaceXAI in the top 4 labs. With Grok Build it scores 56 on the Coding Agent Index (+9 vs 4.6), 4th among native harnesses behind Claude Fable 5.1, GPT-6 Astra, and Claude Opus 5. Pricing stays $2/$6 per 1M in/out ($0.50 cache hits), 500k context.

Artificial Analysis: Grok 4.7 + Grok Build hits Coding Agent Index 56 (4th); Intelligence Index 46 puts SpaceXAI in top 4 labs

Key Takeaways

  • Coding Agent Index: Grok 4.7 + Grok Build scores 56 (+9), 4th among native harnesses.
  • Intelligence Index 46 (+2) puts SpaceXAI in the top 4 labs; +111 Elo on AA-Briefcase.
  • Same $2/$6 per 1M pricing as 4.6 ($0.50 cache hits), 500k context; gains come with higher token use.
Read full story

Artificial Analysis: Devin Fusion joins Coding Agent Index; Fable scores 62, Astra cheaper/faster

Artificial Analysis independently benchmarked Devin Fusion—the first multi-model coding agent on their Coding Agent Index. Claude Fable 5.1 (xhigh)+SWE-2 scores 62; GPT-6 Astra (xhigh)+SWE-2 scores 59 with ~43% lower cost and ~31% faster completion while retaining frontier-level performance.

Key Takeaways

  • First multi-model coding agent on Artificial Analysis Coding Agent Index.
  • Fable 5.1+SWE-2 scores 62; Astra+SWE-2 scores 59.
  • Astra config ~43% cheaper and ~31% faster task completion.
Read full story

Artificial Analysis: GPT-6 Astra ties Fable 5 on Coding Agent Index at ~half the cost

Artificial Analysis rated GPT-6 Astra: Coding Agent Index 67 in Codex, roughly matching Claude Opus 5 / Fable 5 in Claude Code and Muse Spark 1.3 in Muse Code, with ~70% better token efficiency vs GPT-5.6 Sol (max). List price rises to $10/$50 per 1M in/out (2.5× Sol), yet per-task cost stays well below Fable 5. Intelligence Index stays 61, tied with Sol.

Key Takeaways

  • Coding Agent Index: 67 in Codex, near Opus 5 / Fable 5 / Muse Spark 1.3; Fable 5.1 still leads at 70.
  • ~2/3 fewer tokens vs GPT-5.6 Sol (max); multiple effort levels sit on the token-efficiency Pareto frontier.
  • List price $10/$50 (90% cache-read discount); Intelligence Index 61; hallucination rate ~92%→~51%.
Read full story

Artificial Analysis: Muse Spark 1.3 Coding Agent Index 64 (xhigh), 68 (max preview)

Artificial Analysis (@ArtificialAnlys) published Meta Muse Spark 1.3 results on the Coding Agent Index in the Muse Code harness: the publicly available xhigh variant scores 64 (up 2 from Muse Spark 1.2 at 62) at about $1.72 per task—the cheapest agent above a 60 index score—while the partner-preview max variant scores 68, tied just behind Claude Opus 5 (xhigh) in Claude Code. Claude Fable 5.1 results are still pending.

Key Takeaways

  • Muse Spark 1.3 (xhigh) scores 64 on the Coding Agent Index in Muse Code, up 2 from 1.2 (62).
  • About $1.72 per task—cheapest agent above a 60 index score, roughly one-fifth of Claude Opus 5 (xhigh) in Claude Code ($8.17).
  • Partner-preview max variant scores 68, second only to Claude Opus 5 (xhigh); Fable 5.1 results still pending.
Read full story