AI Coding Live News

Microsoft opens the GitHub-built Copilot harness in Foundry Agent Service: public preview, 20+ frontier models plus BYOK, billing from Dec 1

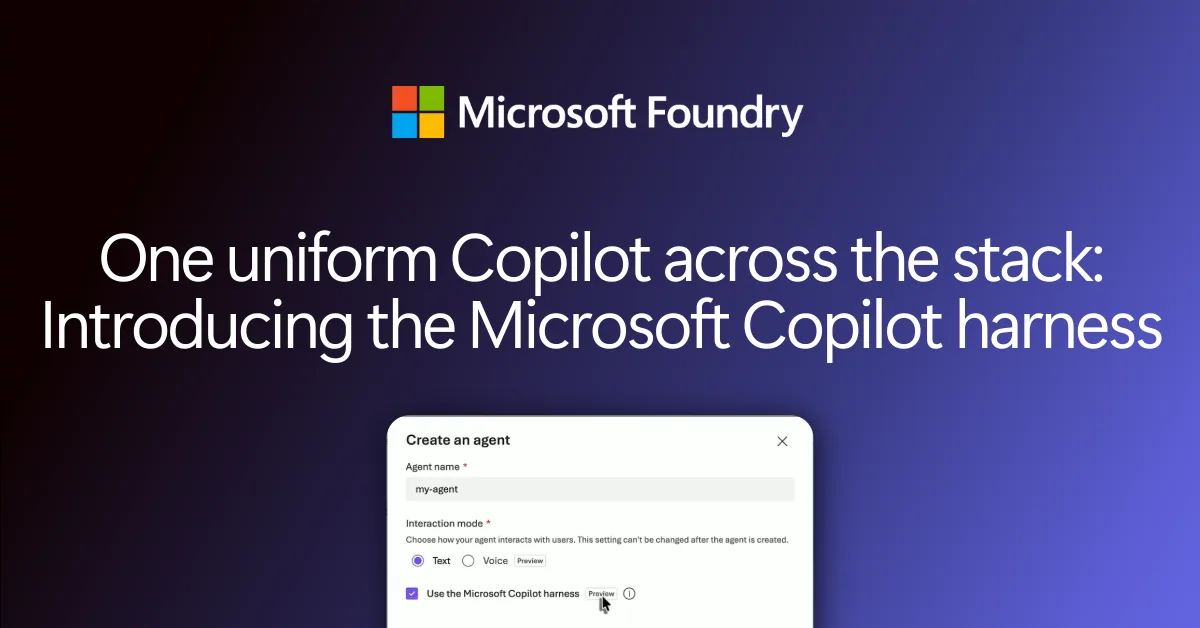
During GitHub Universe on Oct 28, Microsoft put the Microsoft Copilot harness, the shared agent execution layer behind Copilot Code, Copilot Studio, the GitHub Copilot app, the CLI and VS Code, into Foundry Agent Service as a public preview. Microsoft runs the agent loop and sandbox while developers supply instructions, skills, tools and model choice; Microsoft says it works across 20+ frontier models plus bring-your-own-key. Long-running resilience for hosted agents also reached GA. Harness runtime usage is free until Dec 1.
Microsoft opens the GitHub-built Copilot harness in Foundry Agent Service: public preview, 20+ frontier models plus BYOK, billing from Dec 1

Key Takeaways

  • Microsoft says the harness spans 20+ frontier models plus bring-your-own-key, so you can swap models without rewriting orchestration (official blog)
  • Preview building blocks: reusable skills, Foundry and MCP tools with explicit auth and approvals, file and code execution with built-in subagent delegation, and source-controlled agent definitions
  • Pricing: harness runtime is free until Dec 1; after that sandbox compute is USD 0.0994 per vCPU-hour and 0.0118 per GiB-hour, with model inference billed separately (Foundry blog)
  • Long-running resilience for hosted agents went GA the same week: interrupted work restarts with its original input, and your app saves checkpoints
  • Limits: you pick the harness only when creating a new agent; existing agents are unchanged and switching later is not supported yet
Read full story

Microsoft FY27 Q1: Azure growth accelerates to 48%, Foundry revenue more than triples, and Agent 365 now governs 50M agents

On Oct 28, Microsoft reported results for its fiscal Q1 2027, the quarter ended Sep 30: revenue of $92.3B (+19%), Microsoft Cloud revenue of $63.9B (+30%), Azure growth accelerating from 42% last quarter to 48%, and commercial remaining performance obligation of $677B (+73%). CEO Satya Nadella added AI figures on X: Foundry revenue more than tripled year over year, revenue from open source models grew 10x, Copilot daily users grew nearly 50% quarter over quarter, and Agent 365 now holds over 50M agents. Separately, TechCrunch, citing Microsoft's regulatory filing, reports $10B of revenue from OpenAI-related commercial arrangements this quarter.

Microsoft FY27 Q1: Azure growth accelerates to 48%, Foundry revenue more than triples, and Agent 365 now governs 50M agents

Key Takeaways

  • Revenue of $92.3B (+19%) and operating income of $45.9B (+21%); Microsoft Cloud reached $63.9B (+30%) (earnings release)
  • Azure grew 48%, accelerating from 42% in FY26 Q4; commercial RPO reached $677B (+73%) (official investor metrics)
  • Foundry revenue more than tripled YoY, customers building with multiple models grew 5x, and open source model revenue grew 10x (per Satya Nadella on X)
  • Copilot daily users grew nearly 50% QoQ and more than 5x YoY; Agent 365 holds over 50M agents, up 30% QoQ
  • Per TechCrunch citing the 10-Q, OpenAI-related revenue was $10B, about 11% of the total; OpenAI investments added $207M to GAAP net income
Read full story

Microsoft makes MAI-Image-2.6 and MAI-Image-2.6-Flash generally available in Foundry as MAI-Image-2.7-Preview reaches #3 in Image Edit Arena

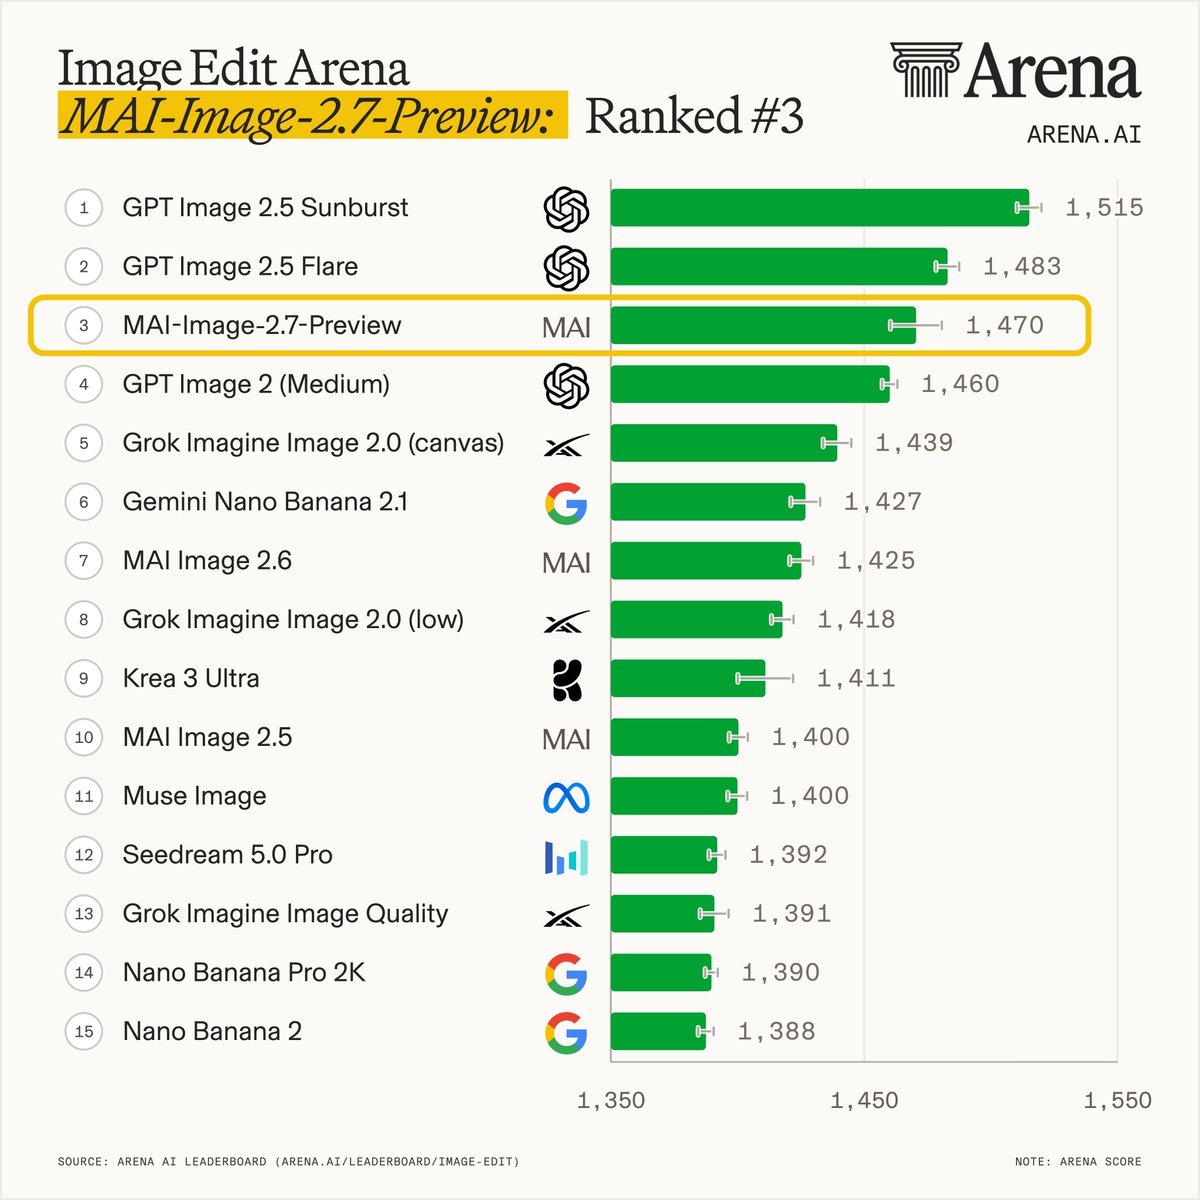
Microsoft AI announced on Oct 27 that MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, with multi-reference editing from up to five images, Bing web grounding, output up to 1.5K and published per-token pricing. The same day its next image editing model, MAI-Image-2.7-Preview, reached #3 overall in Arena's Image Edit leaderboard at 1470 points, 45 points above 2.6; for now it is available only for editing in MAI Playground.

Microsoft makes MAI-Image-2.6 and MAI-Image-2.6-Flash generally available in Foundry as MAI-Image-2.7-Preview reaches #3 in Image Edit Arena

Key Takeaways

  • MAI-Image-2.6 and MAI-Image-2.6-Flash are generally available in Microsoft Foundry, and Microsoft says 2.6 is coming soon to Adobe Firefly
  • Official pricing: 2.6 costs $5 text input, $8 image input and $38 image output per 1M tokens; Flash costs $1.75, $2.50 and $19
  • 2.6 supports multi-reference editing with up to five images, Bing web grounding, dynamic aspect ratios and output up to 1.5K
  • Per Arena, MAI-Image-2.7-Preview is #3 overall in Image Edit Arena at 1470 points, 45 points above 2.6 (#7), putting Microsoft AI #2 among labs
  • Per Artificial Analysis, 2.7-Preview is #2 on AA-Image-Editing v2.1 and beats 2.6 on all 7 editing actions, ranking #1 on 4 of them
Read full story
Linked Models & Agents:
⚡ MAI-Image-2.6⚡ MAI-Image-2.6-Flash⚡ MAI-Image-2.7-Preview🌐 Microsoft🌐 Microsoft AI
A
Anthropicgithub.com·
👀65
🔥82

Claude Code 2.1.304 adds guided /auto-mode-setup and warns Pro/Max users before resuming an inactive conversation would eat into the 5-hour usage limit

Claude Code v2.1.304 (Oct 19 UTC) adds /auto-mode-setup, a guided setup that reads your project and recent sessions to teach auto mode about your environment, now also on Bedrock, Vertex, Foundry, Claude apps gateway and telemetry-disabled sessions. It adds a read-only /claude-api managed-agents-secure check against Anthropic's security guide, warns Pro/Max users when resuming an inactive conversation would use a noticeable share of the 5-hour limit, and fixes 40+ issues including claude --worktree deleting a worktree and branch without asking, which could lose commits.

Key Takeaways

  • New /auto-mode-setup reads your project and recent sessions to teach auto mode your environment, now on Bedrock, Vertex, Foundry, Claude apps gateway and telemetry-disabled sessions
  • New read-only /claude-api managed-agents-secure compares a Managed Agents agent's settings with Anthropic's published security guide
  • Pro/Max plans get a warning when resuming an inactive conversation would use a noticeable share of the 5-hour usage limit
  • Mods gain decider: "person" and e.isReadOnly in tool.check, so only a human permission dialog can approve certain calls
  • 40+ fixes, incl. claude --worktree removing the worktree and branch without asking (could lose commits) and CLAUDE_CODE_AUTO_COMPACT_WINDOW=200k silently becoming 100K
Read full story
ADSponsored

Microsoft AI finishes pre-training MAI-Base-2: 2.8T-total / 80B-active MoE trained on 16K GB200s in 38 days, which MAI estimates is 4.2–12.3x more FLOPs-efficient than DeepSeek-V4-Pro-Base

On 2026-10-15 Microsoft AI published a technical post and PDF saying it has finished pre-training its in-house base model MAI-Base-2: MoE in every layer (1 shared + 7-of-512 routed experts), 80B active / 2.8T total, 102 layers, native encoder-free vision, a 50T-token mixture and a March 2026 knowledge cutoff. Per MAI, it beats every open-weight model tested on held-out BPB and its recipe is 4.2–12.3x more pre-training-FLOPs-efficient than DeepSeek-V4-Pro-Base. It is still in post-training: no API, no weights and no release date yet; Microsoft plans to license weights to trusted partners via Foundry.

Microsoft AI finishes pre-training MAI-Base-2: 2.8T-total / 80B-active MoE trained on 16K GB200s in 38 days, which MAI estimates is 4.2–12.3x more FLOPs-efficient than DeepSeek-V4-Pro-Base

Key Takeaways

  • Scale: 80B active / 2.8T total, 102 layers, hidden 8704, MoE in every layer (1 shared + 7 of 512 routed); MAI-Base-1 was 35B/1T, 78 layers, alternating dense/MoE (PDF)
  • Compute: 16K GB200s for 38 days (Aug–Sep 2026), 21% average MFU (vs 2.5 PFLOPS BF16), 89% goodput; the Muon step is 2.1% (165 ms) of iteration time
  • Efficiency (vendor estimate via scaling-law fits): 4.2–12.3x fewer FLOPs than DeepSeek-V4-Pro-Base to match its BPB; 6.3–12.7x better than the June MAI-Base-1 recipe
  • Data: 50T-token mixture, 18% vision-language (4.5T unique), ~36% more unique tokens than Base-1, described as organic data with no distillation
  • Availability: still in post-training, no API/weights/date; weights to be licensed to trusted partners through Foundry; MAI-Base-3 prep underway (blog)
Read full story
Linked Models & Agents:
⚡ MAI-Base-2⚡ MAI-Base-1⚡ MAI-Thinking-1⚡ DeepSeek-V4-Pro-Base⚡ Kimi K3⚡ Qwen3.8-2.4T-A95B🌐 Microsoft🌐 NVIDIA🌐 DeepSeek

Claude Opus 5.5 fast mode leaves research preview and drops the waitlist: same model, up to 2.5x output speed at $8/$40 per MTok

On 2026-10-15 Anthropic moved Claude Opus 5.5 fast mode out of research preview and removed the waitlist: no access request and no fast-mode-2026-02-01 beta header needed, just speed: "fast". Same weights, up to 2.5x output tokens/sec per Anthropic, at 2x standard price ($8/$40 per MTok). Start/Build/Scale tiers get a default fast rate limit; it is live on Microsoft Foundry (Azure-hosted) with Google Cloud coming soon. Opus 5 and Opus 4.8 fast mode remain in research preview.

Key Takeaways

  • Pricing: Opus 5.5 fast is $8/$40 per MTok, 2x the $4/$20 standard; Opus 5/4.8 fast stay in preview at $10/$50 (docs)
  • Speed: up to 2.5x output tokens/sec per Anthropic; gains are OTPS, not TTFT; same weights
  • Access: no request and no beta header; default dedicated fast limits on Start/Build/Scale tiers (release notes)
  • Platforms: Claude API (incl. Managed Agents) and Microsoft Foundry Azure-hosted; Google Cloud coming soon; not on Batch API, Priority Tier, or Claude Platform on AWS
  • Gotchas: switching speeds invalidates the prompt cache; 429 on limit; check usage.speed
Read full story

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

On 2026-10-15 Meta released Muse Spark Open open weights: an 816B-total / 42B-active MoE with a Perception Encoder, natively multimodal (text/image/video/audio in → text out), 1M context, aimed at coding and long-horizon agents. Weights are on Hugging Face (BF16/NVFP4), SageMaker, Model Garden and Foundry; APIs include OpenRouter, Together, Fireworks and Groq. Meta calls it the most capable US open-weight model to date and, with Apple, optimized it to run locally across two M5 Ultra Mac Studios via MLX.

Meta open-sources Muse Spark Open: 816B/42B natively multimodal US open-weight flagship, runs on two M5 Ultra Mac Studios

Key Takeaways

  • Specs: MoE 816B total / 42B active (256 experts, top-8), 62 layers, 1M context; text+image+video+audio in → text out (model card)
  • Local: NVFP4 needs ≥~700GB VRAM, BF16 ~2TB; or two Apple M5 Ultra Mac Studios via MLX (Meta blog)
  • Agentic benches (xhigh, official table): MCP-Atlas 89.2, JobBench 61.8, OSWorld Verified 80.4, Terminal-Bench 2.1 76.4, DeepSWE 1.1 60, AA Intelligence Index 39
  • Serve with SGLang / vLLM / TensorRT-LLM / Transformers / llama.cpp / Unsloth / MLX; Helion kernels claim 1.03–3.95× kernel speedups on NVIDIA/AMD
  • License: Muse Model License (display “Built with Muse Spark Open”; MaaS over $20M/yr needs a separate deal); OpenRouter ~$1.25/M in, $4.25/M out
Read full story
Linked Models & Agents:

Microsoft launches Microsoft-Decision-1: a Qwen3.5-9B-based decision-scoring model at $0.042/M input tokens, free output, on Foundry and OpenRouter

On Oct 9 Microsoft released Microsoft-Decision-1, a decision-scoring model that returns calibrated probabilities over fixed options instead of generating text, aimed at routing, classification, verification, agent guardrails and AI judging. Microsoft reports top accuracy across 36 blind benchmarks, ~35x lower P50 latency than GPT-6 Sol and a 1.3% decision-flip rate under perturbation. Available on Microsoft Foundry and OpenRouter, 32K context, $0.042/M input, free output.

Microsoft launches Microsoft-Decision-1: a Qwen3.5-9B-based decision-scoring model at $0.042/M input tokens, free output, on Foundry and OpenRouter

Key Takeaways

  • Pricing: $0.042/M input tokens, $0 output, 32,768-token context (OpenRouter)
  • Vendor-reported: highest accuracy across 36 blind benchmarks (~150K questions); 2.5x faster than runner-up H2O-Lightning-4B v1.1 and 35x faster than GPT-6 Sol
  • Robustness: 1.3% average decision flips across 8 perturbation types; zero flips when options are paraphrased, reversed or shuffled
  • Base: post-trained from Qwen3.5-9B for single-pass scoring; Microsoft plans to rebase on MAI and OpenAI models
  • Internal use: Xbox Research labeled 10K+ feedback items at near GPT-6 Sol quality, 14x+ faster and ~200x cheaper (vendor-reported)
Read full story
Linked Models & Agents:
⚡ Microsoft-Decision-1⚡ Qwen3.5-9B⚡ GPT-6 Sol🌐 Microsoft🌐 OpenRouter

Cohere Embed 5 ships: Pro/Fast shared space; ViDoRe V3 Pro 85.8 avg; Fast at $0.08/M tokens

On 2026-09-30 Cohere launched Embed 5 with Pro and Fast tiers that share one embedding space (index with Pro, query with Fast). Multimodal text/image/fused inputs, 128K context, 100+ languages; API ids embed-v5.0-pro / embed-v5.0-fast. Blog: ViDoRe V3 Pro avg 85.8 (+8.8 vs Embed 4); text pricing $0.12 / $0.08 per M tokens. Available on Cohere API, Model Vault, Azure Foundry, SageMaker; vLLM for private deploy.

Cohere Embed 5 ships: Pro/Fast shared space; ViDoRe V3 Pro 85.8 avg; Fast at $0.08/M tokens

Key Takeaways

  • Shipped 2026-09-30: cohere.com/blog/embed-5 + docs.cohere.com/docs/cohere-embed
  • Shared space: index Pro / query Fast; cross-model mean loss ~1.6–2.7% vs same-model on 40 dev sets
  • ViDoRe V3: Pro 85.8 (+8.8 vs Embed 4) vs Voyage 4 Large 83.7 / Gemini Embedding 2 83.2; Fast 84.5
  • 128K ctx; dims 2048…256; float/int8/binary + Matryoshka; text $0.12/$0.08 per M (image $0.40/M both)
  • API embed-v5.0-pro/fast; Foundry/SageMaker/vLLM; LangChain/Weaviate/Qdrant/Pinecone integrations
Read full story
Linked Models & Agents:
⚡ Embed 5 Pro⚡ Embed 5 Fast⚡ embed-v5.0-pro⚡ embed-v5.0-fast⚡ Embed 4🤖 rag🤖 agentic-retrieval🌐 Cohere🌐 Microsoft Azure AI🌐 aws

Claude Code 2.1.287: Mods in-process extensions; built-in You should know side agent; 1M context default on gateways

Anthropic shipped Claude Code 2.1.287 on 2026-10-01 (npm @anthropic-ai/[email protected]): Claude Mods let plugins run in-process JS/TS hooks that rewrite tool calls and UI; opt-in built-in You should know side agent; MCP URL elicitation; Opus 4.7+/Fable default to 1M context on Bedrock/Vertex/Foundry/apps gateway. Agent SDK TS 0.3.287 parity.

Claude Code 2.1.287: Mods in-process extensions; built-in You should know side agent; 1M context default on gateways

Key Takeaways

  • Release v2.1.287; npm 2.1.287; GitHub ~2026-10-01T18:00:22Z
  • Mods: in-process hooks for UI + tool.call rewrite; ≥2.1.287; docs https://code.claude.com/docs/en/plugins/mods/overview
  • You should know: /plugin enable cc-plugin-you-should-know@builtin (first-party + telemetry); off by default
  • 1M context default for Opus 4.7+/Fable on Bedrock/Vertex/Foundry/apps gateway; disable via CLAUDE_CODE_DISABLE_1M_CONTEXT=1
  • Agent SDK TS 0.3.287; MCP URL elicitation / bareElicitationCapability
Read full story
ADSponsored

LiteLLM 1.103.2: forward Claude Code safeguards; attribute CLI session spend; restore pass-through pre-config wins

BerriAI shipped LiteLLM v1.103.2 on 2026-10-01 (PyPI ~06:20Z; 17 commits vs 1.103.1): forward Claude Code safeguards / dangerous-tool-use beta unchanged to Anthropic, Bedrock, Vertex, and Azure AI Foundry so auto mode works behind the proxy; attribute CLI session spend to a per-user cli-session alias for daily activity BI; restore pre-config-wins for pass-through endpoints.

LiteLLM 1.103.2: forward Claude Code safeguards; attribute CLI session spend; restore pass-through pre-config wins

Key Takeaways

  • Release v1.103.2 at 2026-10-01T06:37:31Z; 17 commits vs v1.103.1
  • Forward Claude Code safeguards + dangerous-tool-use beta to Anthropic/Bedrock/Vertex/Azure Foundry so auto mode returns safeguard_results
  • CLI session spend attributed to per-user cli-session alias for daily activity BI (#40541/#43642/#43656)
  • Restore pass-through pre-config-wins (#43962); verify Docker with cosign
  • pip install 'litellm==1.103.2'; https://docs.litellm.ai/docs/ ; https://pypi.org/project/litellm/1.103.2/
Read full story
n
n8nn8n-io·
👀77
🔥90

n8n 2.42.0: Agents on by default; AI Agent Tool nesting; MCP client/registry + Azure AI Foundry rename

n8n shipped [email protected] on 2026-09-29: Agents enabled by default (#39312); AI Agent Tool can use its own tools under a pre-v3 parent agent (#39160); MCP Client terminates sessions before close, MCP Registry flag removed from AI Assistant, editor adds Mistral Vibe to MCP picker; Azure OpenAI Chat Model renamed Azure AI Foundry with project/deployment listing and Entra app sign-in; plus shared Agent context and Agent Builder UX polish.

n8n 2.42.0: Agents on by default; AI Agent Tool nesting; MCP client/registry + Azure AI Foundry rename

Key Takeaways

  • Release [email protected] on 2026-09-29; compare 2.41.0...2.42.0
  • Agents enabled by default (#39312); shared Agent context (#38930)
  • AI Agent Tool nests its own tools under pre-v3 parents (#39160)
  • MCP: terminate session on client close; Registry ungated in AI Assistant; Mistral Vibe in MCP picker
  • Azure OpenAI node renamed Azure AI Foundry Chat Model; docs AI Agents
Read full story

Claude Code 2.1.278: Auto Mode defaults to server-side classifier

Claude Code 2.1.278 changes Auto Mode for Claude API, Enterprise, and Bedrock/Vertex/Foundry/gateway users to default to the server-side classifier, which does not charge classifier overhead. Set CLAUDE_CODE_AUTO_MODE_SERVER=0 to opt out on gateways; billed fallback warns. /status adds an Auto mode server row for the session.

Key Takeaways

  • Auto Mode defaults to the server-side classifier with no classifier overhead; gateways can opt out via CLAUDE_CODE_AUTO_MODE_SERVER=0.
  • Warns on billed fallback; see code.claude.com/docs/en/auto-mode-classifier-billing.
  • /status shows Auto mode server; notes at github.com/anthropics/claude-code/releases/tag/v2.1.278.
Read full story

Claude Code 2.1.277: read AGENTS.md when CLAUDE.md is missing

Anthropic staff announced that Claude Code 2.1.277 adds AGENTS.md support: if a project folder has no CLAUDE.md, Claude reads AGENTS.md for project instructions, toggleable under Project instructions in /config. The official changelog lists about 87 CLI changes, including fixing silent hangs in claude -p and Agent SDK sessions after internal errors. The feature is not yet available on Bedrock, Vertex, or Foundry.

Key Takeaways

  • From 2.1.277, Claude reads AGENTS.md when CLAUDE.md is absent; toggle under /config Project instructions.
  • Lets teams share AGENTS.md with tools like Codex instead of maintaining two instruction files.
  • Also fixes silent hangs in claude -p / Agent SDK; notes at github.com/anthropics/claude-code/releases/tag/v2.1.277.
Read full story

Azure DevOps Remote MCP is GA: hosted streamable-HTTP endpoint with Entra auth, no sidecar

Microsoft announced Azure DevOps Remote MCP is generally available: a hosted streamable-HTTP endpoint at https://mcp.dev.azure.com/{org} with Entra auth and no sidecar. Drop it into mcp.json for VS Code Copilot, Foundry, Copilot Studio, and VS/CLI/apps; Claude, Cursor, and ChatGPT stay on a local bridge until Entra DCR/CIMD lands.

Key Takeaways

  • GA: hosted Remote MCP with streamable HTTP + Entra and no sidecar.
  • Connect: put mcp.dev.azure.com/{org} in mcp.json for VS Code Copilot / Foundry / Copilot Studio.
  • Limit: Claude / Cursor / ChatGPT still use a local bridge pending Entra DCR/CIMD.
Read full story
Linked Models & Agents: