AI Coding Live News

Epoch AI: open-weight GLM 5.3 autonomously exploited the patch gap in six Firefox releases for about $1,000 each

Epoch AI reported on Oct 29 that, in a deliberately basic setup emulating an unsophisticated attacker, Z.ai's open-weight GLM 5.3 read security fixes that were public but not yet shipped and autonomously built exploit chains for all six Firefox releases from Sep 17 to Oct 26, letting a single webpage visit read local files. Marginal cost was about $1,000 per version and the fastest run took 12 hours. Mozilla patched a previously undisclosed bug the model also used in Firefox 159.0 on Oct 27.
Epoch AI: open-weight GLM 5.3 autonomously exploited the patch gap in six Firefox releases for about $1,000 each

Key Takeaways

  • 6 of 6: every Firefox release from Sep 17 to Oct 26 was compromised using only information public at each release (Epoch report)
  • About $1,000 marginal cost per version, with a 48-hour budget and the fastest run at 12 hours; total Firefox research spend exceeded $100,000 including setup
  • The model also rediscovered an unpublished bug on each attempt, which Mozilla fixed in Firefox 159.0 on Oct 27
  • No refusals or safeguards triggered through first-party or third-party APIs
  • Roughly $100,000 of attempts against Chrome failed so far, which Epoch says is not strong evidence Chrome is safe
Read full story

Mistral launches its Responses API in public preview: OpenAI Responses-compatible, returning the answer, reasoning and tool calls as separate items for building agents

Mistral AI announced on X on Oct 28 that its Responses API is in public preview, positioned as the interface for building agents on Mistral. The official docs say it uses the OpenAI Responses format, and each response's output array carries the models messages, its reasoning and its function calls as separate items, which is easier to handle step by step than Chat Completions. The preview is stateless, so the app keeps the conversation history and sends it back; it supports text, image and file input, JSON Schema structured output, streaming events, client-executed function calls, reasoning.effort, and token counting via POST /v1/responses/input_tokens. It is served in the EU and US on Mistral AI Cloud Inference. The same thread says Mistral now also serves DeepSeek V4.1 Flash (public preview) and GLM 5.3 Flash (generally available).

Key Takeaways

  • The Responses API is in public preview and uses the OpenAI Responses format, so existing Responses integrations can move to Mistral more easily
  • Each response splits the answer, reasoning and function calls into separate output items, which suits step-by-step agent loops
  • The preview is stateless: the app keeps the history and sends earlier output items back along with function_call_output results
  • It supports image and file input, JSON Schema structured output, streaming, function calling (including namespaces), reasoning.effort and token counting via /v1/responses/input_tokens
  • It is served in the EU and US on Mistral AI Cloud Inference; Mistral also added DeepSeek V4.1 Flash (preview) and GLM 5.3 Flash (GA)
Read full story

humans& releases its first model, Ampersand v0.1: a group-collaboration model trained from GLM 5.3, now open via its Agents API

On Oct 20, AI startup humans& released its first model, Ampersand v0.1, pitched as a collaborator that helps groups reach individual and shared goals rather than an assistant that completes tasks alone. It is trained from Z.ai's GLM 5.3 (about 744B total, about 40B active parameters) with long-horizon multi-party RL against simulated users played by humans&'s own user model, Persimmon. It is available now, with no waitlist, through an API compatible with OpenAI's Agents API.

humans& releases its first model, Ampersand v0.1: a group-collaboration model trained from GLM 5.3, now open via its Agents API

Key Takeaways

  • Base: GLM 5.3 MoE with about 744B total and about 40B active parameters and a 1,048,576-token context (official model card)
  • Long-term collaboration simulation (vendor figures): 12.94 for Ampersand versus 9.89 for base GLM 5.3
  • Collaborative Intelligence teamwork 59.1% (GLM 5.3: 54.3%); CooperBench cooperative success 39.0% versus 17.3% for GLM 5.3
  • Trade-off: SWE-bench Pro v2 (Hard-51) 82.4%, slightly below the base model's 84.3%; humans& also admits it sometimes over-coaches
  • Access: model ID ampersand-v0.1, usable with the official OpenAI SDK pointed at the humans& base URL
Read full story
Linked Models & Agents:

OpenCode Makes GLM 5.3 Flash and 1M-Context Reflection Beam Free in Its Open-Source Coding Agent, Drawing 1.92M+ Views

OpenCode (@opencode), the wildly popular open-source terminal coding agent, announced free access to both Zhipu AI's high-speed GLM 5.3 Flash and Reflection AI's newly released 501B/23B MoE model Beam with a full 1M-token context window. The GLM 5.3 Flash announcement alone surged past 1.92 million views and 17,500 likes on X within hours.

OpenCode Makes GLM 5.3 Flash and 1M-Context Reflection Beam Free in Its Open-Source Coding Agent, Drawing 1.92M+ Views

Key Takeaways

  • Viral 1.92M-view developer launch: OpenCode's free GLM 5.3 Flash rollout drew 1.92M+ views and 17.5K likes on X
  • 1M-context Reflection Beam added for free: integrates the 501B/23B MoE model (80.1% on Terminal-Bench 2.1) with a full 1M-token context window
  • Zero-cost dual coding workflow: pairs ultra-fast GLM 5.3 Flash tool loops with 1M-context whole-repo reasoning inside the open-source OpenCode CLI
Read full story
ADSponsored

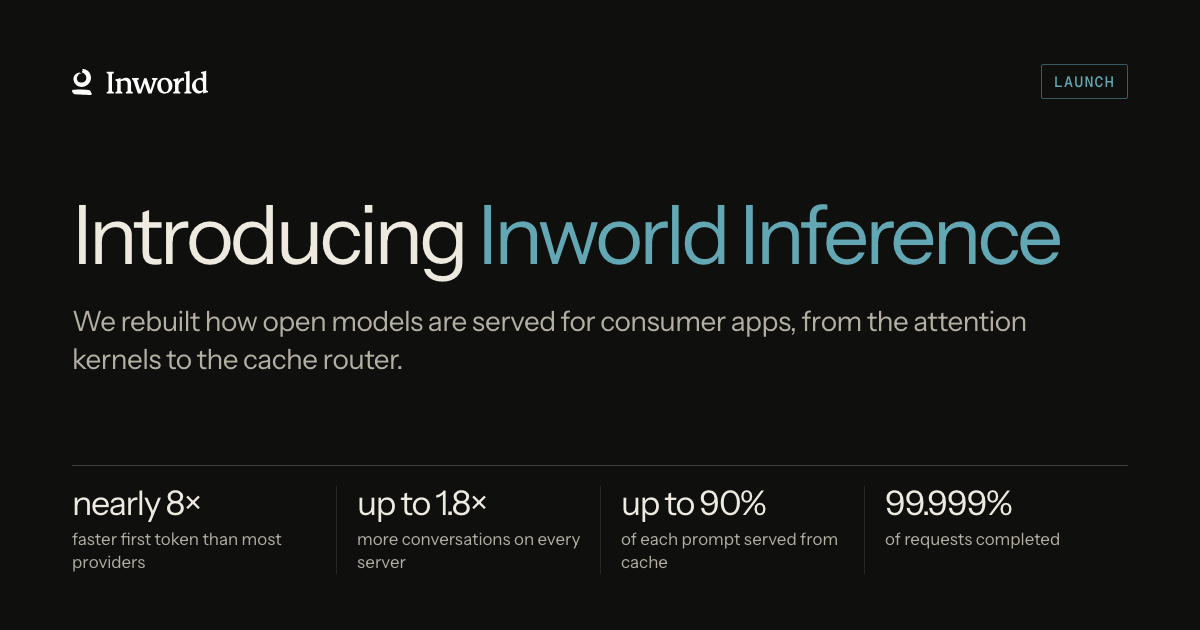
Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

On 2026-10-14 Inworld AI opened Inworld Inference to every developer, positioning it as an inference service for consumer apps (companions, tutors, voice, interactive fiction). Instead of listing thousands of models it builds a per-model serving stack for open models such as Gemma 4, GLM 5.3 Flash, DeepSeek and MiMo: draft-and-verify (speculative) decoding, a rewritten split-KV verify attention kernel, KV-aware routing and eval-gated low precision. Vendor-reported: Gemma 4 26B p95 first token of 0.31 s, 7.8x faster than the median OpenRouter provider; up to 90% of prompts from cache; 99.999% success over 20M+ GLM 5.3 Flash requests in 30 days. The API is OpenAI-compatible with Flex/Default/Priority/Fast tiers per request.

Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

Key Takeaways

  • Gemma 4 26B first token: p50 0.17 s / p95 0.31 s, 3.6x / 7.8x faster than the median OpenRouter provider (blog, vendor-reported snapshot, not a matched workload)
  • Pricing: Gemma 4 26B at $0.07 input, $0.035 cached, $0.34 output per 1M tokens, nearly 40% below the median no-training provider
  • Rewritten verify attention: 3.4–7.5x faster per layer, attention share of a decode step 27.5%→16.5%, p50 TTFT 154→117 ms at equal eval scores
  • KV-aware routing: GLM 5.3 Flash cache hits 25%→47%, DeepSeek V4.1 Flash 11%→33%; cached MiMo 2.6 Pro input costs 99% less
  • Reliability: 98 failures across 20M+ GLM 5.3 Flash requests in 30 days (~4.8 per million); per-request service_tier of Flex/Default/Priority/Fast
Read full story

DigitalOcean Agent Droplets: harness + inference + 16k tools in one monthly plan from $50/$200

On 2026-10-01 DigitalOcean launched Agent Droplets for Managed Agents (public preview): Pro $50/mo (15% off) and Team $200/mo (20% off) bundling Harness Runtime microVMs, DO-hosted open-model inference (Kimi K3, GLM 5.3), session storage, and Action Gateway (16,000+ tools). Works with Claude Code, Codex CLI, OpenCode. Paired with prepaid Inference and Agents Balance.

DigitalOcean Agent Droplets: harness + inference + 16k tools in one monthly plan from $50/$200

Key Takeaways

Read full story

Cursor lists GLM 5.3 / Flash natively: 1M context, Other Models pool, from $1.4 / $0.15 per MTok

Cursor’s official Models & Pricing and dedicated docs now list Z.ai GLM 5.3 and GLM 5.3 Flash as addable third-party models: 1M context, Low/High/Max reasoning (High default), Other Models pool billing. Table rates: GLM 5.3 $1.4/$0.26/$4.4, Flash $0.15/$0.029/$0.5 per MTok—same as 5.2, no long-context surcharge. Enable in Settings → Models (not the BYOK custom-endpoint path).

Key Takeaways

Read full story

Freebuff launches $8/mo Starter: ad-supported high-usage coding plan centered on DeepSeek V4.1 Flash / GLM Flash

@jahooma (Freebuff/Codebuff) announced an $8/mo Starter tier: the post claims ~15 hours/day of DeepSeek V4.1 Flash with unlimited messages because ads subsidize usage. freebuff.com/plans currently lists Starter at $8/mo with about 10 hrs/day DeepSeek V4.1 Flash or 30 hrs/day GLM 5.3 Flash across Web, Desktop, and CLI.

Freebuff launches $8/mo Starter: ad-supported high-usage coding plan centered on DeepSeek V4.1 Flash / GLM Flash

Key Takeaways

  • Founder announced $8/mo Starter: ad-supported, claiming ~15h/day DeepSeek V4.1 Flash with unlimited messages.
  • Plans page lists Starter at $8/mo with ~10h/day DeepSeek V4.1 Flash or ~30h/day GLM 5.3 Flash.
  • Works across Web, Desktop, and CLI as a low-cost alternative tier to Claude Code / Cursor / Codex.
Read full story
Linked Models & Agents:

Bolt Forge launches on bolt.new: open-weight coding agent free with up to 50x usage until Oct 14

bolt.new introduced Bolt Forge, an open-weight coding agent now live in the bolt.new model picker. Free until Oct 14 with up to ~50x usage and zero usage charges; lineup includes GLM 5.3 / GLM 5.3 Flash, Kimi K3, and DeepSeek v4 Pro. Opt-in builds help train a trillion-parameter-class model with Arcee; also announced $9/mo Bolt Lite (Forge included; join by Oct 14 to lock $9). Partners include Arcee, Microsoft, Vercel, Fireworks, and DigitalOcean.

Key Takeaways

  • Bolt Forge is live in bolt.new’s model picker as an open-weight coding agent.
  • Free through Oct 14 with up to ~50x usage and zero usage charges; GLM 5.3, Kimi, DeepSeek included.
  • Also ships $9/mo Bolt Lite with Forge; opt-in builds train a trillion-param model with Arcee.
Read full story

LMArena: Fable 5.1 quality-vs-price head-to-head vs Opus 5, GPT-5.6 and more

Arena.ai (@arena) highlights @petergostev’s head-to-head: Anthropic Claude Fable 5.1 vs Fable 5, Opus 5, GPT-5.6, Kimi K3, GLM 5.3, Qwen-3.8, Grok-4.6, and DeepSeek across coding, 3D, SVG, research, and data-viz—with generation costs from cents to $65+—so developers can weigh quality vs price.

Key Takeaways

  • Arena frames a quality-vs-price bake-off of Fable 5.1 against frontier peers.
  • Peers include Opus 5, GPT-5.6, Kimi K3, GLM 5.3, Qwen-3.8, Grok-4.6, and DeepSeek.
  • Per-generation costs span cents to $65+, useful for model selection and budgeting.
Read full story
ADSponsored

Composio Evaluates 5 Open-Weight Models on 30 Multi-Step Agent Tasks: Flash Models Lead in ROI

Composio benchmarked 5 open-weight models across 30 multi-step agent tasks, finding GLM-5.3 Flash and DeepSeek-V4 Flash delivered the highest cost efficiency at a fraction of full-model pricing.

Key Takeaways

  • Flash-class models achieve near parity with full-scale weights at approximately 75% lower inference cost;
  • Multi-application tool orchestration remains the primary failure mode across all open-source models;
  • Provides empirical cost-per-success metrics to guide architectural selection for enterprise agent deployments.
Read full story