
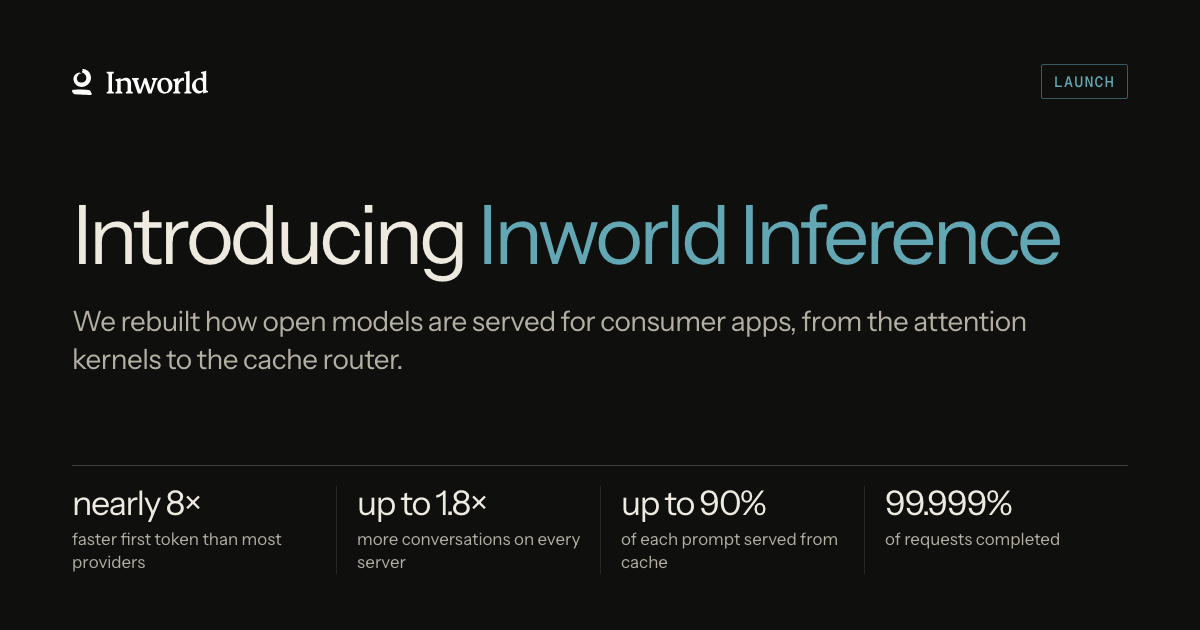
On 2026-10-14 Inworld AI opened Inworld Inference to every developer, positioning it as an inference service for consumer apps (companions, tutors, voice, interactive fiction). Instead of listing thousands of models it builds a per-model serving stack for open models such as Gemma 4, GLM 5.3 Flash, DeepSeek and MiMo: draft-and-verify (speculative) decoding, a rewritten split-KV verify attention kernel, KV-aware routing and eval-gated low precision. Vendor-reported: Gemma 4 26B p95 first token of 0.31 s, 7.8x faster than the median OpenRouter provider; up to 90% of prompts from cache; 99.999% success over 20M+ GLM 5.3 Flash requests in 30 days. The API is OpenAI-compatible with Flex/Default/Priority/Fast tiers per request.
Key Takeaways
- ✓Gemma 4 26B first token: p50 0.17 s / p95 0.31 s, 3.6x / 7.8x faster than the median OpenRouter provider (blog, vendor-reported snapshot, not a matched workload)
- ✓Pricing: Gemma 4 26B at $0.07 input, $0.035 cached, $0.34 output per 1M tokens, nearly 40% below the median no-training provider
- ✓Rewritten verify attention: 3.4–7.5x faster per layer, attention share of a decode step 27.5%→16.5%, p50 TTFT 154→117 ms at equal eval scores
- ✓KV-aware routing: GLM 5.3 Flash cache hits 25%→47%, DeepSeek V4.1 Flash 11%→33%; cached MiMo 2.6 Pro input costs 99% less
- ✓Reliability: 98 failures across 20M+ GLM 5.3 Flash requests in 30 days (~4.8 per million); per-request
service_tierof Flex/Default/Priority/Fast
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Inworld AI opened Inworld Inference to all developers on 2026-10-14 as an inference API built for consumer AI rather than enterprise or coding workloads. Consumer turns resend the whole conversation (median prompts are 13–36x the reply length across apps Inworld serves), fan out into ~20 calls per turn, and must cost almost nothing. Inworld therefore builds a dedicated serving stack per open model (Gemma 4, GLM 5.3 Flash, DeepSeek V4.1 Flash, MiMo 2.6 Pro): draft-and-verify speculative decoding, a verify step moved onto a split-KV attention kernel (3.4–7.5x faster per layer on Gemma 4 26B; p50 TTFT 154→117 ms), a KV-aware router that scores replicas on prefix overlap and load (GLM 5.3 Flash cache hits 25%→47%), and NVFP4 MLP weights with FP8 attention/KV, gated on MATH, MMLU-Pro and GSM8K. Vendor-reported results: Gemma 4 26B p95 first token 0.31 s vs 2.42 s for the median OpenRouter provider, $0.07/$0.34 per 1M input/output tokens, and 98 failures across 20M+ GLM 5.3 Flash requests in 30 days. The API is OpenAI-compatible (base URL https://api.inworld.ai/v1) with per-request service tiers (Flex, Default, Priority, Fast), TTFT-based model failover, CEL routing conditions and A/B splits, plus dedicated deployments for bring-your-own or post-trained models.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.