Artificial Analysis Launches Decision Index v2: New Calibration-Aware Decision Score, 45% Private Data, Drex Max v1.1 Narrowly Leads Decision Models at 73
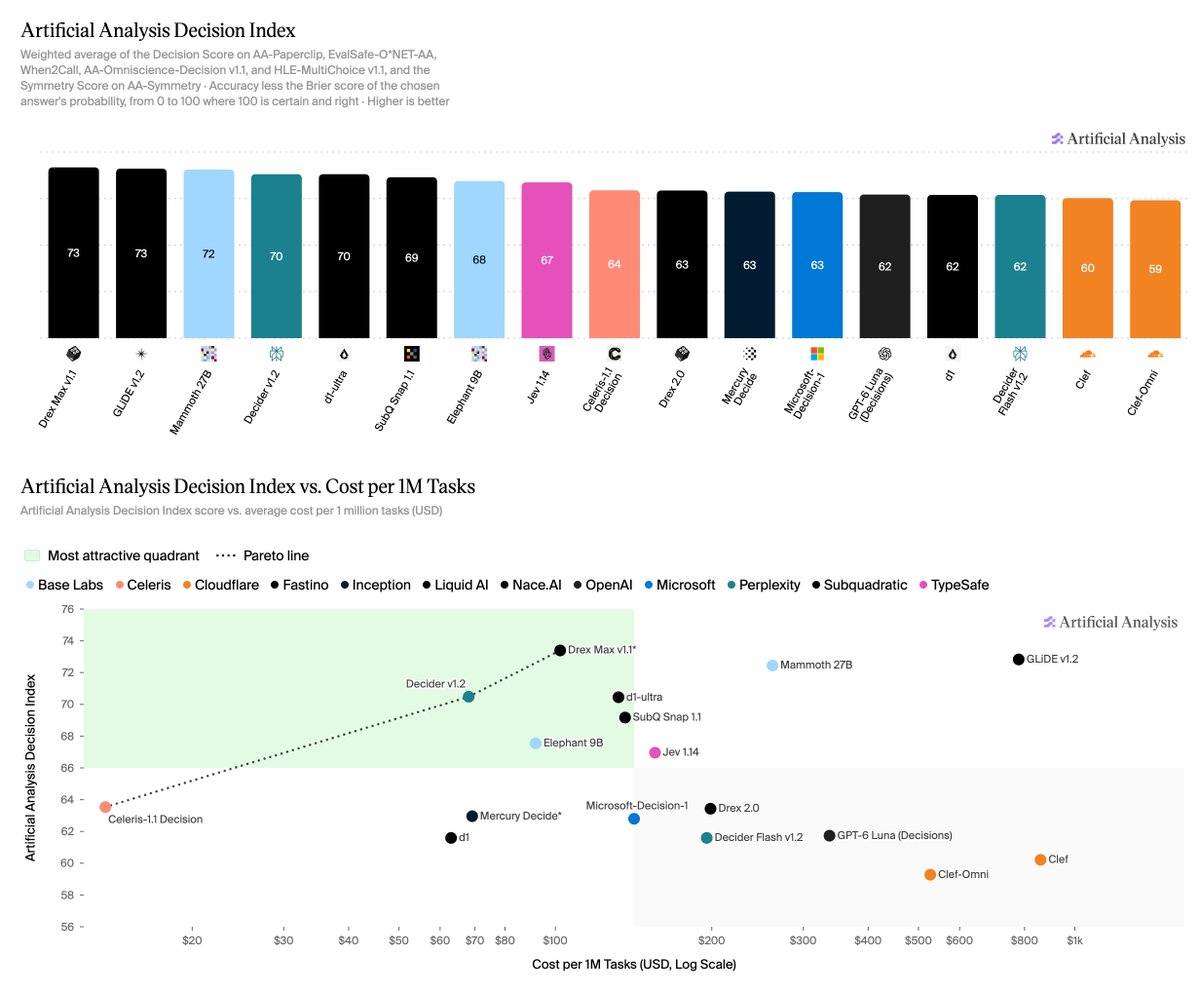
On November 8 (morning of November 9 in Singapore), independent evaluator Artificial Analysis released version 2 of its Decision Index for decision models. The headline metric is now a Decision Score that rewards both correct answers and well-calibrated confidence, the private-data share rises from 25% in v1 to 45%, and two new evaluations are added: AA-Paperclip with 1,500 private documents and AA-Symmetry for answer consistency. Among decision models, Nace AI's Drex Max v1.1 and Fastino Labs' GLiDE v1.2 both score 73, with Drex Max narrowly ahead, and Base Labs' Mammoth 27B scores 72. General LLMs score higher, with Claude Haiku 5.5 (Max) at 77 and GPT-6 Luna (Max) at 76, but cost $6,240 and $1,530 per 1M tasks versus $102 for Drex Max.
Key Takeaways
- New metric (official leaderboard): per-question score = 50 x (1 + c - (p - c)^2), equal overall to 50 x (1 + accuracy - Brier score); right answers always score above 50 and wrong ones below 50, with confidence spreading scores within each half
- New weights: AA-Paperclip 30%, AA-Symmetry 15%, EvalSafe-O*NET-AA 15%, AA-Omniscience-Decision v1.1 15%, HLE-MultiChoice v1.1 15%, NVIDIA When2Call 10% (down from 25%); the saturated WildGuardTest was removed
- Top decision models (vendor-run evaluation): Drex Max v1.1 73, GLiDE v1.2 73, Mammoth 27B 72; general LLMs Claude Haiku 5.5 (Max) 77 and GPT-6 Luna (Max) 76
- Cost gap above 60x: Celeris-1.1 Decision $14 per 1M tasks, Drex Max v1.1 $102, Clef $859; GLiDE v1.2 bills a document's input for every question and costs $780, about 8x Drex Max
- Speed: Celeris-1.1 Decision takes 56 ms per task and Elephant 9B 70 ms, versus 11.34 s for GPT-6 Luna (Max) and 32.65 s for Claude Haiku 5.5 (Max)
Linked Models & Agents:
⚡ Drex Max V1 1⚡ Glide V1 2⚡ Mammoth 27b⚡ Elephant 9b⚡ Celeris 1.1 Decision⚡ Claude Haiku 5.5⚡ GPT-6 Luna🌐 Artificial Analysis🌐 Nace AI🌐 Fastino Labs🌐 Base Labs🌐 Anthropic🌐 OpenAI🌐 NVIDIA🌐 TypeSafe