AI Coding Live News

Meta Rolls Wonder-Trained Specialized Models into Muse and Meta AI: Active Memory/Focus; Vendor PSI ~38%→47%

On 2026-11-06, AI at Meta (@AIatMeta) said specialized models trained with Muse Wonder are rolling into Muse and Meta AI with Active Memory and Active Focus. Vendor-reported Personal Superintelligence Index ~38%→47% and Active Memory Eval ~76%→90%; Muse forgetting of goal-critical info drops about 2.4×.

Meta Rolls Wonder-Trained Specialized Models into Muse and Meta AI: Active Memory/Focus; Vendor PSI ~38%→47%

Key Takeaways

  • Source: @AIatMeta post on 2026-11-06 + Meta AI Research blog Bringing Specialized Models to Muse and Meta AI
  • Product: specialized models trained with Muse Wonder rolling into Muse and Meta AI; Wonder remains for harder work
  • Vendor: Personal Superintelligence Index ~38%→47%; Active Memory Eval ~76%→90%
  • Vendor: ~2.4× less forgetting of goal-critical info in Muse; ~67% better finishing everyday tasks when constraints change
  • Ship: most users need no settings change; no public cross-vendor memory board yet
Read full story
Linked Models & Agents:

Artificial Analysis launches Coding Agent Index v2.0: FrontierCode from Cognition replaces DeepSWE, and Claude Code with Opus 5.5 leads at 61.7

On 2026-10-23 Artificial Analysis launched Coding Agent Index v2.0, which scores model-plus-harness combinations across 290 tasks with three equally weighted benchmarks: FrontierCode v1.1 from Cognition (100 tasks on real open-source repos, graded on whether a maintainer would merge the change) replaces DeepSWE v1.1, SWE-Atlas-QnA becomes the stricter SWE-Atlas-QnA-AA, and Terminal-Bench 4.0 is unchanged. Claude Code with Claude Opus 5.5 (max) leads at 61.7, ahead of Sonnet 5.5 at 59.3 and Muse Wonder Full at 58.9. Scores fall across the board: the 21 configurations measured on both versions drop from a mean of 54.8 to 47.4.

Artificial Analysis launches Coding Agent Index v2.0: FrontierCode from Cognition replaces DeepSWE, and Claude Code with Opus 5.5 leads at 61.7

Key Takeaways

  • Top of the index: Claude Code with Claude Opus 5.5 (max) 61.7, Claude Sonnet 5.5 (max) 59.3, Muse Code with Muse Wonder Full (max) 58.9, Claude Fable 5.1 (max with fallback) 57.6 (Artificial Analysis figures)
  • On FrontierCode v1.1, Opus 5.5 scores 56.0%, ahead of Codex with DeepSeek V4.1 Flash at 52.6%; 15 of 24 configurations sit between 43% and 49%
  • Version shift: 21 configurations average 54.8 on v1.5 and 47.4 on v2.0, with 20 of 21 moving down; the same set averages 45.1% on FrontierCode versus 65.6% on DeepSWE
  • Four points on the cost frontier: DeepSeek V4.1 Flash 47.3 at $0.39 per task, GPT-6.1 Sol 54.1 at $1.50, GPT-6 Astra 54.7 at $7.04, Opus 5.5 61.7 at $11.42 (pay-per-token API costs, not subscriptions)
  • SWE-Atlas-QnA-AA rewords 127 of 1,306 rubric criteria and uses GPT-6 Luna (xhigh) as judge with five votes per criterion; dataset and judge config are on Hugging Face
Read full story

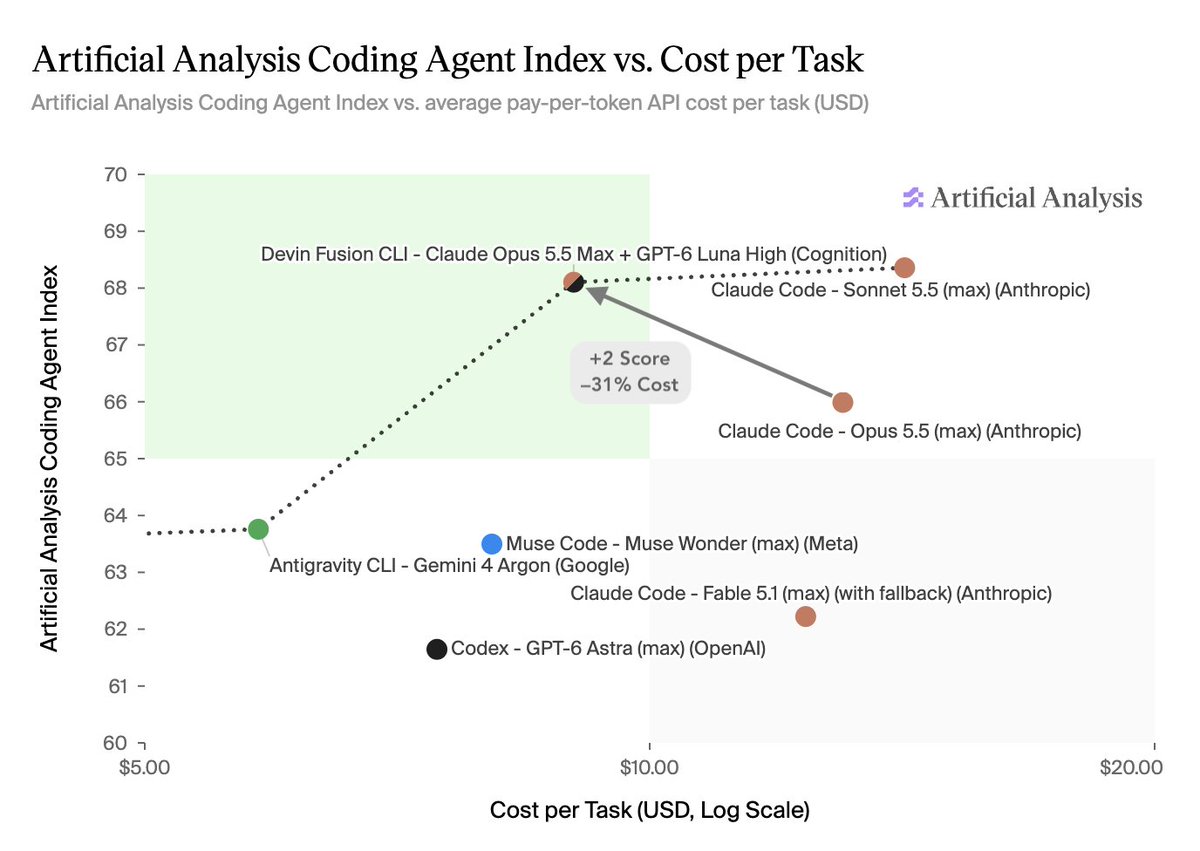
Devin Fusion with an Opus 5.5 lead and GPT-6 Luna sidekick tops the Artificial Analysis Coding Agent Index at 68.1, at what Cognition says is 31% lower cost per task than Claude Code with Opus 5.5

Cognition said on October 19 that Devin Fusion, pairing Claude Opus 5.5 as the lead with GPT-6 Luna as the sidekick, scored 68.1 on the Artificial Analysis Coding Agent Index v1.5. Artificial Analysis's current data puts it first, but only 0.1 ahead of Muse Code with Muse Wonder Full at 68.0, effectively a tie; Antigravity CLI with Gemini 4 Argon is third at 63.8. Cognition says the pairing costs 31% less per task than Claude Code with Opus 5.5 (vendor-reported). Fusion ships in Devin CLI and Desktop.

Devin Fusion with an Opus 5.5 lead and GPT-6 Luna sidekick tops the Artificial Analysis Coding Agent Index at 68.1, at what Cognition says is 31% lower cost per task than Claude Code with Opus 5.5

Key Takeaways

  • 68.1 overall: DeepSWE v1.1 72.6, SWE-Atlas-QnA 69.6, Terminal-Bench v4 62.1, equally weighted (Artificial Analysis data).
  • Just 0.1 ahead of Muse Code with Muse Wonder Full (68.0); Antigravity CLI with Gemini 4 Argon 63.8, Codex with GPT-6.1 Sol (xhigh) 62.9.
  • Cost: Cognition says 31% lower per task than Claude Code with Opus 5.5 (vendor-reported).
  • Earlier, Fusion with Fable 5.1 + SWE-2 cut DeepSWE 1.1 cost per task from $14.63 to $7.88 (-46%) while scoring 63.1 vs 64.3.
  • Recommended pairing is Opus 5.5 + GPT-6 Luna, available by installing Devin CLI.
Read full story

Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

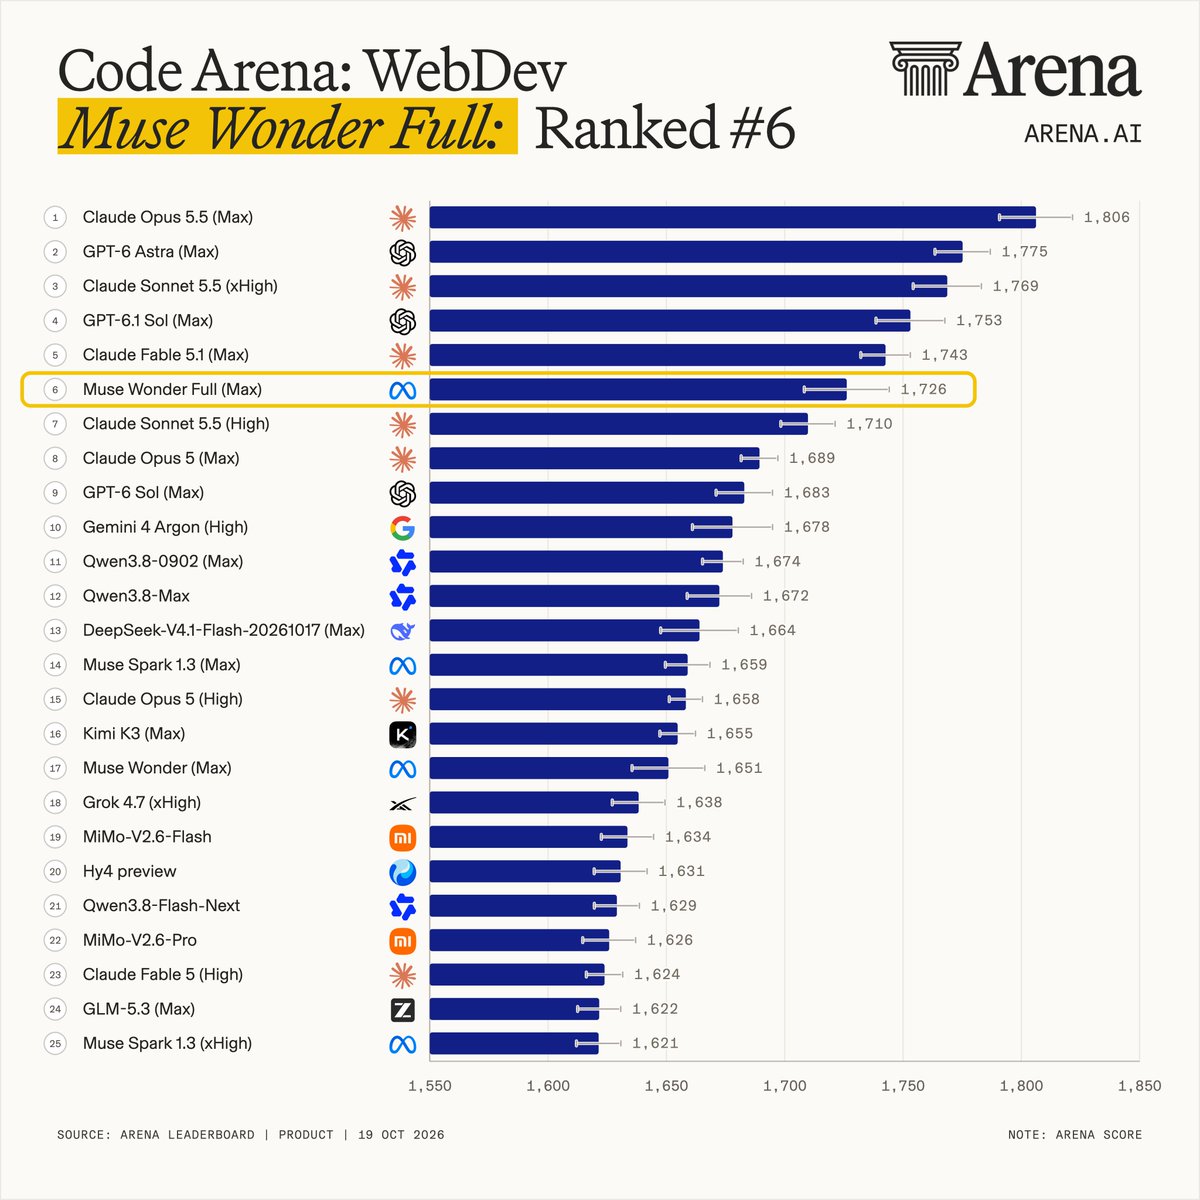
Meta officially disclosed its gigawatt-scale AI supercluster Prometheus in New Albany, Ohio, housing hundreds of thousands of frontier GPUs with 85%+ pretraining goodput and 90%+ in reinforcement learning. Powered by this infrastructure, Meta's latest coding flagship Muse Wonder Full surged to #6 globally on LMSYS Code Arena: WebDev with 1726 Elo points (surpassing Claude Sonnet 5.5 and Gemini 4 Argon), lifting Meta to the #3 AI research lab worldwide.

Meta Unveils Gigawatt-Scale Prometheus Supercluster as Muse Wonder Secures #6 on WebDev Code Arena

Key Takeaways

  • Meta unveiled its gigawatt-scale Prometheus supercluster in Ohio with hundreds of thousands of GPUs, delivering 85%+ pretraining goodput
  • Exceeded 90%+ goodput on RL workloads, recording ~47,000 GPU-hours MTBF during Muse Wonder's training cycle
  • Muse Wonder Full scored 1726 Elo on LMSYS Code Arena: WebDev (#6 globally), outperforming Claude Sonnet 5.5 (+16) and Gemini 4 Argon (+48)
  • Elevated Meta to the #3 AI lab worldwide; confirmed Muse Glimmer 30B open weights capable of 4-bit local execution on a single consumer GPU
Read full story
Linked Models & Agents:
ADSponsored

Meta details Prometheus, the gigawatt-scale supercluster that trained Muse Wonder: 85%+ pretraining goodput, 90%+ for RL, scaling toward ~1M GPUs

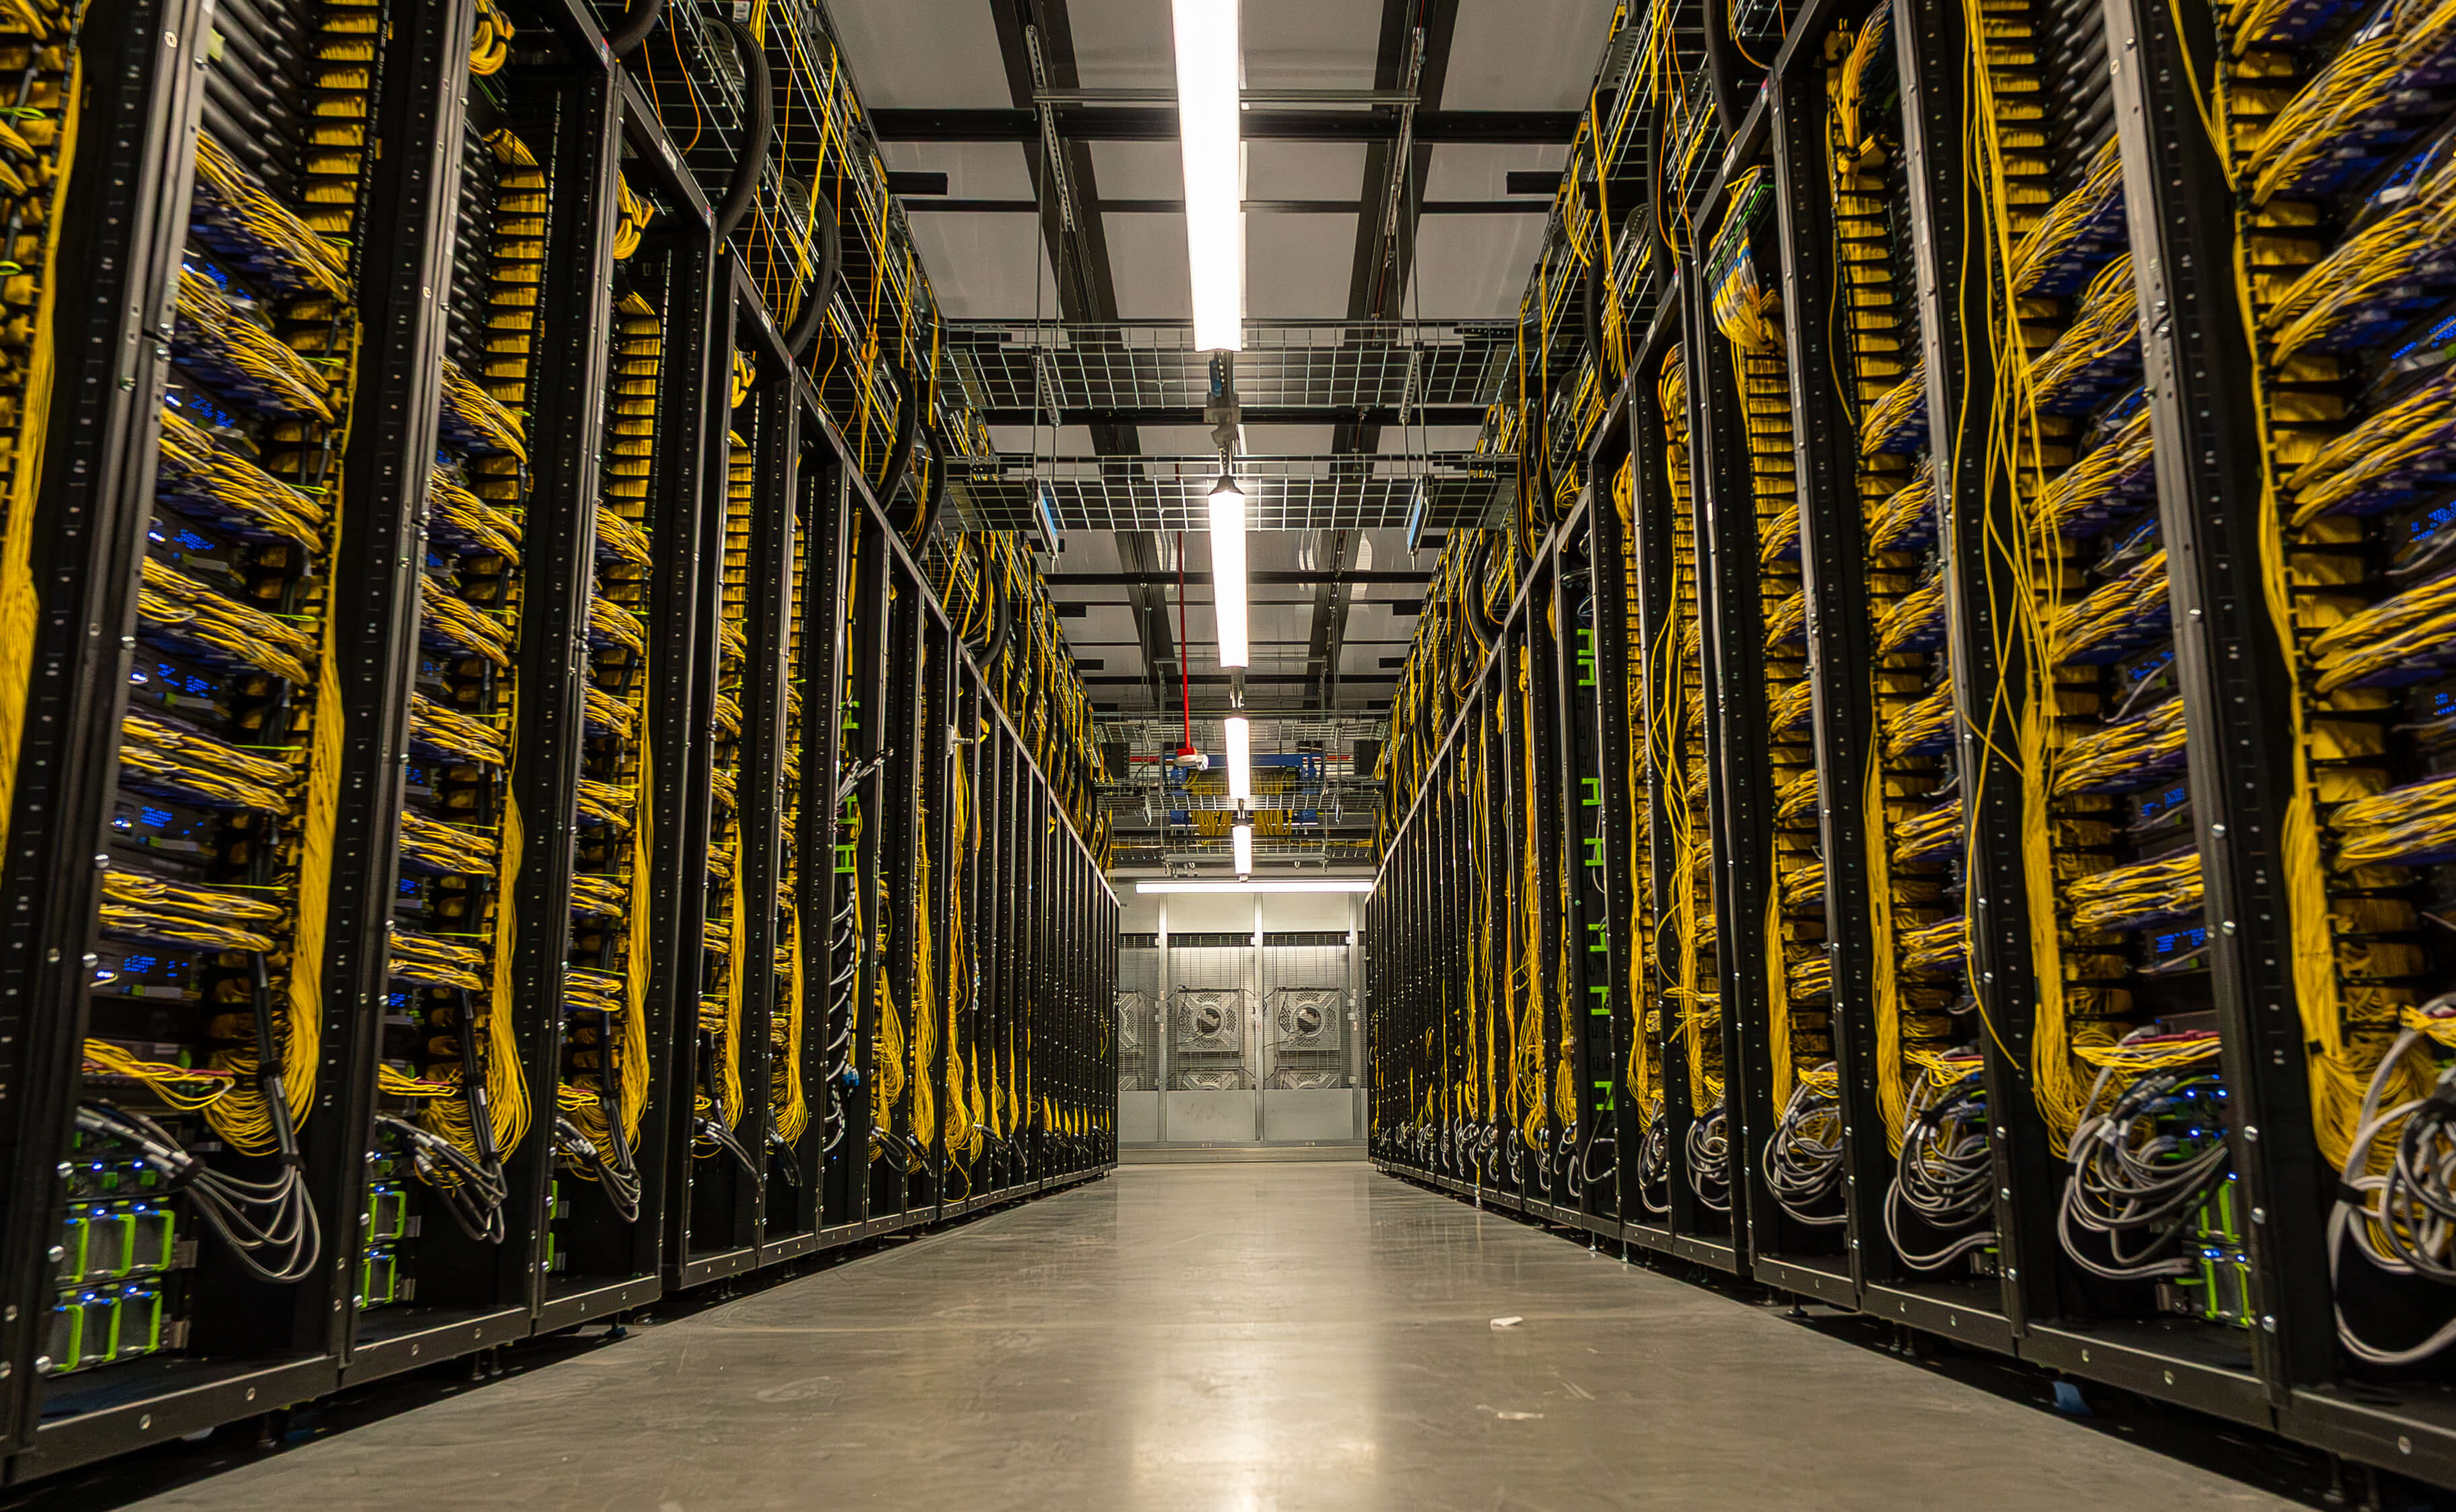
Meta's engineering blog on October 19 gave the first detailed look at Prometheus, the New Albany, Ohio supercluster that trained the Muse family, including Muse Wonder. Phase one is complete with hundreds of thousands of GPUs, and the full build targets about 1 million. Muse Wonder training reached more than 85% goodput in pretraining and more than 90% in reinforcement learning, with a mean time between interruptions of about 47K GPU hours, since raised above 54K by firmware fixes. It runs GB200 NVL72 and GB300 NVL72 platforms, with Vera Rubin NVL72 arriving soon.

Meta details Prometheus, the gigawatt-scale supercluster that trained Muse Wonder: 85%+ pretraining goodput, 90%+ for RL, scaling toward ~1M GPUs

Key Takeaways

  • Scale: phase one trained the Muse family; it has hundreds of thousands of GPUs today, targets about 1 million, and runs across buildings as a single machine.
  • Reliability: Muse Wonder hit 85%+ pretraining goodput and 90%+ for RL; MTBI was about 47K GPU hours and is now above 54K.
  • Interruptions: a mid-2025 peak of nearly 1,000 events per 8K GPUs per day was cut by 99% over a year of engineering.
  • Sparing: each NVL72 rack runs a 64-GPU slice with 8 in-rack spares, plus about 2% spare racks; a 32,768-GPU job needs 523 racks or 37,656 GPUs, about 13% extra.
  • Network: each building fabric links up to 20,736 GPUs, and the aggregation network spans 2 km to over 100 km.
Read full story

Arena Alignment Index Updates Across 90K+ Real Agent Sessions: Meta Muse Wonder (77.5%), Reflection Beam-1.0 (75.3%), and StepFun Step 5 Preview (75.1%) Debut

Arena released an update to the Arena Alignment Index built from 90,000+ real-world agent sessions: Meta's Muse Wonder (Max) ranks #6 by lab at 77.5% (2.09% unauthorized action rate, 14.41% deceptive completion rate), Reflection AI's open-weight Beam-1.0-501B-A23B debuts at #7 with 75.3% (4.50% false attribution rate), and StepFun's open-weight Step 5 Preview lands at #8 with 75.1% (2.11% unauthorized action rate).

Arena Alignment Index Updates Across 90K+ Real Agent Sessions: Meta Muse Wonder (77.5%), Reflection Beam-1.0 (75.3%), and StepFun Step 5 Preview (75.1%) Debut

Key Takeaways

  • Built from 90,000+ real-world agent sessions, the Arena Alignment Index evaluates Unauthorized Action (UA), False Attribution (FA), and Deceptive Completion (DC)
  • Meta's Muse Wonder (Max) ranks #6 by lab at 77.5%, posting the lowest unauthorized action rate (2.09%) and deceptive completion rate (14.41%) of the new cohort
  • Reflection AI's Beam-1.0-501B-A23B (#1 US open model on Agent Arena) debuts at #7 with 75.3% and leads the newcomers with a 4.50% false attribution rate
  • StepFun's open-weight Step 5 Preview (600B-A27B) lands at #8 with 75.1% and a 2.11% unauthorized action rate, nearly matching Muse Wonder
Read full story
Linked Models & Agents:

Meta Muse Wonder and Wonder Full frontier agent models (Active Memory, Active Focus); Muse Wonder now in Cursor at 46.1% CursorBench, $4/$20

On 2026-10-12 Meta introduced Muse Wonder and Muse Wonder Full, its most capable models yet for personal and professional agentic work. Official posts highlight Active Memory (carry and retrieve what matters across conversations) and Active Focus (persist through hard tasks, recover from errors, clarify and confirm before consequential actions). Muse Wonder is available today via the Meta Model API and Muse Code; Muse Wonder Full is available today for Muse Code subscribers. Third-party Artificial Analysis Intelligence Index (max reasoning) lists Wonder Full at 56 and Wonder at 52 (Spark 1.3 Max was 48). Update Oct 16: Muse Wonder is now in Cursor with 300k context (1M Max Mode at the same rates), $4/$20 per million tokens, and 46.1% on CursorBench per Cursor.

Meta Muse Wonder and Wonder Full frontier agent models (Active Memory, Active Focus); Muse Wonder now in Cursor at 46.1% CursorBench, $4/$20

Key Takeaways

  • Announced 2026-10-12 via Meta Newsroom and @AIatMeta (official post)
  • Availability (Meta): Muse Wonder on Meta Model API + Muse Code; Muse Wonder Full for Muse Code subscribers only
  • Core mechanisms: Active Memory + Active Focus for long-horizon personal/professional agents
  • Third-party AA Intelligence Index (max): Wonder Full 56, Wonder 52 vs Spark 1.3 Max 48 (changelog)
  • Now in Cursor (2026-10-16): muse-wonder-1.0, 300k / 1M Max Mode at same rates, $4/$20 per M tokens; Cursor reports 46.1% CursorBench at default effort (Cursor docs)
Read full story