
AI Coding Live News

GitHub Agentic Workflows is generally available: write automation in Markdown, compile it to Actions YAML, run Copilot or your own coding agent, now with ARC self-hosting and micro-VM isolation

At Universe 2026 on Oct 28, GitHub made GitHub Agentic Workflows, an open source GitHub Next project, generally available on GitHub Free, Team and Enterprise. Developers describe tasks such as issue triage, CI failure analysis, documentation updates and test writing in natural-language Markdown, and gh aw compiles them into standard Actions YAML run by Copilot or a coding agent of their choice. GA adds self-hosted ARC runners with Docker-in-Docker, a non-experimental gh aw forecast cost estimate, per-workflow model providers and model routing, and Cloud Hypervisor or NVX micro-VM isolation.
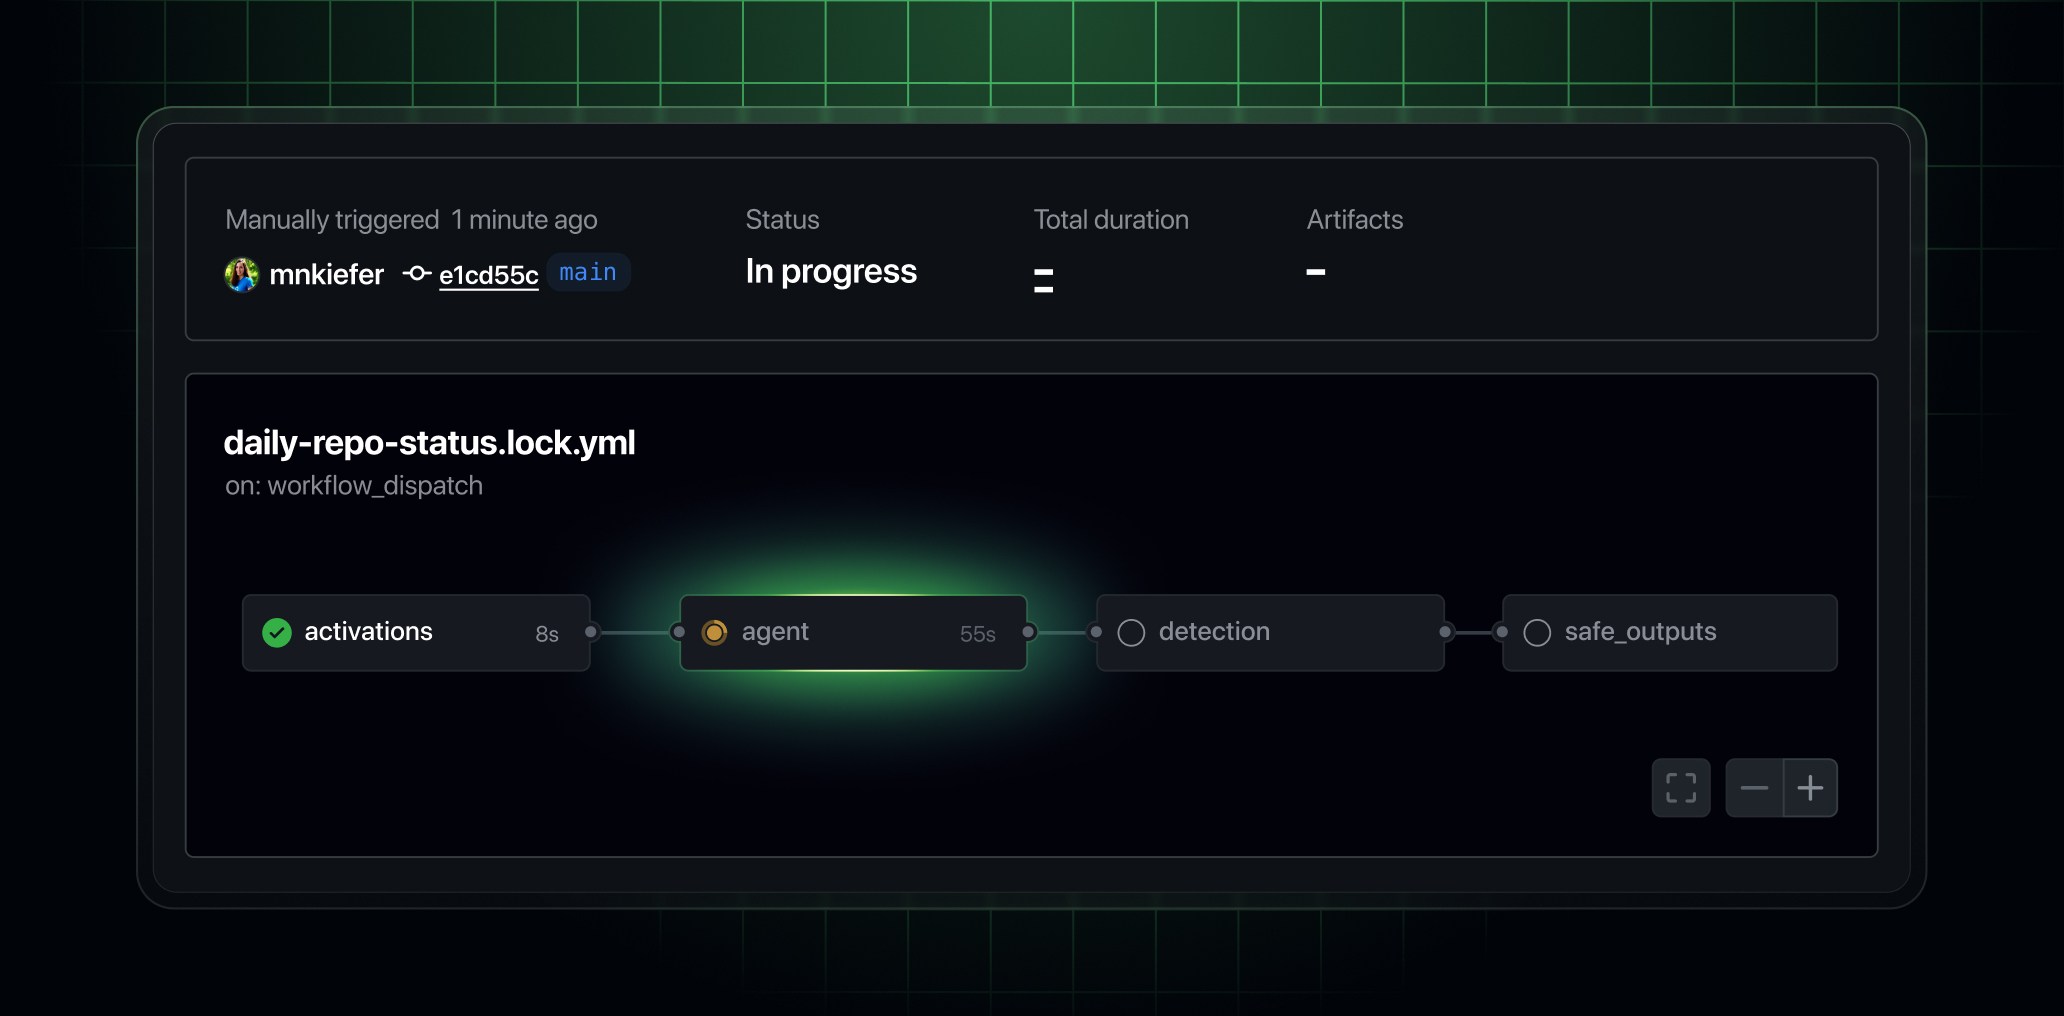
GitHub Agentic Workflows is generally available: write automation in Markdown, compile it to Actions YAML, run Copilot or your own coding agent, now with ARC self-hosting and micro-VM isolation

Key Takeaways

  • Availability: GitHub Free, Team and Enterprise on github.com; using the default Copilot CLI engine requires a Copilot license
  • How it works: requirements in Markdown, compiled to standard Actions YAML that reuses existing runner groups and policies; run with Copilot or your own coding agent
  • Safe defaults: read-only permissions, a sandboxed container behind the Agent Workflow Firewall, safe-outputs validation, and a threat detection job before changes are applied
  • New at GA: self-hosted ARC runners with Docker-in-Docker, gh aw forecast out of experimental (with threat detection credits and monthly ranges), per-workflow model providers, model routing, micro-VM isolation and cross-repo enclaves
  • Customer story (Accenture's figures): one lead saved about 29 hours a week, AI authors 91% of the team's commits, and production errors fell from about 11,000 a day to under 1,000
Read full story

Earendil ships Pi 1.0: stable minimal agent harness with Codemode+MCP; ~111.8k★ / HN 1645 pts

On 2026-10-01 Earendil shipped Pi 1.0 (MIT): a hardened minimal coding-agent harness. Built-ins: Codemode (QuickJS sandbox for model-written JS calling tools / Jev / image models) + MCP, virtual-model routing, deferred tools, Anthropic cache warming, mid-conversation system edits. At ingest: 111793★; HN 1645 pts / 573 comments. Experimental Pi Durable shipped the same day.

Key Takeaways

  • Official post 2026-10-01; GitHub v1.0.0 at 2026-10-01T19:20:55Z; MIT
  • At ingest: 111793★; HN Pi 1.0 thread 1645 pts / 573 comments
  • 1.0: Codemode+MCP, virtual models, deferred tools, Anthropic cache warming, mid-convo system messages, fullscreen TUI; changelog ~5300→3300 prompt tokens (−40%) for GPT-5.6 with defaults+codemode
  • Not NVIDIA SoL-Pi (already in D1) — this is Earendil’s Pi harness
  • Install: curl https://pi.dev/install.sh | sh or npm @earendil-works/pi-coding-agent; docs pi.dev
Read full story
Linked Models & Agents:

Ollama 0.35.0: Decision Models via /v1/systemone (Jev); Nimble & Tev1 return choices, probabilities, confidence

Ollama shipped v0.35.0 on 2026-09-28 (GitHub prerelease): Decision Models via TypeSafe’s Jev API at /v1/systemone. Instead of free text, models answer choice/noul/score questions with options, probabilities, and confidence—for ticket triage, model routing, and classification. First models: Nimble (Bespoke Labs) and Tev1 (Together AI). ~7 commits / 66 files vs v0.34.4; Settings no longer blocks on discovery; macOS update menu and stalled MLX downloads fixed.

Ollama 0.35.0: Decision Models via /v1/systemone (Jev); Nimble & Tev1 return choices, probabilities, confidence

Key Takeaways

  • v0.35.0 (prerelease) adds Decision Models at POST /v1/systemone (TypeSafe Jev)
  • Question types: choice (with probabilities), noul, score — not free-text generation
  • First models: Nimble (Bespoke Labs) and Tev1 (Together AI) on ollama.com/library
  • ~7 commits / 66 files vs v0.34.4; Settings/macOS update/MLX download fixes
Read full story

Mastra @mastra/core 1.70.0: ModelSelectionProcessor routes cheap vs strong models; durable streams gain closeOnSuspend

Mastra published @mastra/[email protected] on 2026-09-24 with ModelSelectionProcessor for classifier-backed per-request model routing (#24865), closeOnSuspend on durable agent streams so AG-UI-style loops can finish on tool suspend, plus createClassifierScorer(), optional tool titles, and trace aggregate dimension/measure helpers with tag predicates. Docs warn routing is not always cheaper because models do not share prompt caches.

Key Takeaways

  • ModelSelectionProcessor routes simple vs hard requests (#24865); scope: 'first-step' optional
  • Durable closeOnSuspend: true ends streams at tool suspend (#24894)
  • createClassifierScorer() maps Classifier questions to 0–1 scores (#24792)
  • Trace aggregate descriptors + tag predicates for advanced queries
  • Upgrade: npm i @mastra/[email protected]; see CHANGELOG + processors docs
Read full story
Linked Models & Agents:
ADSponsored

OpenSquilla open-sources a microkernel agent with local four-tier model routing

@DanKornas highlighted TokenRhythm/opensquilla, a token-efficient microkernel AI agent for builders. SquillaRouter scores each turn locally on length, language, code, keywords, and semantic embeddings, then routes across four tiers to the cheapest capable model; the registry targets 20+ LLM backends with primary-plus-fallback. Fifteen bundled skills load on demand, and the agent can act as an MCP client or server. Local Markdown notes add SQLite full-text search and sqlite-vec semantic recall, with three sandbox policy tiers plus human-in-the-loop approvals for sensitive tools. Apache 2.0.

Key Takeaways

  • Local four-tier routing picks the cheapest capable model instead of always using the top tier.
  • Skills + MCP: 15 on-demand skills; agent can be MCP client and server.
  • Apache 2.0; Markdown/SQLite memory with three sandbox tiers and human approvals.
Read full story
Linked Models & Agents:

minirouter.sh ships minirouter/auto task routing plus Google/GitHub/passkey login

Zhe (@iamzhe) shipped a minirouter.sh update: minirouter/auto for task-based model routing, Google/GitHub/passkey login, and a fix for Codex users with Qwen models.

Key Takeaways

  • New option: minirouter/auto for task-based model routing that improves over time.
  • Login: Google, GitHub, and passkey.
  • Fix: bug affecting Codex users with Qwen models.
Read full story
Linked Models & Agents:

Cline: GLM-5.3 max outperforms GPT-5.6 Sol max on Terminal-Bench 4.0

Cline reported that Zhipu GLM-5.3 at max effort outperforms OpenAI GPT-5.6 Sol at max effort on the newly released Terminal-Bench 4.0. The post quotes Zhipu lead Zixuan Li's announcement that the benchmark itself is iterating fast enough to keep up with model releases. Cline already hosts glm-5.3 in-product: install with npm i -g cline, run /model, and select glm-5.3. ClinePass is offered as roughly 5x discounted access versus calling the direct API, continuing Cline's push to make open-weight agent models the default path rather than a hobby sidecar. For teams running terminal-native coding agents, the result matters because Terminal-Bench measures long-horizon shell work rather than single-file completion. An open-weight win against Sol on that surface changes both model routing and budget planning, especially if ClinePass pricing holds under production traffic.

Key Takeaways

  • GLM-5.3 max beats GPT-5.6 Sol max on Terminal-Bench 4.0, an open-weight challenge to a closed flagship.
  • Cline already serves glm-5.3 in-product via npm i -g cline and /model.
  • ClinePass offers about 5x discounted access versus the direct API for this class of open weights.
Read full story

Replit Introduces Intelligent Model Routing: Automatic Model Selection Cuts Agent Costs by Up to 65%

Replit launched Intelligent Model Routing for Replit Agent, automatically picking the best model per task with an auto toggle, cutting development costs by up to 65% while maintaining output quality.

Key Takeaways

  • Abstracts model selection into infrastructure, eliminating tedious manual switching between models;
  • Delivers matched output quality at up to 65% lower total expenditure compared to previous Max Mode;
  • Enterprise controls allow administrators to restrict routing within security-approved model whitelists.
Read full story
Linked Models & Agents:

Cloudflare AI Gateway Unified Billing Offers 50% Off GPT-5.6 Sol Inference for One Month

Cloudflare introduced a 50% promotional discount for OpenAI's GPT-5.6 Sol via AI Gateway unified billing, combining edge caching, observability, and cost-effective multi-model routing.

Key Takeaways

  • Gateway competition expands from observability and retries into direct API rate subsidies on flagship models;
  • Unified billing invoice streamlines multi-vendor LLM management across hosted and proxied endpoints;
  • Edge caching and smart routing reduce time-to-first-token and operational costs for production apps.
Read full story
Linked Models & Agents:

Cursor launches Cursor Router: Task-aware model routing cuts coding costs by 60%

Cursor launched Cursor Router, an intelligent model dispatch engine. In Auto mode, users configure goals for Intelligence, Balance, or Cost. The router sends complex tasks to frontier models and routine edits to efficient ones, cutting cost per commit by ~60% with zero quality degradation.

Key Takeaways

  • Dynamically routes tasks based on prompt complexity between frontier and efficient models.
  • Early enterprise tests show equivalent quality to always-on Opus 4.8 at 60% lower token spend.
  • Admins can configure team-level model permissions and default routing thresholds.
Read full story
ADSponsored