AI Coding Live News

Cartesia launches Managed Agents voice agent platform: #1 of 30 on Speech Agent Arena, $0.03 per minute at launch

Voice model company Cartesia launched Managed Agents on Oct 29, an end-to-end voice agent platform for enterprise phone calls that tunes its own speech-to-text and text-to-speech models together with the agent harness, and bundles telephony, knowledge bases, tool calls and outbound batches. Cartesia says it ranks #1 on Artificial Analysis's Speech Agent Arena with a 1115 Elo and scores 87.4% accuracy and 90.7% experience on ServiceNow's EVA-Bench (vendor-reported, with GPT-5.5 as the reasoning model). Launch pricing is 50% off at $0.03 per minute.

Cartesia launches Managed Agents voice agent platform: #1 of 30 on Speech Agent Arena, $0.03 per minute at launch

Key Takeaways

  • On Artificial Analysis's Speech Agent Arena blind preference test, Managed Agents ranks #1 of 30 agents with a 1115 Elo, ahead of Gemini 3.1 Flash Live Minimal (1099), Grok Voice 3.0 (1064) and GPT-Live-1 (1041) (Cartesia blog, as cited by the vendor)
  • First-attempt results on ServiceNow EVA-Bench across 200+ customer service, IT service and HR scenarios: 87.4% accuracy and 90.7% experience, versus 73.7%/71.2% for Grok Voice 3.0 and 59.0%/61.6% for GPT Realtime 2.1 (EVA-Bench)
  • All these benchmark runs use GPT-5.5 as the reasoning model; Cartesia's internal evaluation says 85% of calls had no turn-taking issues, versus 67% for other agents
  • Launch pricing is 50% off at $0.03 per minute; Cartesia says the platform has already handled tens of millions of conversations in finance, retail, hospitality and healthcare
  • It supports 44 languages; English, Spanish, Hindi, French and Japanese can switch mid-call today, with the rest coming soon
Read full story

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Mistral AI unveiled Voxtral 3, a production audio intelligence suite paired with a real-time Voice-Agent API. The lineup features the 4B-parameter Mini Transcribe, Small Transcribe 3, and a turn-key voice agent SDK built on LiveKit. Supporting transcription across 50 languages with diarization, multi-lingual TTS with emotional tags across 35+ languages, and 30-minute voice cloning, Voxtral 3 redefines voice AI economics. In Artificial Analysis independent benchmarks, Small Transcribe 3 secured rank #3 globally with a 2.1% error index (outperforming ElevenLabs Scribe v2), while Realtime Transcribe delivers sub-500ms latency at $0.04/min for full voice agent turns.

Mistral Releases Voxtral 3 Audio Model Suite and Real-Time Voice-Agent API with Sub-500ms Latency

Key Takeaways

  • Mistral AI launched the Voxtral 3 suite spanning transcription, emotional TTS, studio-grade voice cloning, and a LiveKit-powered Voice-Agent SDK
  • Artificial Analysis independently verified Small Transcribe 3 at a 2.1% error index, outperforming ElevenLabs Scribe v2 (2.2%) and Grok Voice 2.0 (2.3%)
  • Realtime Transcribe 3 achieves sub-500ms latency, delivering sub-second full conversational voice-agent turns
  • Aggressive pricing: Mini Transcribe starts at $0.0035/min, and managed voice agent sessions cost just $0.04/min paired with Mistral Small 4
Read full story

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

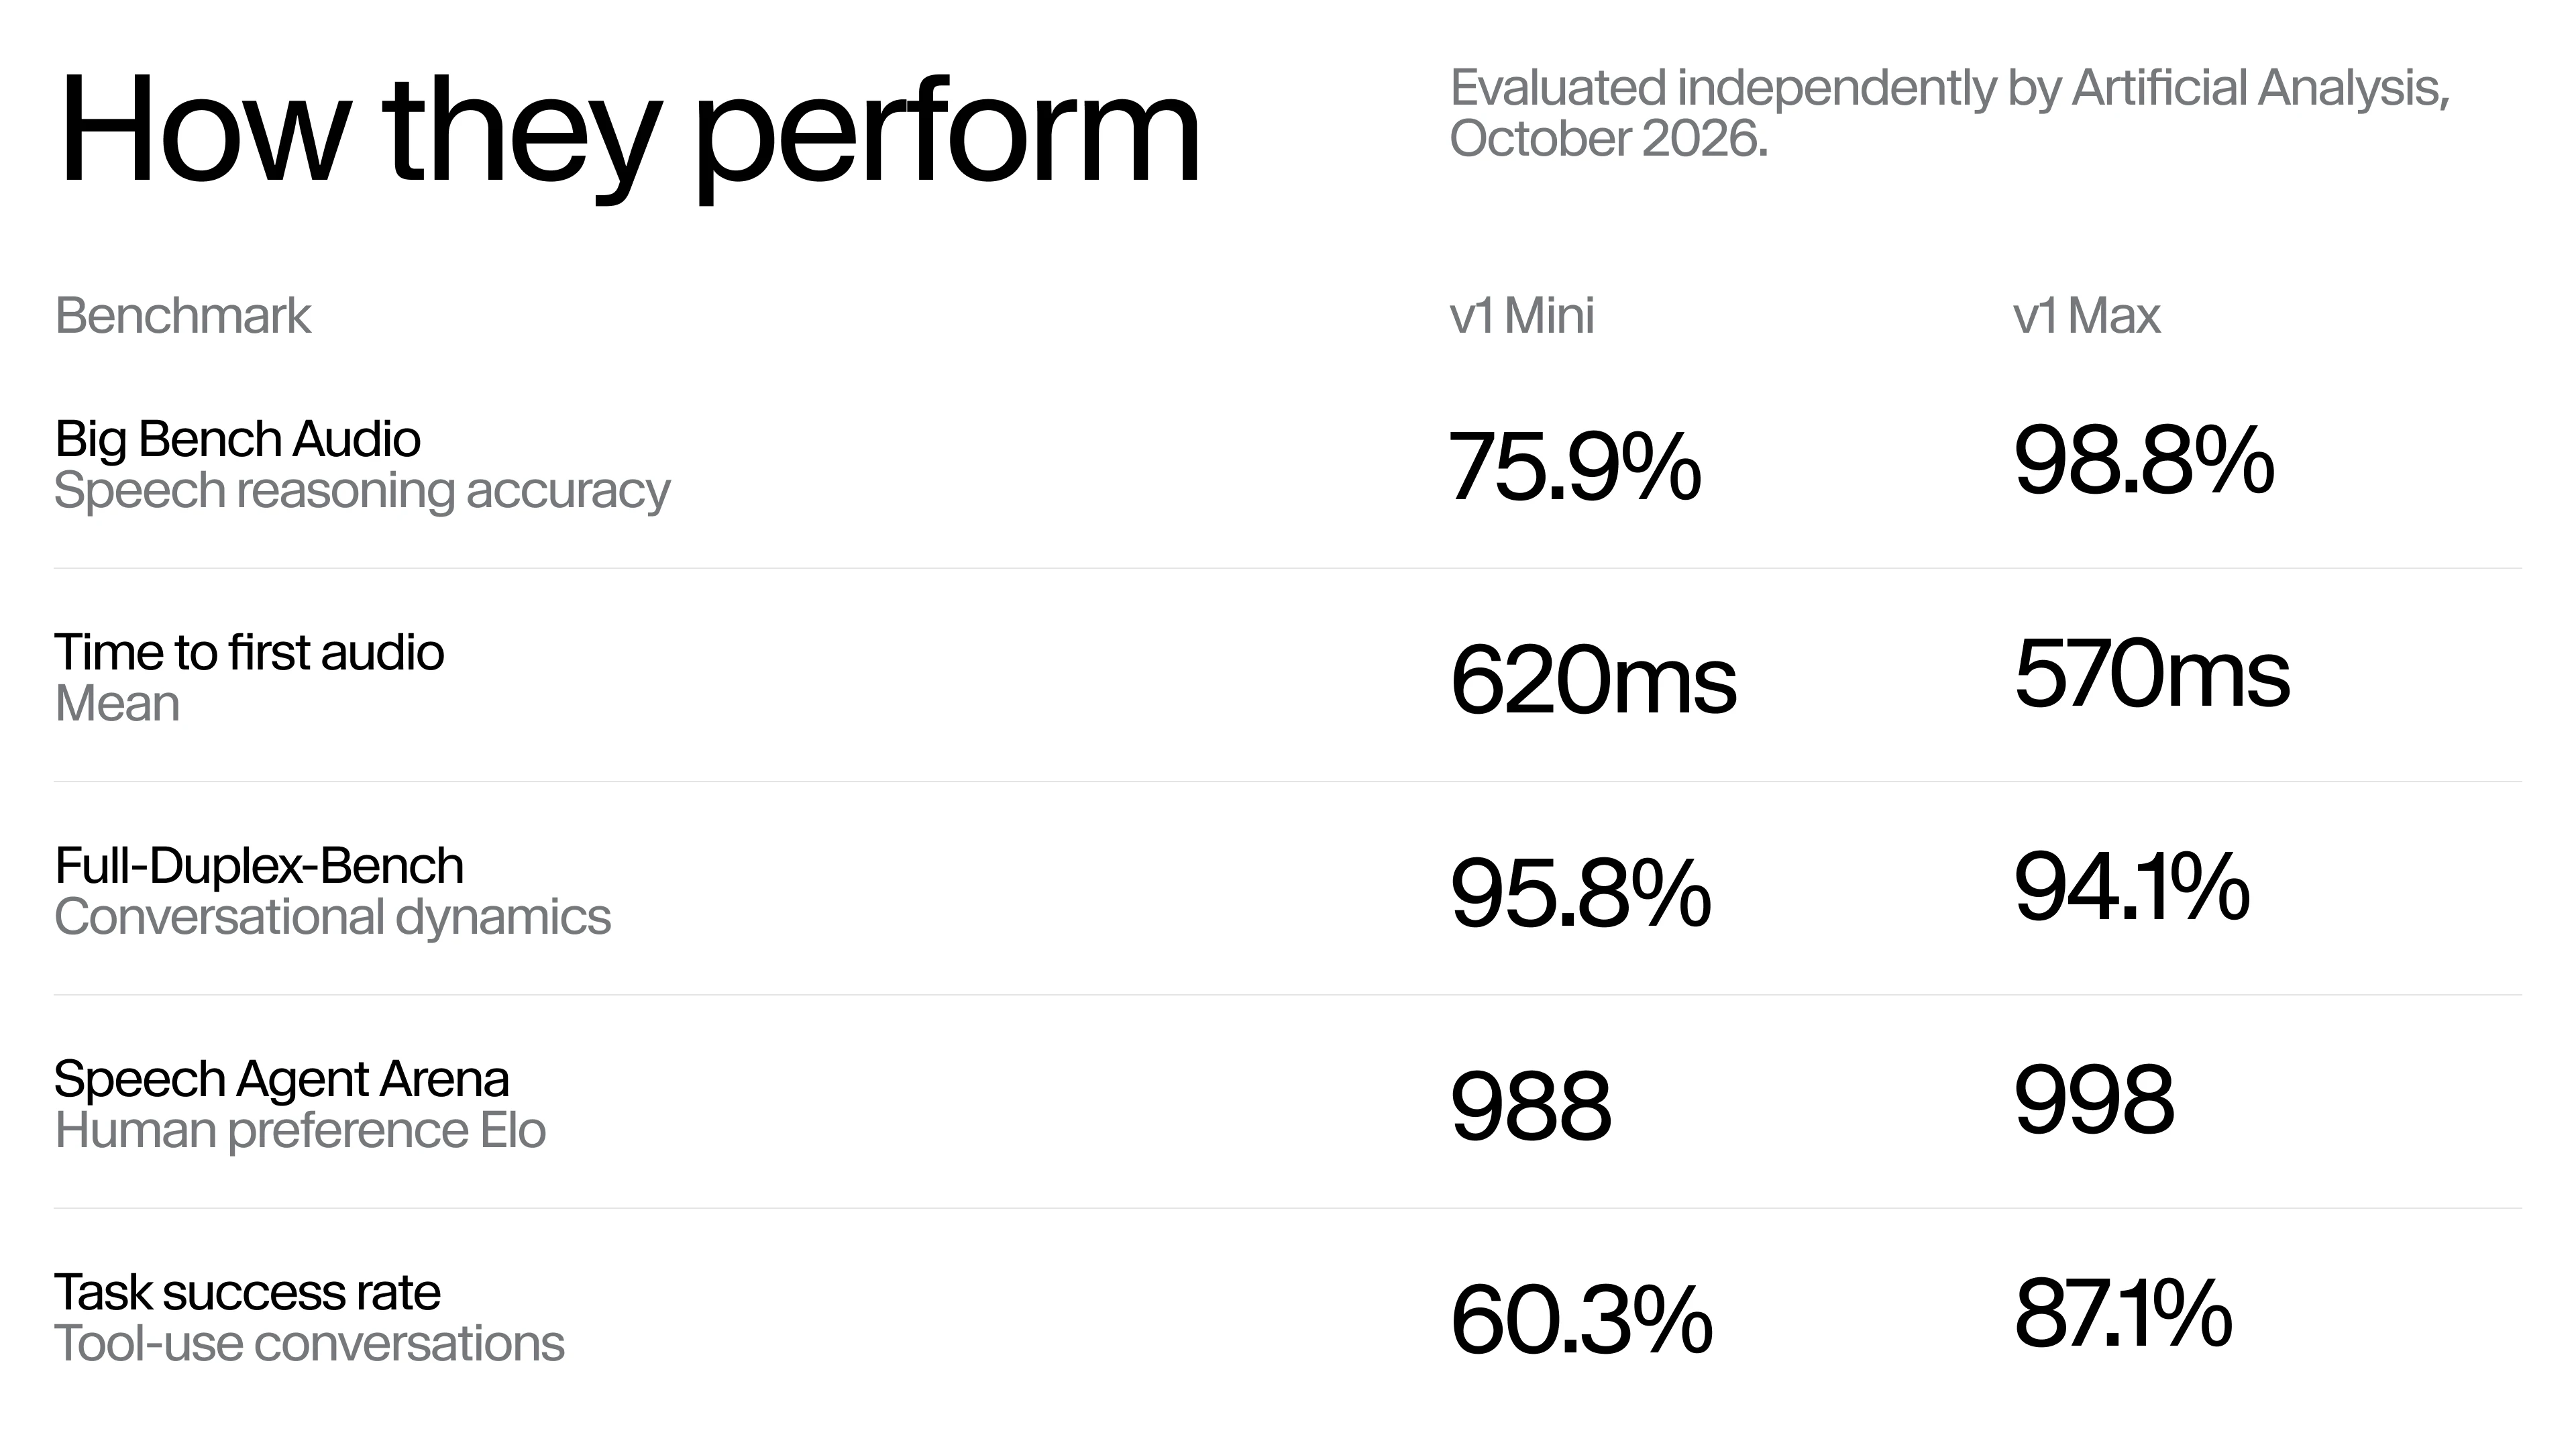
On Oct 20 ElevenLabs released Eleven Realtime, end-to-end speech-to-speech models where each model is a complete voice agent, removing the need to wire up speech recognition, an LLM and text-to-speech yourself. v1 Mini targets low-cost natural conversation and v1 Max targets support and multi-step tool use. Both cover 90+ languages and 17,000+ voices. Citing independent Artificial Analysis evals, Max answers 98.8% of Big Bench Audio correctly and starts speaking in 0.57s on average. The API is OpenAI Realtime compatible, so migrating means changing the endpoint and model name.

ElevenLabs launches Eleven Realtime v1 Mini and Max speech-to-speech models: Max scores 98.8% on Big Bench Audio, speaks in 0.57s on average, and is OpenAI Realtime API compatible

Key Takeaways

  • Speech reasoning (independent Artificial Analysis eval cited by ElevenLabs): on 1,000 Big Bench Audio questions, v1 Max scores 98.8% and v1 Mini 75.9%
  • Speed (vendor-stated): Max starts speaking in 0.57s on average and Mini in 0.62s; the launch post says "half a second", slightly faster than the blog figures
  • Conversation dynamics and preference: Full-Duplex-Bench Mini 95.8%, Max 94.1%; Speech Agent Arena blind tests Max 998, Mini 988
  • Tool-use task completion: Max 87.1% vs Mini 60.3%, which is why ElevenLabs recommends Max for heavy tool calling
  • 90+ languages and 17,000+ voices; the Realtime API is WebSocket-only at wss://api.elevenlabs.io/v1/convai/realtime and works with the OpenAI SDK; pricing was not in the launch post
Read full story
Linked Models & Agents:
⚡ Eleven Realtime v1 Mini⚡ Eleven Realtime v1 Max🤖 ElevenAgents🌐 ElevenLabs🌐 Artificial Analysis

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

On Oct 20 Mistral released Voxtral 3: the Voxtral Small/Mini Transcribe 3 speech-to-text models, Voxtral Mini Transcribe Realtime 3, the Voxtral Mini TTS 3 (Voxtral Speech 3) text-to-speech model, and a LiveKit-based voice agent SDK that streams listening, reasoning with tool calls, and speaking as one pipeline, with each turn completing in under a second per Mistral. Transcription covers 50+ languages with diarization and context biasing; TTS covers 35+ languages and 50+ dialects, plus Pro Voice cloning from 30 minutes of audio. It is live on the Mistral API (EU, US and global endpoints) and can be self-deployed.

Mistral launches the Voxtral 3 speech model family and a voice agent SDK: transcription in 50+ languages, TTS at $13 per 1M characters, EU-hosted or self-deployed

Key Takeaways

  • Multilingual transcription (vendor-reported): macro WER over 45 FLEURS languages is 4.1% (language forced) / 4.0% (inferred) for Voxtral Small Transcribe 3, tied with Microsoft AI Transcribe 2 and ahead of Scribe v2 (4.9%) and Whisper large-v3 (16.0%/14.9%)
  • Diarization (vendor-reported): cpWER of 18.4% for Small and 18.6% for Mini, vs 30.9% for the previous Voxtral Mini Transcribe 2 and 38.4% for Gemini 3.5 Transcribe
  • Pricing: Voxtral Mini Transcribe 3 is 4B parameters at $0.0035/min (docs list it as Public Preview with 32k context); Voxtral Speech 3 costs $13 per 1M characters
  • Realtime: Voxtral Mini Transcribe Realtime 3 runs below 500 ms latency; in Mistral's 35-language FLEURS chart the 480 ms setting scores 6.4% WER, still behind Gemini 3.5 Realtime Transcribe at 4.2%
  • The voice agent SDK is built on LiveKit with SIP telephony and WebRTC; each stage (LLM, voice, language) is swappable, and Pro Voice clones a voice from 30 minutes of audio
Read full story
Linked Models & Agents:
⚡ Voxtral Small Transcribe 3⚡ Voxtral Mini Transcribe 3⚡ Voxtral Mini Transcribe Realtime 3⚡ Voxtral Mini TTS 3🤖 Voxtral voice agent SDK🌐 Mistral AI🌐 LiveKit
ADSponsored

SpaceXSI launches Grok Voice 3.0: speech-to-speech model tops Artificial Analysis S2S Index at 86.9, price held at $0.08/min

SpaceXSI (SpaceX Super Intelligence, x.ai) released Grok Voice 3.0 on 2026-10-14 17:04 UTC. Per Artificial Analysis testing (Oct 13) cited on the official blog, it scores 86.9 on the Speech-to-Speech Index (Grok Voice 2.0 81.3, GPT-Live-1 Astra 83.2, Gemini 3.8 Live 82.6), 97% on Full Duplex Bench, and 71.6% on τ-Voice — on par with GPT-Live-1 at ~40% lower latency. In the Voice Agent API, grok-voice-latest now aliases grok-voice-3.0 with an unchanged interface at $0.08/min; grok-voice-2.0 is deprecated.

SpaceXSI launches Grok Voice 3.0: speech-to-speech model tops Artificial Analysis S2S Index at 86.9, price held at $0.08/min

Key Takeaways

  • #1 on Artificial Analysis Speech-to-Speech Index at 86.9 (v2.0 81.3, GPT-Live-1 Astra 83.2, Gemini 3.8 Live 82.6)
  • Big Bench Audio 98.5%, Speech Agent Arena Elo 1070, task success 94.8%, Full Duplex Bench 97.0%
  • τ-Voice 71.6%, comparable to GPT-Live-1 (Astra) at ~40% lower latency; top accuracy (74%) on ServiceNow EVA-Bench
  • Same price: $0.08/min ($4.80/hr); grok-voice-latest auto-upgraded to 3.0, grok-voice-2.0 deprecated
  • Production scale (vendor figures): ~20k Starlink support calls/day, ~70% resolved with no human
Read full story
Linked Models & Agents:
⚡ Grok Voice 3.0⚡ Grok Voice 2.0⚡ GPT-Live-1⚡ Gemini 3.8 Live🌐 SpaceXSI🌐 xAI🌐 Artificial Analysis🌐 ServiceNow

xAI Concludes Galaxy Event: Unveils Enterprise Voice Agent API & Builder

xAI wrapped up its three-day Galaxy developer event, launching the enterprise Voice Agent API and Voice Agent Builder. Powered by Grok end-to-end multimodal audio stream, it supports sub-100ms interruptions, emotional tone modulation, and autonomous call-center workflows.

Key Takeaways

  • Launches enterprise full-duplex Voice Agent API and visual workflow builder
  • End-to-end multimodal audio streaming with sub-100ms conversational turnarounds
  • Direct integrations with CRM backends for autonomous customer support and sales
Read full story

OpenAI: GPT-Live-1 live in the API—full-duplex voice agents that listen while speaking

OpenAI Developers said GPT-Live-1 is available in the API: bring ChatGPT’s natural back-and-forth into your app with voice agents that listen while they speak, using the models and harness you choose. OpenAI’s Tibo also noted builders can use the same full-duplex voice stack shipped to ~1B ChatGPT users, with solid tool calling.

Key Takeaways

  • GPT-Live-1 is live in the OpenAI API for full-duplex voice agents.
  • Agents can listen while speaking and pick model + harness.
  • Same voice stack as ChatGPT; strong fit for tool-calling voice apps.
Read full story
Linked Models & Agents:
⚡ GPT Live 1🌐 OpenAI

xAI brings Grok Voice to LiveKit: STT, Grok 4.3, and TTS in one ZDR AgentSession

SpaceXAI said Grok Voice models can now be used in LiveKit to build voice agents with full zero-data-retention support. LiveKit showed a patient-intake agent that cascades Grok STT, Grok 4.3, and Grok TTS through LiveKit Inference in a single AgentSession, with one set of credentials and billing. For developers, that is a three-string voice stack instead of a glued-together ASR, LLM, and TTS bill.

Key Takeaways

  • Grok Voice is available in LiveKit with zero-data-retention on every hop.
  • STT, Grok 4.3, and TTS cascade in one AgentSession with unified credentials and billing.
  • The reference build is a patient-intake agent for real-time, tool-using voice workflows.
Read full story
Linked Models & Agents:

Grok Voice Think Fast 2.0 ranks #1 on speech-to-speech and is live in API and Agent Builder

SpaceXAI said Grok Voice Think Fast 2.0 is #1 on the Artificial Analysis Speech-to-Speech Index, which scores whether voice agents can reason over speech, resolve real customer issues, and complete tasks with tools. The model is available via API and Agent Builder. SpaceXAI said Starlink is already using Grok Voice to handle more than 15,000 inbound support and sales calls a day.

Key Takeaways

  • Think Fast 2.0 is scored on reasoning, issue resolution, and tool use—not just spoken fluency.
  • The model is live in the API and Agent Builder for teams building voice agents.
  • Starlink’s 15,000 daily calls are a production proof point for voice LLMs in support.
Read full story
Linked Models & Agents: