

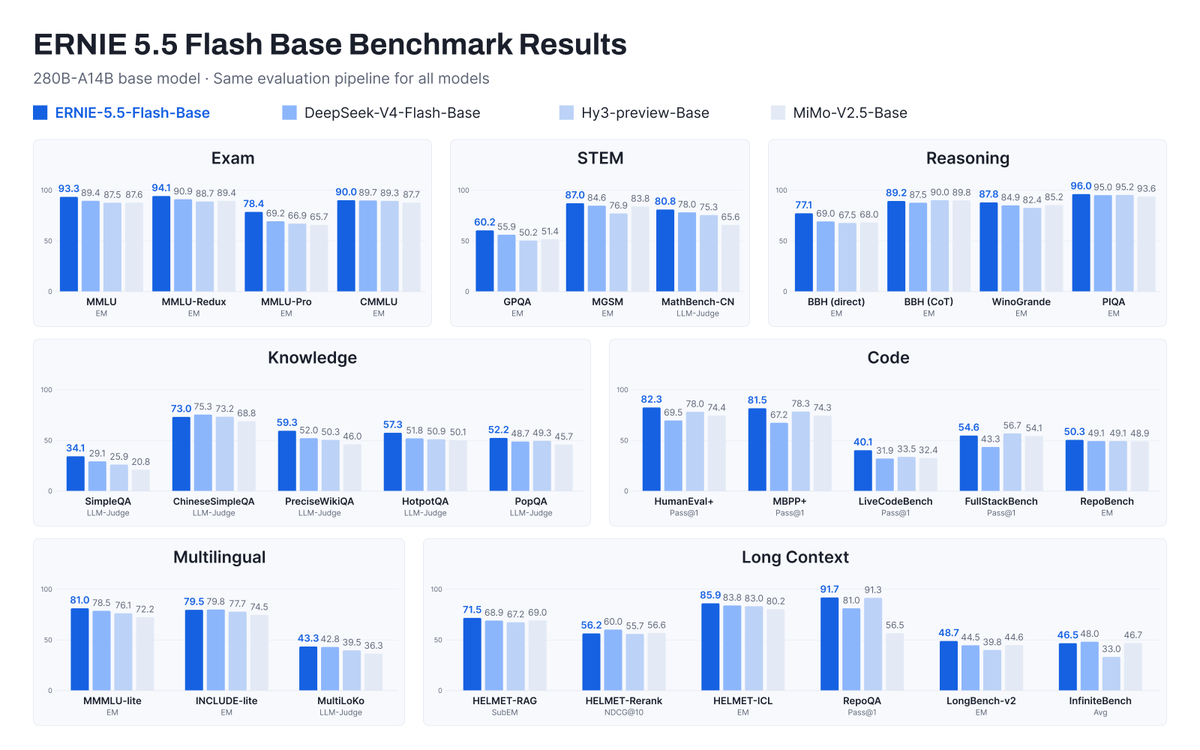
On November 5 Baidu (official blog + @BaiduResearch) open-sourced ERNIE-5.5-Flash-Base: a text-only MoE base checkpoint at end of pre-training (no mid/post-training), 280B total / 14B active per token, 33.5T pretrain tokens, up to 128K train context and 1M for fine-tune/inference. FP8 and BF16 weights are on Hugging Face and ModelScope. Under Baidu's unified eval pipeline vs similar bases: MMLU 93.3, HumanEval+ 82.3, LiveCodeBench 40.1 (vendor-reported). Post-trained ERNIE 5.5 Flash "will follow". License is custom (excludes EU/UK/South Korea; commercial use above $50M related revenue needs prior written authorization).
Key Takeaways
- ✓Nov 5 open base at end of pre-training: 280B total / 14B active — not a chat/instruct model
- ✓33.5T pretrain tokens; up to 128K train context, 1M for fine-tune and inference
- ✓Vendor unified eval: MMLU 93.3, HumanEval+ 82.3, LiveCodeBench 40.1 vs similar bases
- ✓Architecture: 37 HCA + 6 MLA-DSA layers; Multi-Router Latent MoE (512 routed top-10 + 1 shared)
- ✓Custom license (not Apache): excludes EU/UK/South Korea; >$50M related revenue needs Baidu written authorization
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
Many open drops are post-trained chat weights, so continued pre-training is hard to control. On November 5 Baidu released ERNIE-5.5-Flash-Base as an end-of-pretraining text base for domain adaptation, instruction tuning and RL. The post-trained ERNIE 5.5 Flash "will follow"; this is not a chat product.
Architecture Highlights & Internals
280B total / 14B active per token; 43 layers (1 dense + 42 MoE) with 512 routed experts (top-10) plus 1 shared. Hybrid attention: 37 HCA layers (one cache entry per 128 tokens) and 6 MLA+DSA layers, plus Multi-Router, VHA and ECHO. FP8 and BF16 weights ship with SGLang/vLLM examples.
Authoritative Benchmarks & Measured Scores
Vendor-reported results under Baidu's unified harness versus similar bases: MMLU 93.3, MMLU-Pro 78.4; HumanEval+ 82.3, LiveCodeBench 40.1; RepoQA 91.7, LongBench-v2 48.7. No independent third-party replication is claimed here; do not invent extra scores.
Developer Hands-on Guide
Get weights from Hugging Face baidu/ERNIE-5.5-Flash-Base, ModelScope and the ERNIE blog. Serve via completions with BOS (add_special_tokens=True). Custom license excludes the EU, UK and South Korea; related revenue above $50M needs prior written authorization. Read LICENSE before deploy.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.