
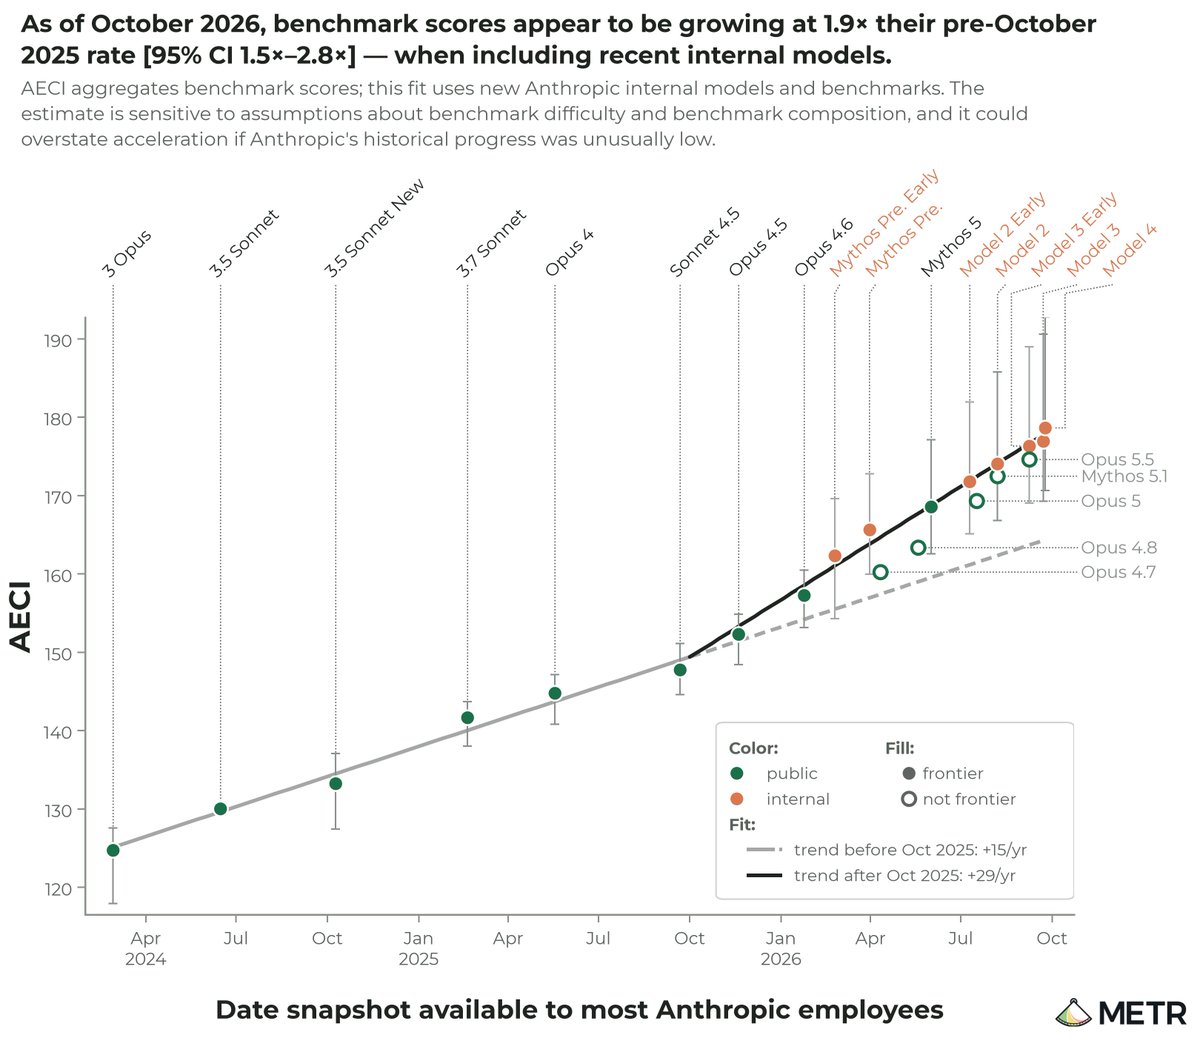
On November 5, independent evaluator METR published a high-access assessment at Anthropic (Aug 12–Oct 29, 2026). As of October 2026, Anthropic is likely improving model capabilities on well-specified tasks at about twice the March 2024–October 2025 historical rate. Since October 2025, AECI scores grew at an estimated 1.9x the prior rate [95% CI 1.5–2.8]. METR judges that a majority of current acceleration is attributable to AI-assisted R&D, not faster training-compute scaling; Anthropic redacted much of the most informative evidence.
Key Takeaways
- ✓Subjective call: ~2x historical rate on well-specified tasks (high uncertainty; ~1.3x–3x plausible; METR)
- ✓AECI: ~1.9x faster growth since Oct 2025 [95% CI 1.5–2.8], ~two years of prior progress in one year (includes unreleased models)
- ✓Attribution: confident not from faster training-compute growth; majority of current acceleration from AI-assisted R&D (~80% subjective guess), not fully autonomous contributions
- ✓Risk: no clear bottlenecks observed for next 12 months, so further acceleration risk; much key evidence redacted by Anthropic
- ✓Process: separate from the Oct 15 employee-like access pilot; compute-allocation verification was canceled mid-engagement
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
Whether AI is accelerating its own R&D is central to frontier RSP thresholds and public risk judgment. From August 12 to October 29, 2026, METR ran a high-access assessment at Anthropic and published a public summary on November 5: as of October 2026, Anthropic is likely improving capabilities on well-specified tasks at about twice its historical rate.
Architecture Highlights & Internals
The review covered pretraining, RL, training compute, internal benchmarks and staff interviews. The main public evidence is a piecewise-linear AECI trend (Anthropic's Epoch Capabilities Index variant). Including unreleased Models 2/3/4 lifted the estimate above the ~1.7x figure in the Haiku 5.5 system card. Acceleration is described as mostly AI assistance rather than fully autonomous control of critical training steps.
Authoritative Benchmarks & Measured Scores
Since October 2025, AECI growth is about 1.9x the prior rate [95% CI 1.5–2.8]; robustness checks span roughly 1.1x–2.9x. Vendor system cards previously cited about 1.7x. METR stresses AECI's focus on easy-to-grade tasks may not map cleanly to real-world impact, and Anthropic redacted most of the most informative evidence, so the public must lean more on METR's judgment than ideal.
Developer Hands-on Guide
Read metr.org/blog/2026-11-05-anthropic-ai-rd-acceleration-assessment/. Useful checks: whether internal evals overfit verifiable tasks, whether AI assistance has entered critical training loops, and whether probes stay monitorable under training pressure. Do not treat "~2x" as a product-shipping schedule; this engagement is separate from Anthropic's October employee-like access announcement.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.