AI Coding Live News

NVIDIA says AI agents now steer the SETI Allen Telescope Array, calibrating it and analyzing up to 2.4 Tbps of live radio data from plain-language requests

An Oct 30 NVIDIA blog post says Breakthrough Listen and the SETI Institute have brought agents into daily SETI work at the Allen Telescope Array (ATA, 42 dishes of 6 m each) in Northern California: from a single natural-language request, agents can steer the antennas, calibrate and focus, fix data errors, and run AI models on the live stream. Holoscan's DAQIRI library pulls sensor data straight into GPU memory, the SETI Institute's CyberEther handles signal processing, and the web-based orchestrator Nexus acts as the agent harness, handling up to 2.4 Tbps on premises on RTX PRO 6000 Blackwell GPUs. The pipeline has made the first real-time AI detection of a pulsar in the Crab Nebula, and the team is evaluating open models such as Nemotron. The @NVIDIAAI Halloween post on Oct 31 drew about 274 likes.

NVIDIA says AI agents now steer the SETI Allen Telescope Array, calibrating it and analyzing up to 2.4 Tbps of live radio data from plain-language requests

Key Takeaways

  • Throughput: up to 2.4 Tbps of radio data on NVIDIA RTX PRO 6000 Blackwell GPUs, with inference running on premises next to the instrument (NVIDIA blog, vendor-reported)
  • Three layers: DAQIRI moves sensor data straight into GPU memory, CyberEther does the signal math with cuFFT and cuBLAS, and Nexus serves as the agent harness for instrument state, compute, and pipelines
  • Capability: one plain-language request can steer the ATA's 42 six-meter dishes, calibrate and focus, fix data errors, and plot results; NVIDIA says this compresses weeks or years of human work into hours
  • Milestone: the first real-time AI detection of a pulsar in the Crab Nebula; no false-positive rates or other metrics were published, and no extraterrestrial signal has been found
  • Next: evaluating open models such as Nemotron for observatories where data locality matters, possibly one day running offline on the far side of the Moon
Read full story

Mistral releases the open weights of Mistral Large 4 "Le Chonk": a 1T-total, ~52B-active multimodal MoE that Mistral says leads open models on FrontierCode 2.0

On Oct 29 Mistral released an improved Mistral Large 4 (Le Chonk) with open weights on Hugging Face (plus an NVFP4 quantized checkpoint), served on its API as mistral-large-4. After about three more weeks of reinforcement learning since the early-October preview, Mistral reports 19.7% on FrontierCode 2.0, Terminal-Bench 4.0 up from 28% to 41%, and new low/medium/high reasoning modes. The license is a modified MIT that allows commercial use, but running a model-as-a-service business needs a separate commercial license.

Mistral releases the open weights of Mistral Large 4 "Le Chonk": a 1T-total, ~52B-active multimodal MoE that Mistral says leads open models on FrontierCode 2.0

Key Takeaways

  • Specs: about 1T total parameters with 49B active per token (about 52B including embeddings and output layers), 128 routed experts with 4 active plus 1 shared expert, 1M context, text and image input
  • Per Mistral: 19.7% on Cognition's FrontierCode 2.0, ahead of DeepSeek V4.1 Flash at 19.3% and GLM-5.3 at 17.8%, first among open models
  • 48% on the Artificial Analysis Coding Agent Index, roughly tied with GLM-5.3 while using 47% fewer tokens per task on average; Terminal-Bench 4.0 rose from 28% in preview to 41%
  • 51% on the Artificial Analysis Cyber Index, and a 96.6% average refusal rate on malicious cyber requests, which Mistral says is the highest among open models
  • Trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters; in Surge Code blind pairwise tests it ranked behind only Claude Opus 5.5
Read full story
Linked Models & Agents:

NVIDIA open-sources Nemotron 3.5 Transcribe, a 30B MoE speech model with about 4B active parameters that handles transcription in 40 languages, speaker attribution and translation, and tops open models on the Open ASR English leaderboard

NVIDIA AI announced Nemotron 3.5 Transcribe on Oct 28, with weights on Hugging Face and ModelScope. It is an offline, instruction-driven speech model whose single checkpoint covers transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, and audio question answering, on recordings up to an hour long with up to eight labeled speakers. NVIDIA says it ranks first among open-weight models on the Hugging Face Open ASR English leaderboard at 5.33% average WER, and Artificial Analysis measured a 2.8% AA-WER, tied for first among open models with Voxtral Small, which uses 24B active parameters. The weights, the Granary v2 training data and fine-tuning recipes are all released.

NVIDIA open-sources Nemotron 3.5 Transcribe, a 30B MoE speech model with about 4B active parameters that handles transcription in 40 languages, speaker attribution and translation, and tops open models on the Open ASR English leaderboard

Key Takeaways

  • Architecture: a speech encoder paired with a Mamba-2/Transformer hybrid MoE language model, about 30B total parameters (34B in the model card counting the audio encoder) and about 4B active per token (4.3B in the model card), shipped in BF16, FP8 and NVFP4
  • Capabilities: transcription in 40 languages, translation between 31 languages and English, speaker attribution in 13 languages, audio Q&A (trained in English only) and word-level timestamps, on recordings up to 1 hour with up to 8 speakers
  • Official and third-party figures: first among open models on the Open ASR English leaderboard (5.33% average WER), 4.62% mean WER across 7 languages and 10.98% on long-form; Artificial Analysis AA-WER 2.8% and 1.8% on its AA-AgentTalk voice-agent set (next-best open model 2.3%)
  • Artificial Analysis measured DeepInfra's hosted endpoint at a 75x speed factor, transcribing a minute of audio in under a second, priced at $2.00 per 1,000 minutes
  • Licensed under OpenMDW-1.1 for commercial use; Granary v2 data and NeMo Speech fine-tuning tools are released too, and in NVIDIA's medical case study fine-tuning cut WER a further 45.8% relative to the best prompt
Read full story
Linked Models & Agents:
⚡ Nemotron 3.5 Transcribe 30B-A4B⚡ Voxtral Small🌐 NVIDIA🌐 Hugging Face🌐 Artificial Analysis

AWS & UIUC Introduce Lean4AgenticRL: Verifiable Multi-Level Process Rewards in Lean4, Reaching 77.3% on TerminalBench

Researchers from Amazon Web Services (AWS) and UIUC unveiled Lean4AgenticRL (arXiv:2610.22448). Tackling the limitations of conventional agentic reinforcement learning relying on sparse, binary outcome rewards, the framework grounds multi-level process rewards within a formal Lean4 verification schema. Utilizing workflow-stage-normalized GRPO, the resulting LAR-27B model reaches 77.3% on TerminalBench-2.1, outperforming base models by 9.89% and surpassing comparable open models by 5.07%.

AWS & UIUC Introduce Lean4AgenticRL: Verifiable Multi-Level Process Rewards in Lean4, Reaching 77.3% on TerminalBench

Key Takeaways

  • AWS and UIUC introduced Lean4AgenticRL (arXiv:2610.22448), the first framework grounding multi-level process rewards in Lean4 formal proofs
  • Overcomes sparse outcome reward bottlenecks using workflow-stage-normalized GRPO to stabilize multi-turn credit assignment
  • LAR-27B hits 77.3% on TerminalBench-2.1, outperforming base models by 9.89% and outscoring comparable baselines by 5.07%
  • Ablations show verifiable process rewards accelerate RL convergence by over 42%, establishing a rigorous paradigm for terminal coding agents
Read full story
Linked Models & Agents:
ADSponsored

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

MiniMax officially announced M3.1 Flash, its next-generation lightweight frontier model (previously dominating leaderboards as the secret model Space Bunny across 200T+ tokens). Featuring a native 1M context window, flat-rate API pricing of $0.15 / $0.60 per 1M input/output tokens ($0.015 cache reads), and 3x faster inference at 1/3 the cost of M3. It surged +106 points to 1588 on LMSYS Code Arena: WebDev (#12 among open models), with full weights set for open release on October 23.

MiniMax Releases M3.1 Flash: 1M Context Window, $0.15/M Token Pricing, Surging +106 Points in WebDev Code Arena

Key Takeaways

  • MiniMax officially launched M3.1 Flash, unveiling that it was the mystery model Space Bunny evaluated across 200T+ tokens
  • Features native 1M context with flat-rate API pricing of $0.15/$0.60 per 1M tokens ($0.015 cache reads), offering 3x speed at 1/3 cost of M3
  • Debuts on LMSYS Code Arena: WebDev at 1588 Elo (+106 pts over M3), ranking #12 among open models with major leaps in Gaming (+179) and Reference Design (+155)
  • Artificial Analysis benchmark confirms Intelligence Index of 42 and HLE of 48% at half the token consumption of rivals; weights release on Oct 23
Read full story
Linked Models & Agents:

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Arena announced a major update to Code Arena: WebDev: DeepSeek-V4.1-Flash-20261017 (Max) clinched the #1 position among open models with 1670 points, surpassing Kimi K3 (Max) at a 10x lower cost. Ranking #12 overall, it outperforms Claude Opus 5 (High) and narrows the gap with closed-source frontier GPT-6 Sol (Max) to roughly 10 points, resetting the Pareto efficiency curve at $0.30 input / $1.20 output per million tokens.

Arena Code Arena: WebDev Update: DeepSeek-V4.1-Flash Becomes #1 Open Model, Scoring 1670 to Rival GPT-6 Sol and Surpass Claude Opus 5

Key Takeaways

  • DeepSeek-V4.1-Flash-20261017 (Max) captured the #1 open model position in Arena Code Arena: WebDev with 1670 points, surpassing Kimi K3 (Max)
  • Ranks #12 overall on the leaderboard, defeating Claude Opus 5 (High) and trailing closed-source champion GPT-6 Sol (Max) by only ~10 points
  • Resets the Pareto efficiency frontier at $0.30 input / $1.20 output per million tokens, cutting operational costs by ~10x against rival models
  • Gains +52 points over its previous 20260910 checkpoint in just over a month
Read full story
Linked Models & Agents:

Alibaba Unveils Million-Image/Day Multi-Agent CommerceGen-Studio (6B SKU-DiT Beats 20B Models and Nano Banana Pro) Alongside Microsoft's Test-Time Diversity Alignment (MSR)

Alibaba Taobao & Tmall Group detailed CommerceGen-Studio (arXiv:2610.20603, 52 HF upvotes), a production multi-agent generation system serving millions of images daily within seconds. Its 6B SKU-DiT trained via Reinforce-Distill-Reinforce (RDR) scores 9.43 (single-image) and 9.45 (multi-image) on CommerceGen-Bench, outperforming 20B open models and closed-source Nano Banana Pro. Meanwhile, Microsoft Research introduced Mine, Sample, Render (MSR, arXiv:2610.21185) for training-free test-time diversity alignment.

Alibaba Unveils Million-Image/Day Multi-Agent CommerceGen-Studio (6B SKU-DiT Beats 20B Models and Nano Banana Pro) Alongside Microsoft's Test-Time Diversity Alignment (MSR)

Key Takeaways

  • Alibaba's CommerceGen-Studio (arXiv:2610.20603) serves millions of commercial product images per day in production with a latency of a few seconds per image
  • Its 6B SKU-DiT trained with Reinforce-Distill-Reinforce (RDR) scores 9.43 (single-image) and 9.45 (multi-image) on CommerceGen-Bench, beating 20B open models and closed-source Nano Banana Pro (9.39 / 9.33)
  • Combining SKU-DiT with the self-evolving PERL-Agent loop and Layout Thinker Optimization pushes scores to 9.62 (single-image) and 9.48 (multi-image)
  • Microsoft Research's Mine, Sample, Render (MSR, arXiv:2610.21185) externalizes test-time diversity via corpus-mined attribute sampling across webpage UI design, agent-generated 3D assets, user simulation, and text-to-image
Read full story
Linked Models & Agents:

Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

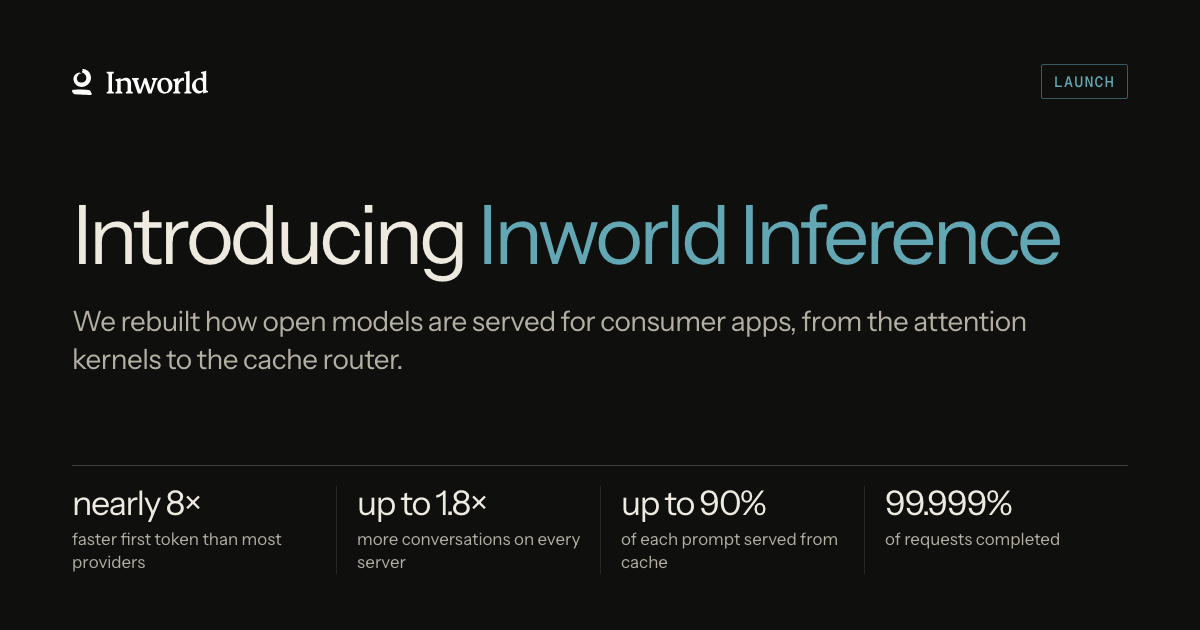
On 2026-10-14 Inworld AI opened Inworld Inference to every developer, positioning it as an inference service for consumer apps (companions, tutors, voice, interactive fiction). Instead of listing thousands of models it builds a per-model serving stack for open models such as Gemma 4, GLM 5.3 Flash, DeepSeek and MiMo: draft-and-verify (speculative) decoding, a rewritten split-KV verify attention kernel, KV-aware routing and eval-gated low precision. Vendor-reported: Gemma 4 26B p95 first token of 0.31 s, 7.8x faster than the median OpenRouter provider; up to 90% of prompts from cache; 99.999% success over 20M+ GLM 5.3 Flash requests in 30 days. The API is OpenAI-compatible with Flex/Default/Priority/Fast tiers per request.

Inworld Inference opens to all developers: an open-model inference API built for consumer AI, with Gemma 4 26B p95 first token 7.8x faster than the median OpenRouter provider

Key Takeaways

  • Gemma 4 26B first token: p50 0.17 s / p95 0.31 s, 3.6x / 7.8x faster than the median OpenRouter provider (blog, vendor-reported snapshot, not a matched workload)
  • Pricing: Gemma 4 26B at $0.07 input, $0.035 cached, $0.34 output per 1M tokens, nearly 40% below the median no-training provider
  • Rewritten verify attention: 3.4–7.5x faster per layer, attention share of a decode step 27.5%→16.5%, p50 TTFT 154→117 ms at equal eval scores
  • KV-aware routing: GLM 5.3 Flash cache hits 25%→47%, DeepSeek V4.1 Flash 11%→33%; cached MiMo 2.6 Pro input costs 99% less
  • Reliability: 98 failures across 20M+ GLM 5.3 Flash requests in 30 days (~4.8 per million); per-request service_tier of Flex/Default/Priority/Fast
Read full story

Omni-Embed-Mini Binds 6 Modalities Without Forgetting: MBZUAI Opens 0.9B Dense Distillation Model Outperforming Gemini

Expanding text embedding models to multimodal domains typically triggers catastrophic forgetting in text retrieval, with existing omni-modal embedders ballooning past multi-billion parameters to compensate. MBZUAI researchers introduce Omni-Embed-Mini, a compact 0.9B architecture mapping text, speech, audio, image, video, and rich documents into a single shared cosine space. Crucially, text-side weights remain bit-identical to the base model, guaranteeing zero regression on text retrieval (49.57 nDCG@10 on MTEB-v2 BEIR-8). Powered by dense cascaded caption distillation, Matryoshka SigLIP loss, and online hybrid hard-negative mining, Omni-Embed-Mini is 2.7x to 9.5x smaller than competing open models, while its 2.3B variant surpasses proprietary gemini-embedding-2 on cross-modality averages.

Omni-Embed-Mini Binds 6 Modalities Without Forgetting: MBZUAI Opens 0.9B Dense Distillation Model Outperforming Gemini

Key Takeaways

  • Unifies text, speech, audio, image, video, and rich documents into a single shared space at only 0.9B parameters
  • Guarantees zero text forgetting via bit-identical frozen text weights (49.57 nDCG@10 on MTEB-v2 BEIR-8)
  • 2.3B model variant outperforms proprietary Google gemini-embedding-2 on cross-modality retrieval averages
Read full story
Linked Models & Agents:
A
AgentField / Santosh Radha@Agent-Field·
👀82
🔥95

AgentField open-sources CodeAF v0.6: one Go binary software factory for open models; vendor DeepSWE 54.9% #1 same-model

CodeAF is an Apache-2.0 Go binary that runs open-weight models as a local software factory with task fan-out and Pareto crewing. v0.6.0 shipped 2026-10-01; ★259 now. Vendor DeepSWE doc: /senior-dev solved 62/113 (54.9%) on DeepSeek V4 Flash vs nine other harnesses—with stated one-seed and sampling caveats.

AgentField open-sources CodeAF v0.6: one Go binary software factory for open models; vendor DeepSWE 54.9% #1 same-model

Key Takeaways

  • Agent-Field/CodeAF Apache-2.0; ★259 / 34 forks; install via agentfield.ai/get/codeaf
  • v0.6.0 published 2026-10-01T18:59:00Z; README still says early preview
  • Vendor DeepSWE same-model table: senior-dev 62/113 (54.9%) at ~22¢/task vs nine harnesses—one seed; sampling-contract caveat documented
  • Later same 113 tasks: 88/113 (77.9%) on DeepSeek V4.1 Flash; 78/113 (69.0%) on Kimi K3 (senior-dev only)
  • Built-in providers include OpenRouter, DeepSeek, GLM, Kimi, MiniMax, Qwen, Codex, Ollama; default worker/planner/checker crew
Read full story
ADSponsored

Command Code leads Composio agent-harness results with 18/30 tasks and 375-second average time

Command Code CEO Ahmad Awais shared Composio benchmark results claiming Command Code solved 18 of 30 tasks with a 375-second average time, leading the comparison on open models. The post references Composio testing GPT-6 Astra across six coding-agent harnesses and highlights substantial token differences when harnesses fail.

Key Takeaways

  • Command Code solved 18 of 30 tasks, with the post claiming the best accuracy among the tested harnesses.
  • Its reported average task time was 375 seconds, also described as fastest and ahead of DeepSeek's own harness.
  • The cited Composio test covered Codex, Claude Code, OpenCode, Hermes Agent, Pi Agent, and Command Code.
Read full story
Linked Models & Agents:

Agent Arena: DeepSeek-V4.1-Flash (Max) reshapes open-model Pareto frontier at ~$0.07/task

Arena.ai (@arena) reports Agent Arena results: DeepSeek-V4.1-Flash (Max) posts about +4.87% net improvement at roughly $0.07 median task cost — lowest among the top-3 open models — retaining ~98% of Hy4 preview’s net gain at ~73% lower cost and ~76% of Kimi K3 (Max) performance at ~92% lower cost.

Key Takeaways

  • DeepSeek-V4.1-Flash (Max) enters Agent Arena at about +4.87% net improvement.
  • Median task cost ~$0.07 — cheapest among top-3 open models.
  • Beats Hy4 / Kimi K3 on cost-efficiency and reshapes the Pareto frontier.
Read full story
Linked Models & Agents:

TechCrunch: Abliteration.ai commercializes guardrail removal, hosts abliterated GLM-5.3

TechCrunch reports startup Abliteration.ai turned the long-standing open-source abliteration technique (orthogonalization that removes refusal tendencies) into a hosted browser/API service, including an abliterated build of Z.ai's recent open-weight GLM-5.3. The company says it targets "offensive cyber, red-teaming, and agent testing work other models refuse to do." TechCrunch created a free account and says the abliterated GLM-5.3 complied with requests for a Chrome password-stealer script and a protocol for culturing a dangerous human pathogen at home. The platform offers a customer-side moderation layer and keeps some limits (e.g. suicide instructions in testing) but has no full KYC beyond logging the payment card. Safety researchers (including CivAI) warn scaled access could enable harm; some red-teamers say they still rely more on fine-tuning open models and that abliteration can reduce capability.

Key Takeaways

  • Commercial hosted abliterated open-weights, including GLM-5.3, via browser/API
  • Pitch: offensive cyber, red-team, agent testing; TechCrunch saw high-risk prompts complied with
  • Debate: lowers misuse friction vs helps defenders; no full KYC yet
Read full story

Together AI + Equinix + NVIDIA: Inference Exchange brings open models to global DCs

Together AI (@togethercompute) announces Equinix Inference Exchange with Equinix and NVIDIA: its open-model platform is live across Equinix’s global data centers, productizing both which model enterprises run and where it runs — arguing model choice and performance are not a trade-off.

Key Takeaways

  • Equinix Inference Exchange launches Together’s open-model platform across Equinix global DCs.
  • NVIDIA-backed enterprise inference path tying model choice to where workloads run.
  • Positions open source as the default enterprise AI build path without sacrificing performance.
Read full story
Linked Models & Agents:

Ollama switches Pro, Max, and Team to transparent per-token pricing

Ollama’s Pro, Max, and Team plans now bill at published per-token rates against a monthly credit pool: $20/month with $60 of usage, $100 with $300, and $500 Team with $1,000 shared across unlimited users. The plans plug into Claude Code, Codex, and a first-party API, with no service fees and no 5-hour or weekly caps—when the pool runs out, traffic continues at the same token price. Inference stays on dedicated US/EU compute (Singapore for a limited Qwen set) with zero retention and no training on prompts. Existing subscribers can keep the old plan; new signups land on the token model because GPU-time billing became hard to forecast as open models scaled to sizes such as Kimi K3.

Key Takeaways

  • Pro/Max/Team are $20/$100/$500 with $60/$300/$1,000 monthly token credits; Team shares one pool with unlimited seats.
  • No service fees or 5-hour/weekly caps; unused work continues at the published token rate and works with Claude Code and Codex.
  • US/EU dedicated inference with zero retention; existing plans stay until you upgrade, new signups use token pricing.
Read full story
Linked Models & Agents: