Empirical Benchmark Unmasks Sub-Agent Concurrency: SWE-bench Success Drops 24% as Token Costs Surge up to 3.3x
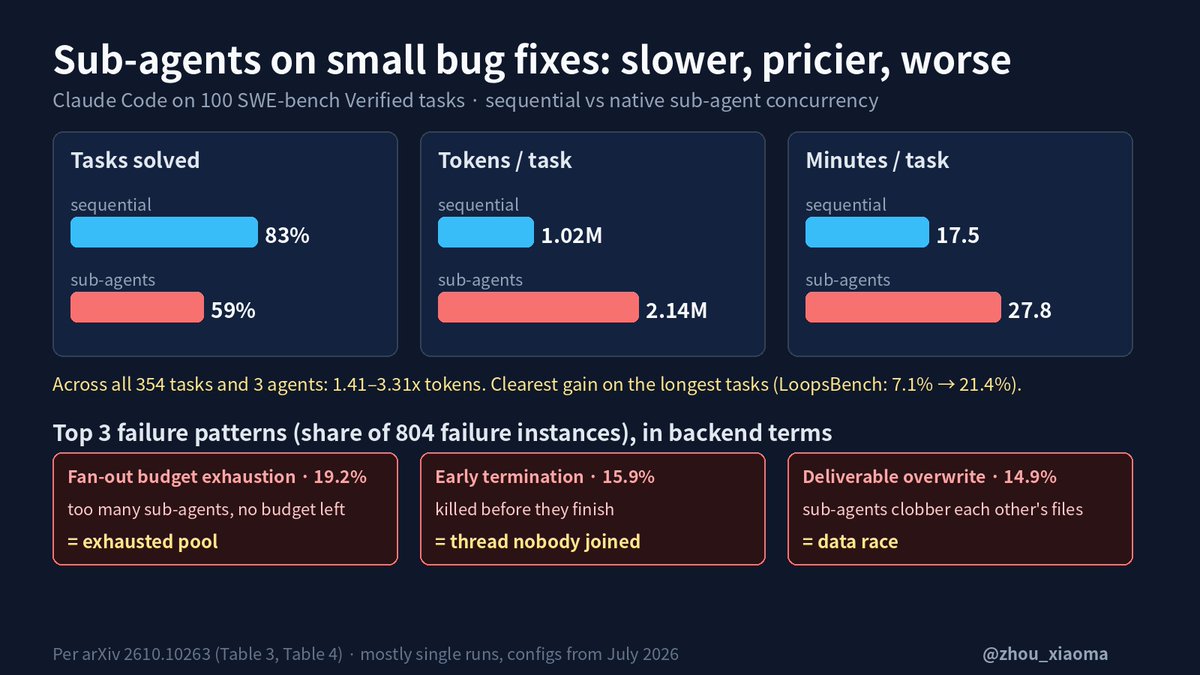
A comprehensive empirical study evaluated native sub-agent concurrency across 2,124 runs on Claude Code, Codex, and Kimi Code (354 tasks, ~$20.8K API cost). On 100 standard SWE-bench Verified tasks, enabling sub-agents caused Claude Code's solve rate to collapse from 83% to 59% (with latency increasing from 17.5 to 27.8 minutes) and Kimi Code from 77% to 59%, while token consumption inflated by 1.41x to 3.31x. The study revealed severe failure modes including budget-exhausting fan-outs, orphaned child processes, and concurrent delivery race conditions.
Key Takeaways
- A $20,800 empirical study across 2,124 runs revealed the real costs of native sub-agent concurrency in Claude Code, Codex, and Kimi Code
- On SWE-bench Verified, sub-agent concurrency dropped Claude Code's solve rate from 83% to 59% and Kimi Code from 77% to 59%
- Token consumption inflated by 1.41x-3.31x while execution times lengthened, caused by thread race conditions and budget exhaustion
- Delivered gains only on massive multi-file projects (LoopsBench: 7.1% to 21.4%); authors recommend sequential execution as the default
Linked Models & Agents: