
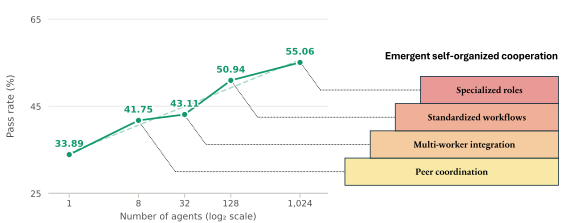
Zhihao Zhan, a Microsoft Research Asia researcher and co-first author, announced on X on Oct 24 that Agensh is now open source under MIT. It is a multi-agent coding harness with no central orchestrator: workers claim sub-tasks, verify and merge asynchronously. Per the authors, scaling from 1 to 1,024 agents lifts the final pandoc test-pass rate from 33.89% to 55.06%.
Key Takeaways
- ✓Open-sourced on Oct 24 under MIT: harness, experiment launch scripts and reproduction guide at microsoft/Agensh.
- ✓Authors report: on the 5 hardest ProgramBench tasks (GPT-5.6-sol high, 6h budget, no Internet), mean final test-pass rate rises from 19.31% with 1 agent to 28.78% with 128 agents, about 49% relative.
- ✓Authors report: on pandoc, 1 to 128 to 1,024 agents moves the pass rate from 33.89% to 50.94% to 55.06%.
- ✓Coordination runs through Gitea (shared workspace), Mattermost (messaging) and a shared-context board adapted from DeLM; each worker uses the Copilot harness agent loop.
- ✓The release ships a single-node Docker Compose team setup plus a single-agent baseline, both on native Copilot ACP sessions.
Key Decision Metrics at a Glance
Turn your technical choice into a development budget
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
Most multi-agent coding harnesses rely on a central orchestrator to assign work, and that orchestrator caps how far a team can scale. Microsoft Research posted the Agensh preprint (arXiv 2609.26781) on Sep 22 and open-sourced the code on Oct 24. This is an update of our September story: some mechanisms and figures in the earlier version could not be traced to the paper or repo and have been rewritten from official sources.
Architecture Highlights & Internals
Agensh has no central orchestrator. Every worker runs the same loop: gather context, claim and self-assign a sub-task, act, verify, and merge progress asynchronously until the goal is met. Three pieces of infrastructure support it: Gitea as the shared workspace for proposed, ongoing and completed work; Mattermost as the message interface; and shared context for reusable findings and work intentions, adapted from DeLM. The paper reports that peer coordination, integration workflows and specialized roles emerge as the team grows.
Authoritative Benchmarks & Measured Scores
All figures are author-reported with no third-party reproduction yet. On the 5 hardest ProgramBench tasks (rebuild reference programs from behavior and bundled docs; GPT-5.6-sol high, 6h, no Internet), the mean final test-pass rate rises from 19.31% with 1 agent to 28.78% with 128 agents. On pandoc it climbs from 33.89% to 50.94% (128 agents) and 55.06% (1,024 agents). Larger teams also reach comparable pass rates sooner.
Developer Hands-on Guide
The repo includes a reproduction guide, a team launcher and a single-agent launcher; a Docker Compose single-node setup lets you compare a team against the single-agent baseline. Experiments depend on Copilot ACP sessions and GPT-5.6-sol, and compute or API cost at large scale is not disclosed, so start with small team sizes.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.