
On 2026-11-05 Hyperstition open-sourced Hyperkernel’s first generated megakernels (Hyperserve), with vendor-reported gains versus NVIDIA-published vLLM baselines; Alpha, B300-oriented.
Key Takeaways
- ✓Official: @hyperstition_cc on 2026-11-05; GitHub Hyperstitioncc/Hyperkernel (MIT, Alpha)
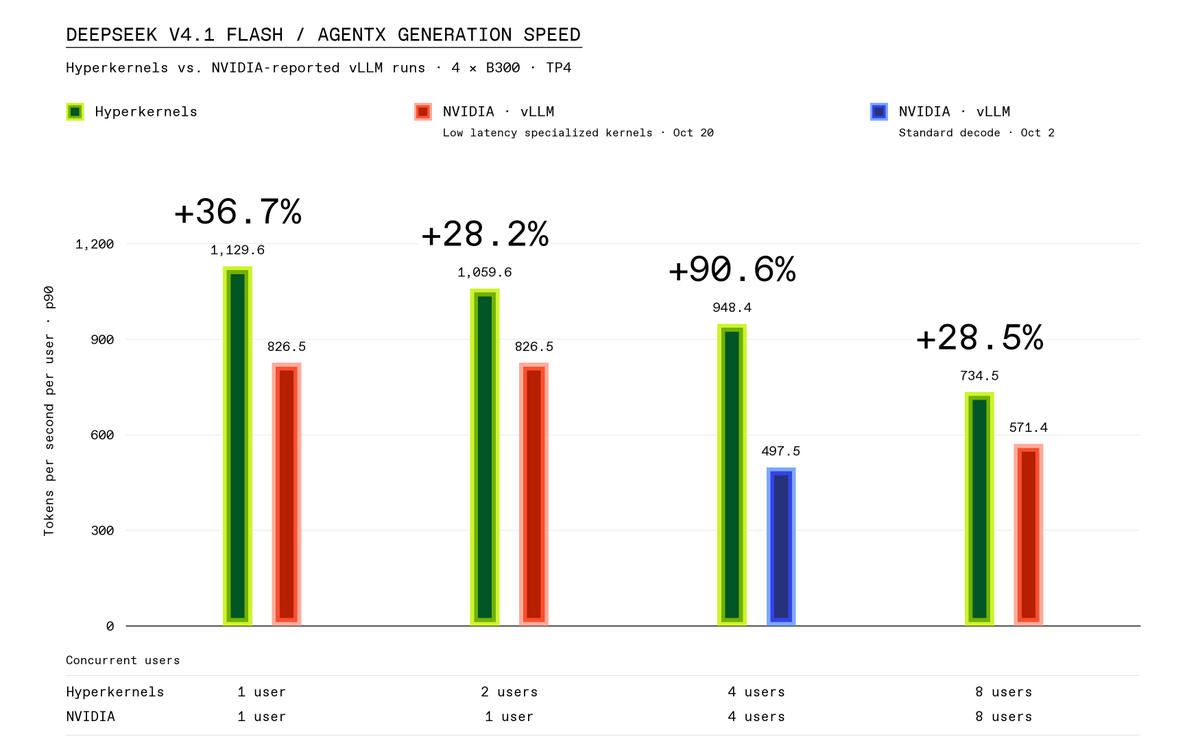
- ✓Vendor claim: DeepSeek v4.1 Flash ~36.7% higher per-user gen at C1 vs NVIDIA-published vLLM; ~90.6% at C4 vs AgentX
- ✓π₀-FAST ~94 vs ~243 ms; Matrix-Game ~37.4 vs ~11.6 FPS (~3.2×)
- ✓CLI: hyperserve llm|drive|dna|world; BYO weights, B300/R580+
- ✓Not independent reruns; full stack + Kimi/GLM serving planned in weeks
Key Decision Metrics at a Glance
Not enough VRAM? Compare cloud API and self-hosting costs
Compare 40 dev plans & simulate token costs vs $20/mo subscriptions
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
Unorthodox GPU workloads often stall on many kernel launches and host sync. On 2026-11-05 Hyperstition open-sourced Hyperkernel, a ~20-day recursive megakernel generator, first shipping generated megakernels (Hyperserve).
Architecture Highlights & Internals
Vendor claim: one launch runs the full forward path; robotics/genomics/voice megakernels generate in under ~50 minutes. CLI: hyperserve <llm|drive|dna|world> for NVIDIA B300, Rust, R580+; bring your own weights. MIT, Alpha.
Authoritative Benchmarks & Measured Scores
Vendor-reported vs NVIDIA-published vLLM (etc.): DeepSeek v4.1 Flash ~36.7% higher per-user gen at C1; ~90.6% at C4 vs AgentX; π₀-FAST ~94 vs ~243 ms; Matrix-Game ~37.4 vs ~11.6 FPS. Not independent reruns.
Developer Hands-on Guide
github.com/Hyperstitioncc/Hyperkernel. cargo build --release, then follow README. Caveats: Alpha, B300-oriented, no bundled weights; full stack + Kimi/GLM serving planned in weeks.
Benchmark side-by-side against alternatives, or calculate monthly token cost vs subscription break-even.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.