vLLM and Ant Group Open-Source Humming: Up to 5x Kernel Acceleration and +43.3% MoE Throughput
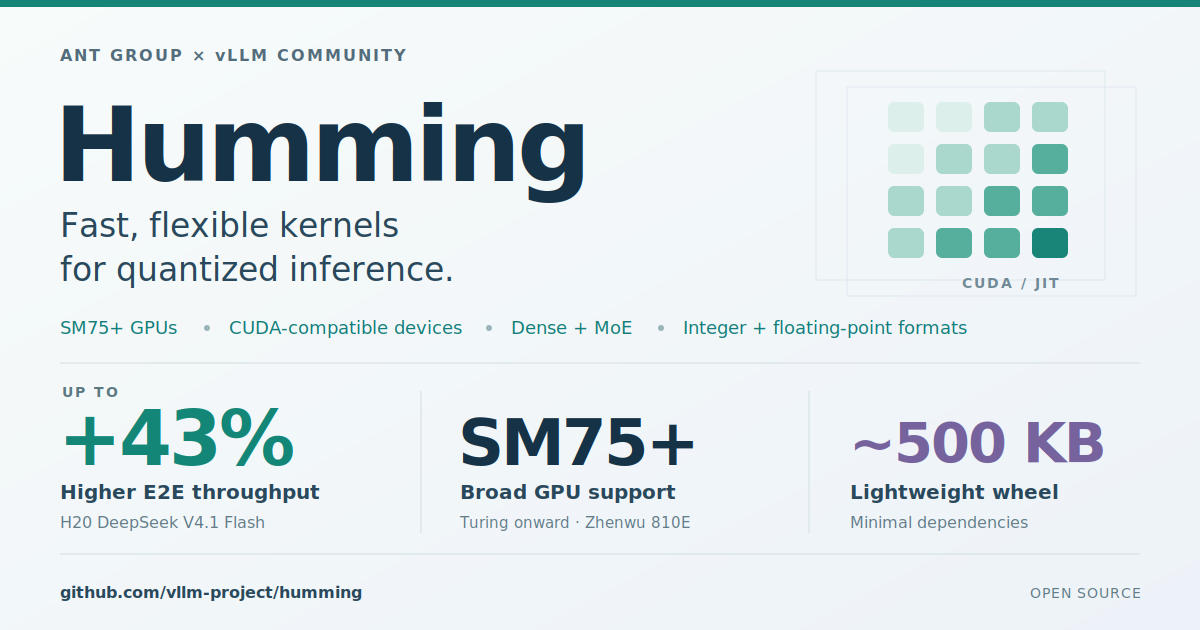
The vLLM project team and Ant Group officially open-sourced Humming (humming-kernels), a specialized high-performance kernel library designed for serving quantized MoE and dense LLMs at massive scale. Humming natively supports WnA16, W8A8, W4A8, and W4A4 across INT1–INT8 and FP4–FP8 formats, spanning NVIDIA architectures from Turing through Blackwell as well as T-Head Zhenwu 810E silicon. In production benchmarks, Humming kernels outpace cuBLAS by 3–4x at small batch sizes and surpass Marlin by 2x on H200 clusters. Serving DeepSeek-V4.1-Flash across 8x H20 GPUs, Humming drives a +43.3% throughput gain under 64 concurrent requests while reducing time-to-first-token (TTFT) by 32%, pre-integrated directly into vLLM v0.29.0+.

Key Takeaways
- vLLM and Ant Group open-sourced Humming (humming-kernels), integrated out-of-the-box into vLLM v0.29.0+
- Covers WnA16, W8A8, W4A8, and W4A4, compiling JIT kernels in just 1.82 seconds versus 23.35 seconds for CUTLASS
- Serving DeepSeek-V4.1-Flash on 8x H20 GPUs yields a +43.3% throughput boost at 64 concurrency (442 to 634 tokens/sec)
- Cuts time-to-first-token (TTFT) by 25% to 32% while delivering up to 5x kernel speedups on Blackwell B300 systems
Linked Models & Agents: