
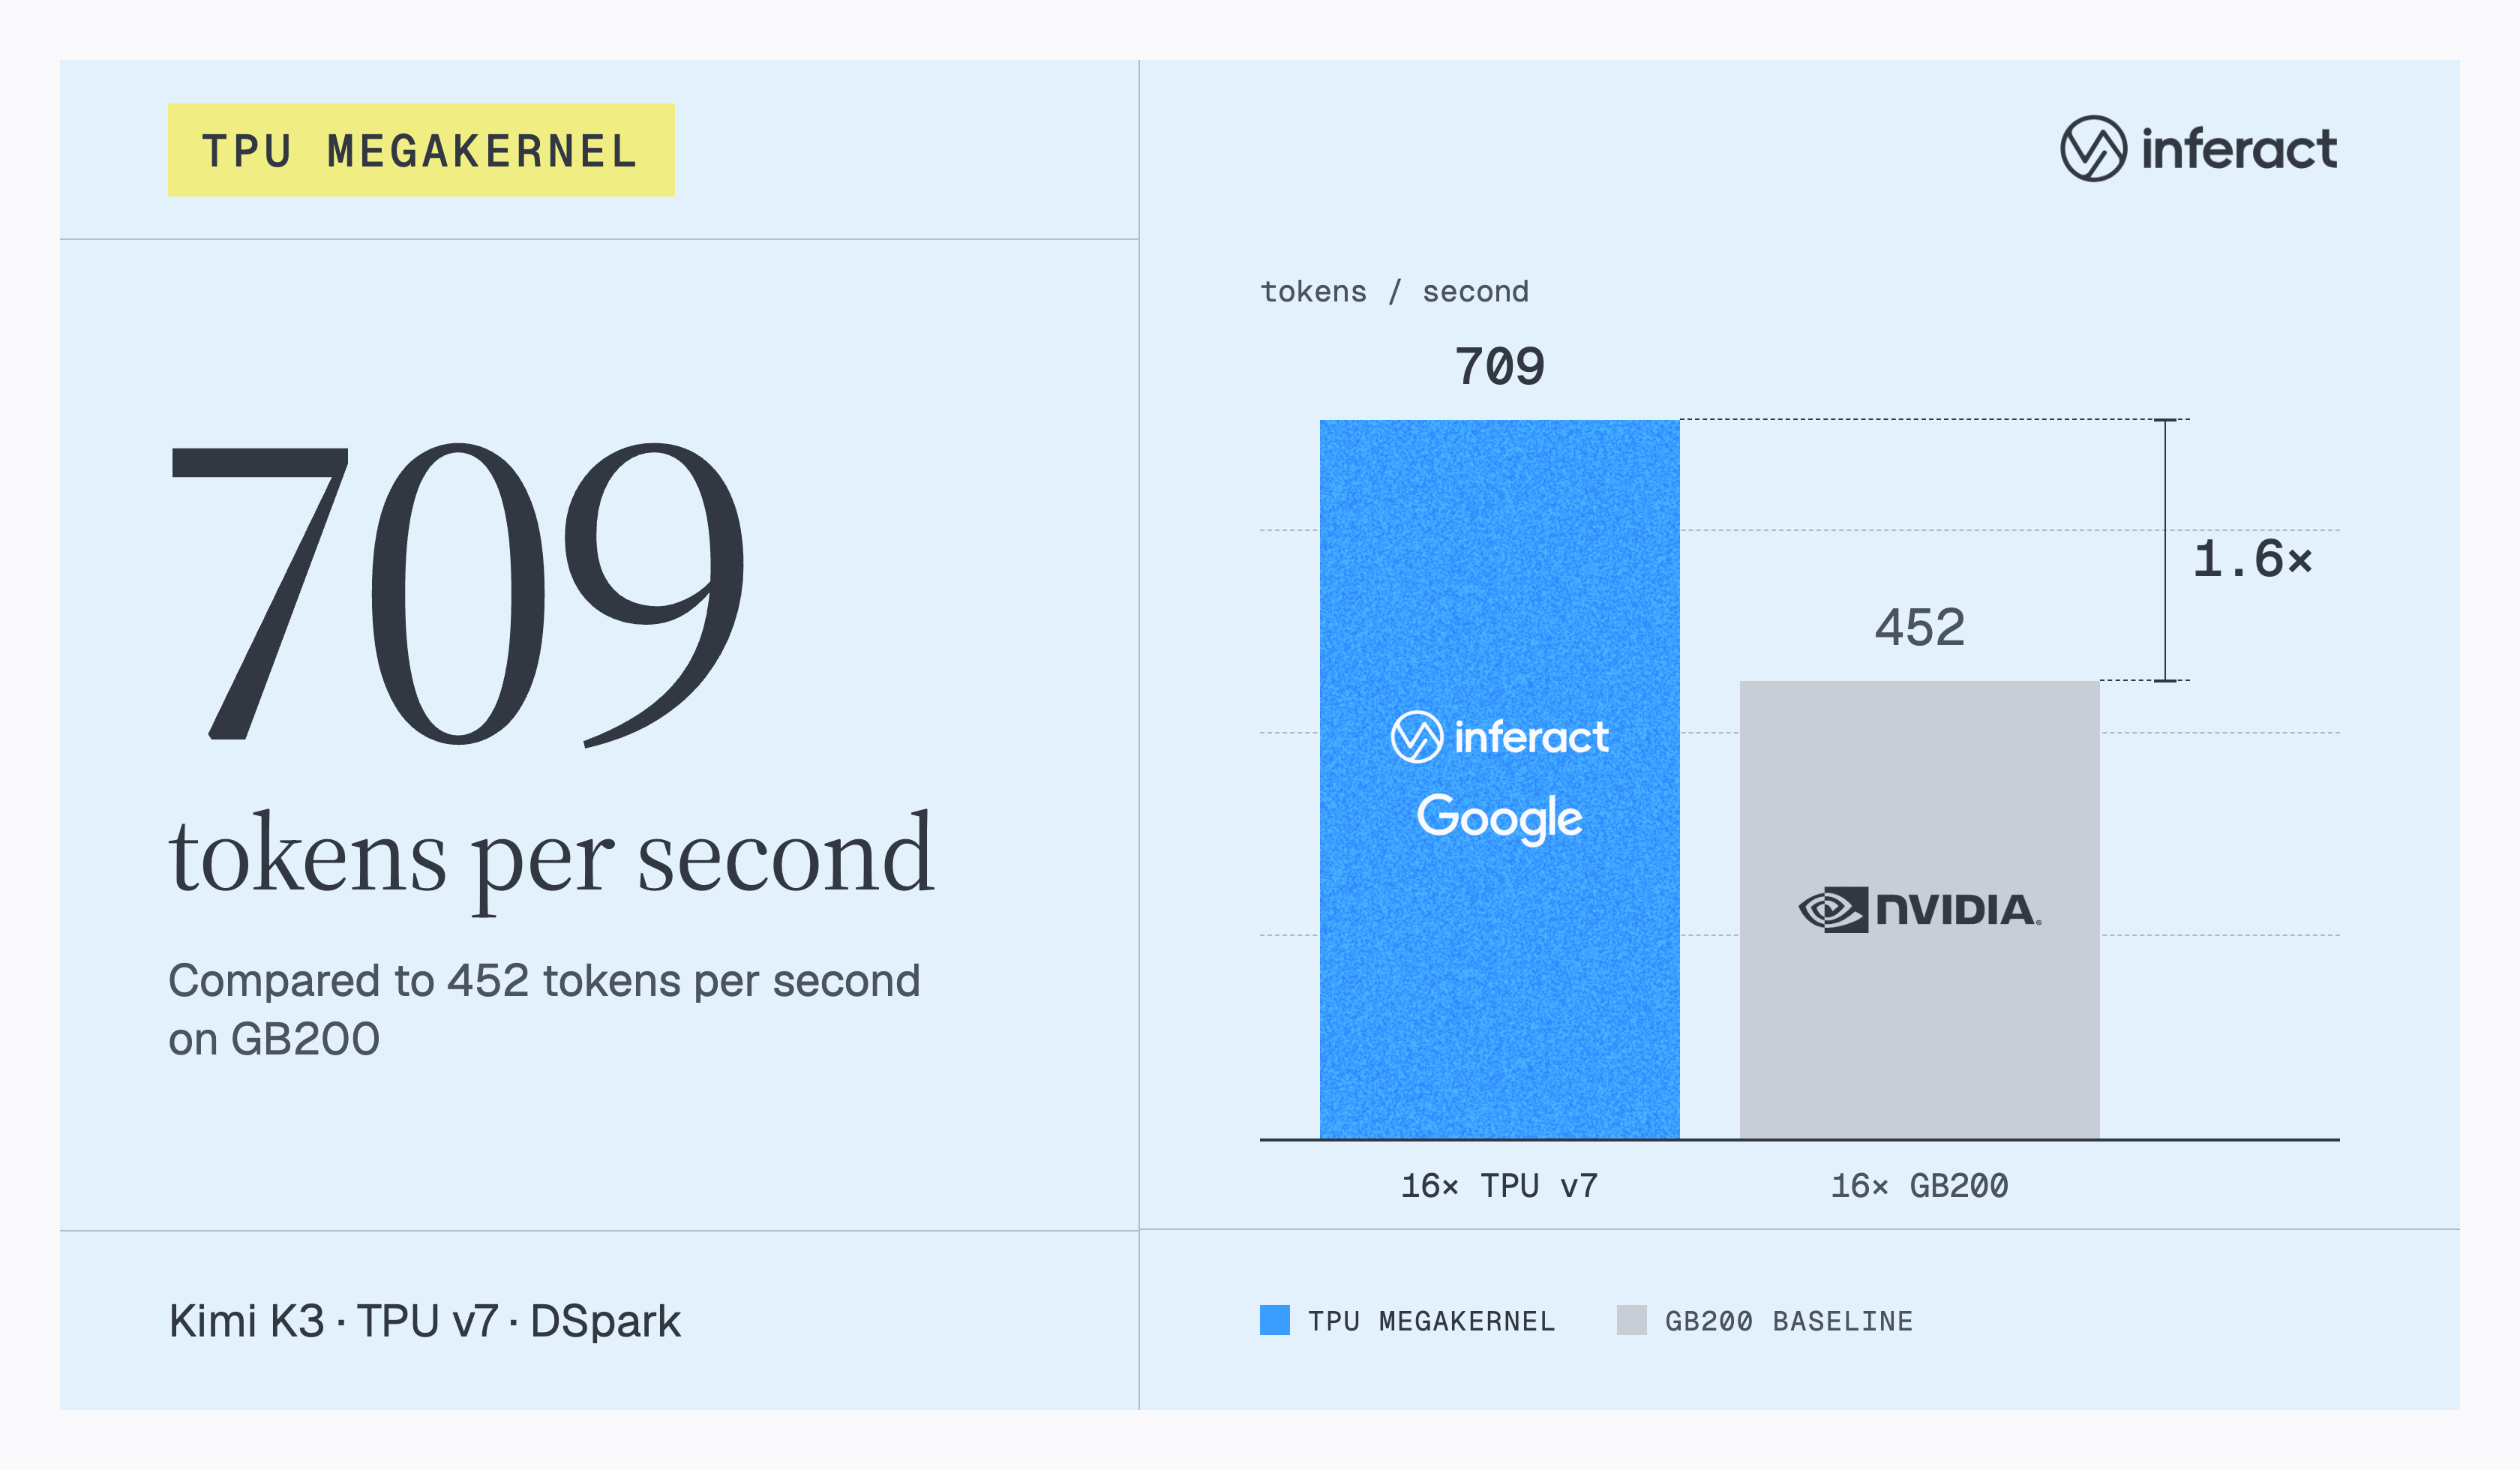
Inferact open-sourced inferact/tpu-megakernels on 2026-09-23: a Pallas megakernel collection for TPU v7. Their blog reports Kimi K3 at 709 tok/s on 16× TPU v7 Ironwood vs 452 tok/s on 16× GB200 under DSpark speculative decoding (acceptance length 6), and roughly 1.4–2× the GB200 baseline at batch sizes 1–8 without speculation. All 92 MoE layers of Kimi K3 run in a single kernel with cross-layer weight prefetch.
Key Takeaways
- ✓Inferact-reported (not independently reproduced): Kimi K3 + DSpark reaches **709 tok/s** on 16× TPU v7 vs **452 tok/s** on 16× GB200 (blog)
- ✓Without speculation: ~**1.4–2×** GB200 baseline at batch 1–8; Qwen 3.8 27B: **1,515** vs **695** tok/s on 4× chips with speculation
- ✓All 92 MoE layers of Kimi K3 run in one Pallas megakernel with cross-layer weight prefetch into VMEM
- ✓Repo: Inferact/tpu-megakernels (Apache-2.0)
Project Links & Resources
Direct AccessIn-Depth Technical Analysis
Core Background & Industry Pain Points
Agentic and chat workloads stress low-concurrency decode, where HBM→on-chip movement and kernel-launch overhead dominate peak FLOPS. Megakernels are hard on GPUs (sync across many SMs); TPU v7’s few compute cores plus large program-managed VMEM fit a single-kernel decode path. Inferact (including vLLM co-creator Woosuk Kwon) open-sourced tpu-megakernels for this niche.
Architecture Highlights & Internals
Per the official write-up, all 92 MoE layers of Kimi K3 run inside one Pallas megakernel, with cross-layer weight prefetch overlapping transfers and compute, targeting TPU VMEM and explicit async pipelines rather than many tiny ops.
Authoritative Benchmarks & Measured Scores
Figures are Inferact’s own, not third-party reproductions, under low concurrency. With DSpark (acceptance length 6): Kimi K3 hits 709 tok/s on 16× TPU v7 vs 452 tok/s on 16× GB200. Without speculation: ~1.4–2× the GB200 baseline at batch 1–8. Qwen 3.8 27B: 1,515 vs 695 tok/s on 4× chips with speculation. Cost/power and high-concurrency curves are not published in the post.
Developer Hands-on Guide
Read the blog, clone Inferact/tpu-megakernels (Apache-2.0) on TPU v7, and compare with vLLM’s GPU Kimi K3 notes (2.8× throughput). Benchmark your own concurrency before production—do not extrapolate the low-concurrency peaks blindly.
Discussion & Comments
0Sign in to join the discussion
Connect with AI developers to exchange benchmark insights.